Category Archives: Meta-Analysis

Closer to Zero Does Not Mean Closer to the Truth — How RoBMA Overcorrects Real Effects

Maier, M., Bartoš, F., & Wagenmakers, E.-J. (2023). Robust Bayesian meta-analysis: Addressing publication bias with model-averaging. Psychological Methods, 28(1), 107–122. https://doi.org/10.1037/met0000405

Take Home Message

A RoBMA estimate near zero is not, by itself, evidence that there is no effect. It is a model-averaged posterior estimate that can be pulled toward zero by the prior for the effect under H1H_1 and then pulled toward zero again by posterior weight on the point-null model. Therefore, a RoBMA estimate near zero does not imply that the true average effect is zero, or even close to zero.

Moreover, if RoBMA also finds substantial heterogeneity, even a true average effect of zero should not be interpreted as evidence that “there is no effect.” It means only that positive and negative population effects balance so that their average is zero. Individual effects may still be substantial. Thus, the point-null hypothesis for the mean is not equivalent to a no-effect hypothesis when effects are heterogeneous.

Finally, model averaging does not guarantee that the resulting average is closer to the truth. It averages estimates from models according to their posterior weights, but all of those models may rely on incorrect or weakly identified assumptions. It is therefore important to examine the estimates from the individual models, the conditional estimate under H1H_1, the posterior evidence for heterogeneity, and the sensitivity of the result to alternative prior specifications rather than interpreting the model-averaged estimate alone.

Introduction

Psychology has been trying for decades to become a real science. However, the replication crisis in social psychology has revealed that the scientific practices of empirical psychologists produce many results that cannot be replicated in later studies (Open Science Collaboration, 2015). The realization that published results are not as robust as they appear has been called the credibility crisis. In response to the credibility crisis, methodologists and meta-psychologists have debated the causes of replication failures and proposed solutions to the credibility crisis.

Some suggestions have produced real change that increases credibility. Personally, I would argue that the sharing of data has been the biggest positive change. Before, researchers would state that data are available on request, but requests often resulted in apologies why the data could not be shared (my dog ate my USB stick). Now it is expected and sometimes even requested by journals that data are shared openly. That makes it possible to find errors in the statistical analyses and occasionally even evidence of data tampering. However, when open data reproduce the original result, it still remains unclear what the data tell us about a particular hypothesis or theory. The reason is more complex and rooted in the problem that many psychological effects are weak and that studies often have large amounts of sampling error. Sampling error simply means that random factors influence the results and a new sample would produce different results. Although this problem is not new or specific to psychology, it remains unsolved. That is, the same data can be analyzed with methods that produce different answers. One method may conclude that the data support a hypothesis and another one leads to the opposite conclusion. The main problem is that empirical researchers often lack the training (and motivation) to understand why different methods produce different results.

Nil Hypothesis Testing Is Wrong

The reason why different models produce different results with the same data is that they make different assumptions about the data and that they answer different questions. The problem is that researchers have a simple question (e.g., how much does listening to music during studying decrease test performance,” but there is no simple way to answer this question. Statistical methods answer questions that can be answered and researchers then report these answers as if they answered the actual question.

This indirect approach of drawing inferences from data is enshrined in the nil-hypothesis ritual that still dominates psychology. After allocating students to a condition with music or no music, the means are compared and the sampling error (standard error) is computed. The ratio of the two is used as a measure of how compatible the data are with the nil hypothesis that there is absolutely no difference. Exactly zero, zip, nada. If the test statistic is above a conventional criterion value, the nil hypothesis is rejected in favor of the conclusion “Music influences learning!” This ritual has been criticized more often than anybody can count and it doesn’t even tell us whether music increases of decreases performance. It just says, the effect is not nil (zero). Let’s say, the sign is negative. However, we still do not know how much music decreases performance. Maybe it changes a grade by 1 percentage point, maybe it is 10 percentage points. So, the answer to the question “How much does music decrease performance” is “It is not zero.” The answer is correct, but not the answer we wanted.

Even worse, the answer could be false. Psychologists use a criterion value that produces a false positive result in 5% of all tests in which the nil hypothesis is true; the effect is really exactly zero. An error rate of 5% may seem low, but this does not mean that only 5% of the results reported in textbooks are false. The reason is that textbooks focus on the studies that rejected the nil hypothesis for a good reason. The other studies are simply inconclusive and do not tell us anything about direction or strength of an effect, if we use this statistical approach.

If results are selected because they showed an effect, it remains possible that all of the published results are false rejections of a hypothesis. This is not just a hypothetical concern. Some people have argued that published studies report more false results than true results.

In conclusion, the most widely used statistical approach in empirical psychology makes it possible that most published results are false, and the replication crisis suggested that false positives contribute considerably to replication failures.

Bayesian Salvation?

The credibility crisis created an opportunity for Bayesian statisticians who had long criticized nil-hypothesis significance testing. One attraction of Bayesian hypothesis testing is that it promises something conventional significance testing cannot provide: evidence in favor of the nil hypothesis. A nonsignificant pp-value does not tell us that the nil hypothesis is true. A Bayes factor, in contrast, can compare a model in which the effect is exactly zero with a model in which the effect can take other values.

This sounds like progress. If psychologists have produced too many false positive results, a method that can distinguish evidence for an effect from evidence for no effect seems useful. The problem is that the ability to produce evidence for the nil hypothesis does not guarantee that the evidence is correct. Just as significance testing can falsely reject a true nil hypothesis, Bayesian hypothesis testing can favor a false nil hypothesis.

Whether this happens depends on the assumptions built into the Bayesian models and their priors.

The Problem of Priors

Bayesian statisticians are aware that prior assumptions influence their results, and they are usually explicit about this. However, the terminology can be misleading to users who are not Bayesian statisticians. Some priors are described as “objective” priors. In everyday language, objective sounds as if the prior is neutral and does not influence the result. That is not what the term means.

An objective prior is better understood as a conventional prior that was chosen without considering the specific subject matter. In this sense, it is similar to using an alpha level of .05 in significance testing. Researchers do not choose .05 because there is something special about their particular hypothesis that makes .05 appropriate. They use it because it has become a convention. Likewise, an objective prior is typically based on a general rule that can be applied across many different research questions.

But standardized does not mean neutral. The prior is still an assumption, and it can influence the result. Different priors applied to the same data can produce different posterior estimates and different conclusions. There is nothing mathematically wrong with this. It is an intended feature of Bayesian statistics. The problem arises when results are presented as if they were produced by the data alone.

A Bayesian result is always conditional on both the data and the prior assumptions used to interpret them. Thus, “objective” does not mean “assumption-free.” It means that the assumption was chosen by a general convention rather than by considering the particular phenomenon being studied.

This is similar to other potentially misleading terms in statistics. “Statistically significant” does not mean that an effect is important. In the same way, an “objective prior” does not mean that the prior has no influence on the result. The technical meaning may be clear to statisticians, while the everyday meaning encourages users to infer more than the term actually implies.

The criticism developed here is therefore not a criticism of Bayesian statistics in general. Bayesian statistics allows researchers to use many different priors, including priors informed by substantive knowledge. The concern is what happens when conventional priors are used without considering whether they make sense for the research question at hand.

One particularly important choice is whether one specific value should receive special prior probability. In Bayesian hypothesis testing, that value is often zero. A model in which the effect is exactly zero is compared with a model in which the effect can take a range of other values. This makes it possible to do something that conventional significance testing cannot do: provide evidence in favor of a nil hypothesis.

That sounds like an important improvement. A nonsignificant p-value does not provide evidence that the effect is zero, whereas a Bayes factor can favor a model in which the effect is fixed at zero.

But this advantage creates the possibility of the opposite error. Conventional significance testing can falsely reject a true nil hypothesis. Bayesian hypothesis testing can favor the nil hypothesis when the true effect is not zero.

Suppose, for example, that psychotherapy has a small positive average benefit. A Bayesian analysis could nevertheless favor a model in which the average effect is exactly zero. The calculation may be mathematically correct, while the conclusion is wrong because the prior and model assumptions were poorly suited to the problem.

Before the credibility crisis, psychologists were highly concerned about low statistical power and failures to detect real effects (Cohen, 1994). More recently, attention has shifted heavily toward false positive results. Both types of error matter. A method that reduces false positives by substantially increasing the risk of falsely concluding that real effects are absent is not necessarily an improvement.

The important question is therefore not whether Bayesian statistics is better or worse than conventional significance testing. The important question is how strongly the conclusion depends on the prior assumptions that were chosen and whether those assumptions make sense for the research question.

This issue becomes especially important for Robust Bayesian Meta-Analysis because its default analysis gives zero a privileged role in more than one way.

Meta-Analysis

Disagreement among statisticians often focuses on the problem of drawing conclusions from a single study. How much did racism and sexism influence the outcome of the 2024 U.S. presidential election? A single study cannot provide a definitive answer, and we cannot repeat the election under identical conditions.

Psychologists are often in a better position because many of the effects they study can be examined repeatedly. Does psychotherapy work? This question has been studied for decades and will continue to be studied. So, it may seem that we can simply combine the results of all available studies in a meta-analysis and get a better answer.

Unfortunately, combining many studies is not as simple as it sounds.

The first problem is that effects vary. Psychotherapy may work differently for different disorders, treatments, populations, therapists, and circumstances. There is therefore no single effect size that describes every situation. At best, a meta-analysis can estimate the average effect and how much effects vary around that average.

The second problem is publication bias. Studies with positive or statistically significant results are more likely to be published than studies with negative or inconclusive results. As a result, the published literature can give an exaggerated impression of the average effect.

This problem was largely ignored for many years, and traditional meta-analyses sometimes produced inflated effect-size estimates, including apparently impressive evidence for implausible phenomena such as extrasensory perception. In response, statisticians have developed a variety of methods that try to detect publication bias and estimate what the average effect might have been if all studies had been available.

Unfortunately, this is a difficult problem. Simulation studies show that publication bias can be hard to detect, especially when it is modest. More importantly, different correction methods can produce very different answers from the same data. One method may estimate an average effect of zero, while another estimates an effect of .20.

The reason is that the methods make different assumptions about how studies came to be published and about the distribution of the missing results. When those assumptions are approximately correct, a method may recover the true effect reasonably well. When they are wrong, the estimate can be badly biased.

The crucial difficulty is that the missing studies are, by definition, missing. The observed data often contain too little information to determine which assumptions about the missing results are correct. Consequently, publication-bias adjustments are not simply estimates produced by the data. They are estimates produced by the data plus assumptions about the data we do not see.

Properly interpreted, the results are therefore conditional: “If the assumptions of Model A are approximately correct, the average effect is close to zero. If the assumptions of Model B are approximately correct, the average effect is closer to .20.

Robust Bayesian Meta Analysis (RoBMA)

Robust Bayesian Model Averaging (RoBMA) offers a solution to the problem that different meta-analytic models can produce different answers. RoBMA fits many models to the same data, gives more weight to models that receive more support from the data, and then averages estimates across these models.

However, RoBMA can move estimates toward zero in two different ways. First, even models that allow for a nonzero average effect use a prior distribution for the size of that effect. When the data provide weak information, this prior can pull the conditional estimate toward its prior mean. For example, a true average effect of .20 might produce a conditional estimate of only .10 if the prior favors smaller effects.

Second, RoBMA also includes models in which the average effect is fixed at exactly zero. When RoBMA remains uncertain about whether the average effect is zero or nonzero, these models receive posterior weight in the final average. If the conditional estimate from the nonzero-effect models is .10 and the zero and nonzero models receive roughly equal weight, the final model-averaged estimate will be approximately .05.

Thus, a true average effect of .20 can first be reduced to .10 by the prior within the nonzero-effect models and then reduced again to .05 by averaging this estimate with models that fix the average at zero. Both steps are mathematically legitimate Bayesian operations. But neither step guarantees that the estimate is moving closer to the true value.

This procedure produces a single number, but it does not make disagreement among the models disappear. If one plausible model produces an estimate near zero and another produces an estimate near .20, this disagreement tells us that the answer depends strongly on assumptions. Averaging the estimates does not resolve that problem. Adding further weight to models that fix the average at zero may move the final estimate closer to zero, but there is no reason why closer to zero must mean closer to the truth.

RoBMA therefore does not eliminate the uncertainty created by conflicting models. It summarizes this uncertainty by averaging across them. The danger is that users may interpret the resulting single estimate as if the disagreement had been resolved. In some situations, the disagreement among individual models is more informative than their average because it reveals how strongly the conclusion depends on assumptions.

Default RoBMA

Default RoBMA gives zero a privileged role in two different ways.

The first prior concerns the size of the average effect when an effect is assumed to exist. RoBMA specifies a distribution of plausible effect sizes, and the default distribution is centered at zero. Before seeing the data, small effects are therefore considered more plausible than large effects, with positive and negative effects treated symmetrically. When the data contain strong information about the average effect, this prior has little influence. When the data contain weak information, however, the estimate remains closer to the center of the prior. Thus, even conditional on the assumption that there is an effect, the default prior can move the estimated effect toward zero.

There is nothing inherently Bayesian about centering this prior at zero. A researcher could specify a prior centered at .10, .20, or some other value. The default of zero is a conventional choice made without substantive information about the particular phenomenon being studied. It may be reasonable in some applications, but it is not neutral: changing the center of the prior can change the estimate when the data are weakly informative.

The second prior gives zero an even more privileged role. RoBMA distinguishes between models in which the average effect is estimated and models in which the average effect is fixed at exactly zero. By default, these two possibilities receive equal prior probability.

A 50:50 split can appear neutral because there are two hypotheses and each receives half of the prior probability. But this appearance is misleading. Zero is only one possible value of the average effect. There is no mathematical reason why exactly zero rather than .01, -.01, or .10 should receive a special probability of 50%. We could construct the same Bayesian model with a spike at .10 and give that value half of the prior probability. The resulting model would then be pulled toward .10 rather than toward zero. Bayesian mathematics permits either choice. The reason for privileging zero must therefore come from the substantive interpretation of zero, not from probability theory itself.

One justification for giving zero special status is parsimony. This makes sense for some statistical problems. If a regression coefficient is exactly zero, the corresponding predictor can be removed from the model. The zero coefficient therefore represents a genuinely simpler model: the predictor does not matter.

This logic is much less convincing for the average of heterogeneous effects in a meta-analysis. If some effects are positive and others are negative, an average of zero does not mean that nothing is happening. It merely means that the positive and negative effects cancel on average. Treating this as a no-effect model would be like calculating the average regression coefficient across many predictors, finding that the positive and negative coefficients average to zero, and concluding that all of the predictors can be ignored.

Thus, even if a point mass at zero can be justified for a single effect or a single predictor, the same parsimony argument does not automatically justify giving special status to a zero average when the individual effects vary.

Nor is there empirical evidence that the average effects studied in psychology have a 50% probability of being exactly zero. The 1:1 prior is a conventional default, not an empirical estimate of how often nil hypotheses are true. Other prior probabilities can be chosen, but there is no generally accepted value that follows from the data themselves.

More importantly, a prior probability for the nil hypothesis is not needed simply to estimate the average effect size. It is needed because RoBMA also asks a categorical question: should the data be attributed to a model in which the average effect is exactly zero or to models in which the average effect is allowed to differ from zero?

These are different questions. Researchers may want to know whether the data discriminate between a point-null model and an alternative model. But the usual goal of a meta-analysis is more straightforward: What is the best estimate of the average effect, and how uncertain is that estimate?

The distinction matters because the answer to the categorical question feeds back into the reported model-averaged effect size. If RoBMA remains uncertain about whether the average is exactly zero, posterior probability remains on the zero model. The conditional estimate from the models that allow an effect is then averaged with zero. Consequently, uncertainty about whether the nil hypothesis is true becomes additional shrinkage of the estimated effect toward zero.

This means that two different prior assumptions can work together. The prior for the size of the effect can pull the conditional estimate toward zero, and the prior probability assigned to the point-null model can then pull the model-averaged estimate toward zero again.

Neither operation is mathematically incorrect. But neither guarantees movement toward the truth.

A Simulation Example

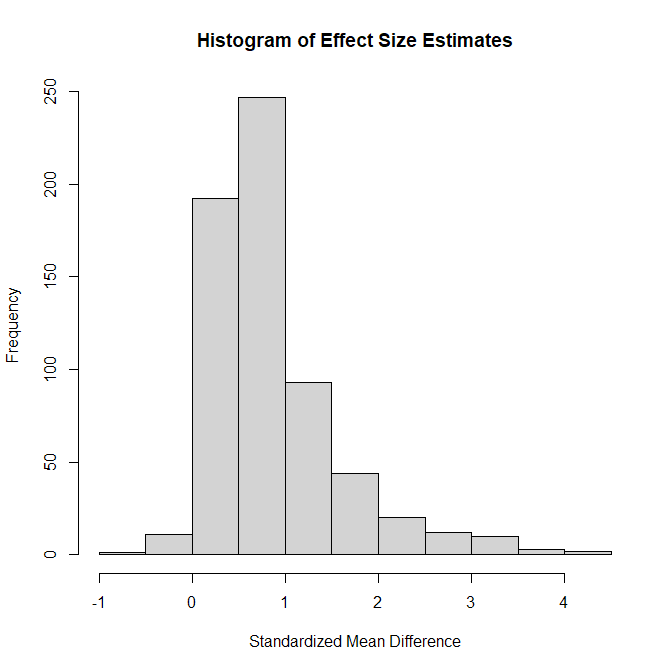
Many meta-analyses in psychology show small average effects together with substantial heterogeneity (van Erp et al., 2017). I used a simple simulation to examine whether RoBMA can produce false evidence for the nil hypothesis under these conditions.

True effect sizes were drawn from a normal distribution with an average effect of d=.20d=.20 and a standard deviation of .40. Thus, the true average effect was clearly nonzero, but individual effects varied widely and could be either positive or negative.

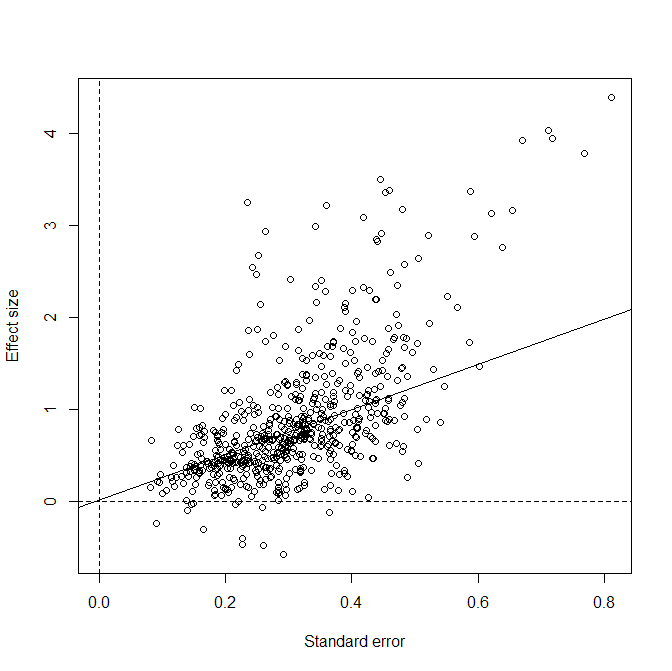
Rather than simulating particular sample sizes, I simulated the standard error of each study directly from a uniform distribution ranging from .05 to .30. True effect sizes and standard errors were independent.

This setup deliberately satisfied two important assumptions of models included in RoBMA. First, true effect sizes followed a normal distribution, which is the population distribution assumed by the random-effects selection models. Second, true effect sizes were independent of their standard errors, so there was no genuine small-study effect of the kind modeled by PET and PEESE.

Publication bias was introduced in a particularly simple way. Only studies with positive observed effect sizes were retained. There was no additional selection for statistical significance and no p-hacking. Selection depended only on the direction of the observed effect.

This form of publication bias is directly relevant to RoBMA because its step-function selection models can include a cutoff at p=.50p=.50, allowing studies with effects in one direction to have different publication probabilities from studies with effects in the opposite direction. Thus, the simulation did not confront RoBMA with a form of selection that lies outside the model space.

Ironically, the model designed to handle directional selection is central to the problem examined here. Given a normal distribution of heterogeneous effects, an observed literature containing only positive results implies that negative results are missing. RoBMA therefore has to reconstruct the unseen negative part of the distribution.

The difficulty is that the observed positive studies do not uniquely determine where the center of the complete distribution lies. A population centered at .20 with substantial heterogeneity and many missing negative results can generate the observed data. But a population centered much closer to zero, combined with a somewhat different amount of directional selection, can also fit the observed positive tail. Because RoBMA includes models that fix the average effect at zero and gives these models positive prior weight, this ambiguity can move the model-averaged estimate toward zero even when the true average is .20.

This is the key identification problem. The data contain a great deal of information about the studies that were observed, but much less information about the studies that were not observed. As a result, RoBMA can remain uncertain about the true average even when hundreds of studies are available.

That uncertainty creates room for the priors to matter. The prior under the alternative hypothesis can pull the conditional estimate toward its own center, and the separate point-null prior can then pull the model-averaged estimate toward zero again.

The simulation is therefore intentionally favorable to RoBMA in several respects. The true effect distribution is normal, there is no relationship between true effect sizes and standard errors, there is no p-hacking, and the publication process consists of simple directional selection that RoBMA explicitly allows for. Nothing in this setup would lead an applied researcher to expect that default RoBMA should frequently provide evidence for an average effect of exactly zero when the true average effect is d=.20d=.20.

Simulation Results

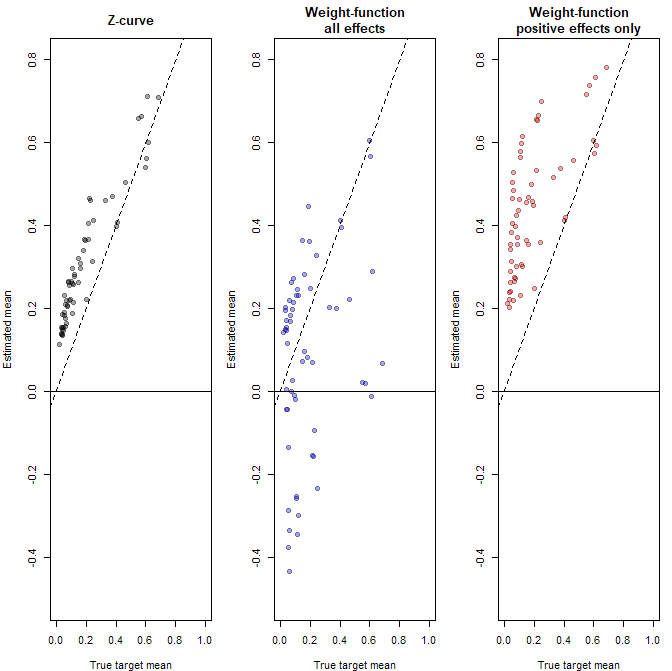
Across 100 simulations, the average RoBMA estimate of the average effect size was only d = .065, although the true average was d=.20d=.20. All credible intervals included zero, whereas only 81% included the true value of .20. Thus, the intervals consistently treated zero as plausible, while failing to include the true effect in 19% of the simulations. The uncertainty intervals therefore do not provide convincing evidence for the true effect and are clearly shifted toward zero.

RoBMA also reports Bayes factors that compare models in which the average effect is exactly zero with models in which it is not. Bayes factors are continuous measures of evidence and do not require a decision to accept or reject the nil hypothesis. In practice, however, conventional cutoffs are often used to describe evidence as favoring one hypothesis or the other. A Bayes factor greater than 3 is commonly interpreted as moderate evidence.

Using this criterion, RoBMA found moderate evidence for a real average effect in only 6% of the simulations. More importantly, it found moderate evidence for the false hypothesis that the average effect was exactly zero in 31% of the simulations. Thus, RoBMA did more than remain uncertain about a small true effect. In about one third of the simulations, it provided evidence in the wrong direction.

RoBMA can also report a conditional estimate that excludes models in which the average effect is fixed at zero. Across simulations, this conditional estimate averaged d = .130. Thus, even within models that assume an effect exists, the estimate had already been pulled substantially from the true value of .20 toward zero.

The default model-averaged estimate was still lower, because RoBMA further down-weights the conditional estimate according to the posterior probability that an effect exists. On average, this posterior probability was only about 40%, below its prior value of 50%. The average model-averaged estimate is not simply 0.40×0.1260.40\times0.126, because the conditional estimate and posterior probability vary together across simulations. Nevertheless, the mechanism is clear: substantial posterior probability remains on models that fix the average effect at exactly zero, and these models contribute zero to the final average.

The estimate is therefore moved toward zero twice. First, within models that allow an effect, the true average of .20 is reduced to a conditional estimate of .126. Second, averaging these estimates with models that fix the effect at zero reduces the final reported estimate further, to .064.

The different model families reveal an additional problem. When RoBMA is restricted to the step-function selection models, it reproduces the near-zero estimate. When it is restricted to PET/PEESE regression models, however, it produces an estimate of approximately d=.421d=.421.

At first sight, the PET/PEESE estimate may appear to be a severe overestimate because the true average across all effects is .20. But PET/PEESE does not model selection by direction. It only adjusts for the part of the observed effect that is associated with standard error—the small-study-effect pattern that often results from selective publication of statistically significant findings.

In this simulation, selection was based on direction rather than significance: only positive observed effects were retained. This selection induced only a small correlation between effect size and standard error, about r=.07r=.07. The mean observed effect among the selected studies was approximately d=.44d=.44, whereas the mean true effect among those selected studies was approximately d=.39d=.39. PET/PEESE detected the small association with standard error and reduced the estimate slightly, from .44 to .42. Thus, under this selection mechanism, PET/PEESE effectively estimates the average effect among the surviving positive studies rather than reconstructing the mean of the complete population.

The contrast between the model families is therefore striking. The step-function models produce an estimate close to zero, whereas PET/PEESE produces an estimate around .42. These are not simply two noisy estimates of the same quantity. They reflect fundamentally different assumptions about what happened to the missing studies and, in this simulation, effectively refer to different quantities.

Ironically, an equal arithmetic average of the step-function estimate of about .06 and the PET/PEESE estimate of about .42 would be approximately .24, close to the true value of .20. But this would be an accident, not a meaningful solution. Nobody is interested in the average of the mean across all effects and the mean among only the positive effects.

RoBMA did not average these two estimates equally. It assigned essentially zero weight to the PET/PEESE models and therefore reported an estimate dominated by the step-function models. The fact that this estimate happened to be much farther from the truth than the PET/PEESE estimate illustrates an important limitation of model averaging: giving more weight to one model does not guarantee that its estimate is closer to the true value.

In sum, this example demonstrates two distinct problems. First, RoBMA can provide evidence that the average effect is exactly zero when the true average is a small positive effect. Second, averaging across models with different assumptions does not guarantee a more accurate or even a more meaningful estimate. In this case, the disagreement between estimates of approximately .06 and .42 is itself important information. It reveals how strongly the answer depends on assumptions about the missing studies. Averaging that disagreement away does not resolve the uncertainty.

Alternative Solution: Mindful Meta-Analysis

RoBMA was developed to address a real problem: different methods for correcting publication bias can produce dramatically different answers from the same data. This blog post shows why automatically averaging these answers does not solve the problem. The models disagree because they make fundamentally different assumptions about how the observed data were generated and about the results that were not observed. Combining their estimates into a single number does not resolve these disagreements. It can merely hide them behind an algorithmic average.

This is similar to the problem Gigerenzer identified in the ritualistic use of nil-hypothesis significance testing. The problem was not the mathematics of significance testing. It was the replacement of scientific reasoning by an automatic procedure: calculate a p-value, compare it with .05, and report the appropriate conclusion. Replacing this ritual with another automatic procedure—fit many Bayesian models, average them, and report one number—does not solve the fundamental problem. Data analysis requires researchers to think about what their models assume and what question they are trying to answer.

In this example, asking about the true average for a hypothetical population of effect sizes that includes negative values when only positive values are observed is the wrong question. The same positive distribution could arise in a fundamentally different way. Imagine that effects were generated directly from a distribution that contained only positive values. No negative results would have been suppressed because no negative effects ever existed. The observed data could look essentially the same, but reconstructing a large number of hypothetical negative results would now be wrong.

This is the fundamental identification problem. From the observed positive results alone, the model cannot know whether negative results once existed and were suppressed or whether the population that generated the data simply contained few or no negative effects. The answer comes from assumptions about the missing part of the distribution, not from direct observation.

In this specific case, a more meaningful question is whether the positive observed results all tested a true nil hypothesis, which is already rejected by the large estimate of heterogeneity that implies at least some of the positive results were obtained with real effects. In this case, the PET-PEESE estimate actually provided the correct answer about the average effect size of the observed results. In contrast, users who focus on the average estimate of RoBMA might arrive at the false conclusion that the true effect size is zero, which ignores the evidence of heterogeneity. When studies are heterogeneous, there is no single effect size to estimate. Thus, even the misleading estimate of zero would require further examination of the positive results as a next step.

In conclusion, meta-analysis requires a lot more thinking than published meta-analyses that focus on the average effect size estimate imply. The devil is not only in the defaults of meta-analytic models, it is also hidden in large estimates of heterogeneity that remains unexplained. If mindless use of p-values got us into the mess, mindless use of Bayesian model averages is not going to get us out of it.
It is OK to be a WEIRD science

It Is Fine to Be WEIRD

Americans love acronyms, and none has traveled further in social psychology than WEIRD — Western, Educated, Industrialized, Rich, and Democratic — coined to criticize a discipline for building a science of humanity out of American undergraduates. The critique was fair, but it points in the wrong direction. Being WEIRD is not the problem. It is perfectly legitimate for WEIRD researchers, paid by WEIRD institutions, to study WEIRD people in order to help WEIRD societies — to ask whether a therapy relieves depression in a Western clinic even if it would do nothing in another culture, or even if the disorder as we define it barely exists there. Local knowledge is not lesser knowledge.

The problem is not being WEIRD. It is being WEIRD while claiming to be universal — and psychology keeps making that claim because it has never quite decided whether it is a natural science of universal laws or a social science of particular societies. This essay is about that confusion, the two rituals that keep it in place — the apologetic limitations paragraph and the meta-analytic average that pools everyone into a number belonging to no one — and what becomes possible once we accept that it is fine to be WEIRD.

Philosophy with p-values

Psychology was born from philosophy but wanted to be physics. It took philosophy’s questions — how we perceive, learn, remember, decide — and set out to answer them with the methods of the natural sciences: experiment, measurement, and laws that hold for everyone. Call it philosophy with p-values. For the questions it started with, this worked reasonably well. Basic perception really is close to universal. A Weber fraction measured in Leipzig is likely to look much the same in Toronto; basic visual processes do not change dramatically from one culture to another. In the laboratory of basic processes, one human is often interchangeable enough with another that findings can generalize broadly.

That success was a trap. It made universality the price of admission to scientific psychology: if your findings held for everyone, everywhere, you were doing real science; if they did not, you were doing something softer and less scientific. The standard was manageable while psychology studied processes that are, in fact, close to universal. It became a problem when psychologists turned to everything else — love, prejudice, persuasion, the self — and kept the same standard.

There are two ways to apply a universal method to a variable subject. The first is to deny much of the subject matter. Behaviorism largely did that: mind, meaning, and emotion were pushed aside in favor of observable stimulus and response, which could be studied in a more law-like fashion. Whatever would not fit the method was ruled unscientific and shown the door.

The second way survived behaviorism and is the one we still practice. Instead of changing the questions, we changed the way we studied them. Social psychology adopted the model of the experimental laboratory — controlled experiments, manipulations, deception, participants reduced to “subjects” — so that social life could be studied as though it, too, obeyed general laws.

What psychology was reluctant to consider was another possibility: that the study of social behavior might be a different kind of science, with standards of its own and no need to discover universal laws.

Biology shows that this was a choice, not a necessity. It is a natural science with genuinely universal principles, and no one doubts its scientific credentials. Yet while reproduction is universal, how organisms reproduce varies enormously, and it would be absurd to insist on one detailed theory of sexual behavior spanning salmon, praying mantises, and swans. Biology does not apologize for this. It allows general evolutionary principles to coexist with the study of particular species and ecological contexts. The second does not have to dissolve into the first to count as science.

The False Promise of Experimental Social Psychology

The first challenge to universality came from studies within WEIRD cultures showing that people behave differently in the same situation. Walter Mischel’s Personality and Assessment (1968) argued that behavior could not be predicted very well from broad personality traits. Social psychologists pushed this argument further. Ross (1977) called the tendency to explain behavior in terms of personality while underestimating the situation the fundamental attribution error, and Ross and Nisbett (1991) went so far as to write that “one cannot predict with any accuracy how particular people will respond.” In this way, the search for universal laws of behavior could continue. Personality psychologists marshalled evidence that people really do differ from one another, but experimental social psychology did not respond by making those differences central to its theories. Social psychologists went on manipulating situations in the laboratory and largely treating differences between people as error variance.

The second challenge came from outside the Western laboratory. Beginning in the 1970s and gathering force through the 1980s, cross-cultural psychologists showed that many supposedly universal findings varied systematically from one culture to another — that the mind studied in Michigan was not simply the human mind. In principle, the point was conceded: virtually everyone now agrees that culture shapes cognition and behavior. In practice, much less changed, because studies kept being run in the same few places.

The complaint finally crystallized, decades later, in Henrich, Heine, and Norenzayan’s 2010 article on the “weirdest people in the world” — WEIRD, for Western, Educated, Industrialized, Rich, and Democratic. If anything, WEIRD may make psychology sound more diverse than it was. France is WEIRD, Germany is WEIRD, Sweden is WEIRD, but the standard participant was not drawn from a representative cross-section of Western societies. The empirical base was often much narrower — closer to a WASP monoculture of white, middle-class American college students.

The article was cited everywhere and changed surprisingly little, much like the cross-cultural critique before it. Papers still open with theories stripped of cultural context and test them on WEIRD samples; they simply close, now, with a limitations paragraph acknowledging that the sample was WEIRD and urging further research on other populations — by someone else. The acknowledgment goes in the one section of a paper that rarely changes the interpretation of the findings, and the work proceeds much as before.

And the asymmetry hides in plain sight, even in the names. Other countries mark their journals — the British Journal of this, the Iranian Journal of that — while the journals that set the field’s agenda do not: they are simply Psychological Science or the Journal of Personality and Social Psychology, as if nationality did not apply to them. So an American study in an American journal is readily read as a finding about people, while an Iranian study in an Iranian journal is read as a finding about Iranians. The universality we claim to have renounced still runs underneath — the default setting for one population, and the denial of that status to every other.

So the apology is the wrong response to the right observation. To acknowledge that a sample was WEIRD and then generalize anyway leaves the universalist assumption intact and merely adds a note of caution. The alternative is not to apologize but to specify — to name the population you studied and claim nothing beyond it. There is nothing unscientific about a finding that holds in one society and not another. Whether a result generalizes across cultures is a question to be answered, not a box to be ticked or an assumption to be smuggled in.

Everybody knows that people differ from one another; that does not make anyone weird. What is truly weird is a science of human behavior that ignores this diversity and imagines that behavior can be reduced to a single number — one universal effect of a situation on everyone. The remedy is not complicated: stop making global generalizations and ask instead a specific question about a specific population. Sometimes, in other words, it is perfectly OK to ask a WEIRD question.

Demographic Acronym “WEIRD” Overused in Psychology Research | Psychology Today

The Weirdest Statistical Method: Meta-Analysis

It is widely recognized that many psychological studies cannot provide conclusive evidence for an effect, let alone against one. Sample sizes are often too small to show that a result is more than a statistical fluke, or to pin down how large an effect actually is. The proposed solution is meta-analysis: find all the published studies on a topic and combine them to estimate the average effect size. That average is then presented as the true population effect size.

Pooling does solve the problem it was built for. Combine enough studies and the average becomes precise — the sampling error that plagued each small study shrinks toward zero. But a precise average is worth nothing if the quantity it averages over is not one quantity at all. If the true effect varies from study to study — across populations, procedures, and cultures — then pooling delivers an exact estimate of a number that describes no one. And heterogeneous effects are exactly what psychology’s meta-analyses pool.

To see why that is a mistake, and to see it clearly enough that no one can accuse me of being against averages, forget psychology for a moment and consider the average height of 8 billion human beings on this planet. Suppose it is 165 centimeters. There is nothing wrong with the number. It is correct, it is precisely estimated, and it is the honest answer to a well-defined question: what is the mean of the height distribution over all living people? Now try to use it. Design a doorframe? You do not build to the mean; you build to a high percentile, because the mean is silent about the tail and the tail is the entire point. Manufacture clothing? Here the average is not merely useless but actively misleading, because no one is average on every dimension at once, and a garment cut to the mean neck, mean arm, and mean torso fits no actual body.

So the average can be correct, precise, and useless, all at once, with no statistical error anywhere. The uselessness is not a flaw in the estimate. It is a property of the question. And the question carries a hidden assumption — one no one would defend if asked, and that the practice acts on regardless. Put the claim baldly and it is absurd: that there is a single true value and every individual simply equals it, the variation being error. No one believes that. but in a psychological meta-analysis the same assumption slips through, not as a belief anyone holds but as a convention everyone follows: the pooled effect is written up as the effect, cited as the effect, carried into the next study as the effect — as though the number applied to everybody.

So, to summarize, estimating a single average for a heterogeneous set of objects is a weird question that no one would consider meaningful to ask or to answer. But its weirdness is hidden by the universality assumption — that variation between people is mere error variance, and that the truth is a single number applying to everybody. A meta-analysis of mindfulness therapy illustrates that I am not attacking a strawman, but that the problem is real. I picked this meta-analysis because I am interested in the effectiveness of mindfulness therapy for WEIRD people in Canada. I don’t want to generalize to all other meta-analyses, but it is likely that this is not the only meta-analysis that failed to take cultural differences into account.

Does Mindfulness Therapy Work?

Goldberg and colleagues (2018) set out to answer exactly that question with a meta-analysis of mindfulness-based therapy. They collected studies spanning a range of disorders — depression, anxiety, substance use, and more — conducted in different populations and countries and using different mindfulness protocols, from standardized programs like MBSR and MBCT to local adaptations. They then pooled these studies to estimate average effects. For depression compared with passive controls, for example, the estimated effect was d =.6, with a 95% confidence interval from .5 to .7 — a moderate effect, the kind of number that easily becomes “mindfulness works” by the time it reaches a textbook or a clinician.

But look at the question that average answers — “the effect of mindfulness therapy” — and you will recognize the problem from the previous section. It treats “mindfulness therapy,” without further qualification, as though there were a meaningful effect to be estimated across all of these studies. Yet the studies were not one thing. Mindfulness for chronic pain in an American clinic and mindfulness for depression in a Chinese university are no more the same treatment of the same disorder in the same population than a newborn and an adult are the same height. The pool is heterogeneous by construction — across disorders, populations, and therapies at once. Asking for its single average effect is like asking for the average height of everyone on Earth.

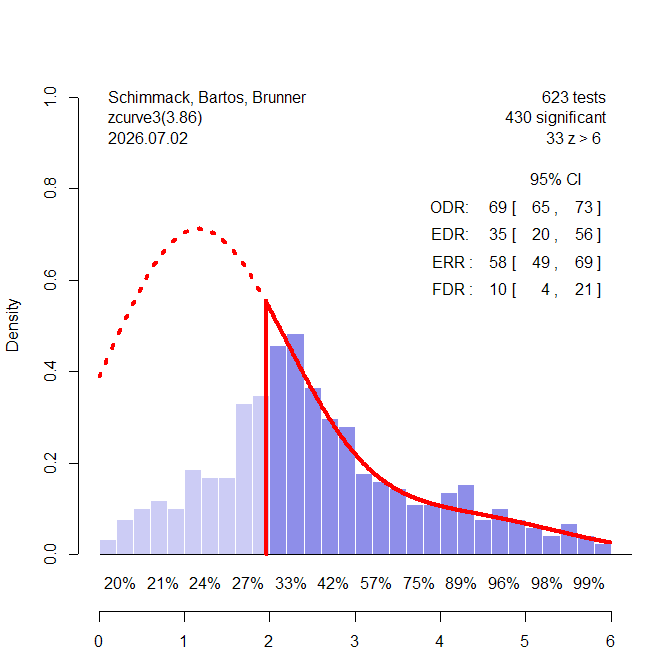
I reanalyzed the open data with z-curve3 (Schimmack, 2026), which is designed to model heterogeneous evidence. The first step is to check for publication bias, and there was little evidence of it — unusual in psychological research, but less surprising in a meta-analysis that includes many nonsignificant results. This means that the full set of 214 positive effect-size estimates can be analyzed without a large correction for selective reporting. The studies were, on average, modestly powered: only about 45% reached significance, reflecting a literature that mixes a few well-powered studies with many underpowered ones.

But the decisive quantity is not the average power or even the average effect. It is the spread. z-curve3 estimates not only the mean true effect but also the distribution of true effects across studies. The estimated mean was .47, reassuringly close to Goldberg’s pooled estimate, with a standard deviation of .29. Those numbers imply a 95% prediction interval from about −.10 to 1.10. In other words, the true effect in another study drawn from this literature could plausibly range from a negligible negative effect to an enormous positive one.

That interval is the data refusing the question. If “the effect of mindfulness therapy” were a single useful quantity, the studies would cluster around it and the interval would be narrow. Instead, it spans almost the entire range of plausible effects.

And this is the point where the argument is often lost, so I want to be precise. The average of .47 is not meaningless. It is the correct answer to a narrow and legitimate question: if you drew another study at random from this same mixture of studies, .47 would be your best single guess for its effect. But patients are not looking to enter a lottery whose prize ranges from a small harm to a large benefit. They want to know whether a particular therapy has been shown to work for their problem and in a population like theirs.

There are, in fact, two problems stacked on top of each other. Even within a single population, an average conceals variation between individuals — some patients improve, some do not. I set that problem aside here because the meta-analytic average fails long before we reach it. It is already an average of different population averages, different treatments, and different disorders. It tells us little about how any particular therapy performs for any particular problem in any particular population. The within-population question is hard. This broader question may not even be well posed.

Goldberg and colleagues (2018) set out to answer exactly that question with a meta-analysis of mindfulness-based therapy. They collected studies spanning a range of disorders — depression, anxiety, substance use, and more — conducted on different populations in different countries, using different mindfulness protocols, from standardized programs like MBSR and MBCT to local adaptations, and pooled them into a single estimate. The headline was encouraging: a standardized mean difference somewhere between .46 and .73, a moderate-to-large effect, the kind of number that has become “mindfulness works” by the time it reaches a textbook or a clinician.

But look at the question that average answers — “the effect of mindfulness therapy” — and you will recognize the grammar from the previous section. It treats “mindfulness therapy,” unconditioned, as one homogeneous thing, an effect that exists and the meta-analysis merely measures. The studies it pooled were not one thing. Mindfulness for chronic pain in an American clinic and mindfulness for depression in a Chinese university are no more the same treatment of the same disorder in the same people than a newborn and an adult are the same height. The pool is heterogeneous by construction — across disorders, populations, and therapies at once. Asking for its single average effect is asking for the average height of everyone on Earth.

Hidden Moderators in Plain Sight

A meta-analyst can fairly say that I have described only half the job. Meta-analysts do not just compute an average; they also look for moderators — study features that predict when the effect is larger or smaller. Culture, dosage, type of control group, severity of the disorder: code each study on these characteristics, then test whether they track the effect sizes. This is the right instinct. If effects vary, find out what they vary with. Sometimes this works. But in psychology it often does not, and the reason is partly built into the way the search works.

A moderator analysis can only find variation associated with variables that were actually coded. You choose the study characteristics, code the studies on them, and ask which ones predict the results. That can reveal an explanation only if two things are true: you thought to measure it, and enough studies differ on it for a pattern to emerge. When the real source of variation is something no one thought to code — an unusual outcome measure, a quality problem, a researcher who strongly favored a particular result — the moderator analysis may come back empty.

Then there is variation that does not correspond to any broad study characteristic at all. Imagine making a smoothie with a dozen different fruits. Suppose it tastes off because of a single rotten blueberry — one study in forty with a broken measure, a p-hacked result, or invented data. There may be no useful moderator for that. “Rotten” is not a dimension along which the studies vary; it is a fact about one study. A moderator is a column in a spreadsheet, while a single unusual study is a row. To understand that study, eventually you have to look at the row.

Psychologists already know the shape of this problem from their own statistical tools. Factor analysis looks for variation that is shared across several measures. A strong relationship between just two variables does not ordinarily define a broad factor and may be treated as something specific to that pair. Cluster analysis asks a different question. If two variables correlate at .9, they can form a tight cluster whether or not they belong to any broader dimension. Moderator analysis resembles the factor approach: it looks for systematic variation along dimensions shared by multiple studies. It is less useful for a small pocket of studies that resemble one another for some idiosyncratic reason, and still less useful for a single unusual study. Those patterns become visible only when we stop looking exclusively at columns and start looking at rows.

In a meta-analysis of treatment effectiveness, however, the rotten blueberries are not the only studies we should be looking for. We also want the opposite — studies that provide especially strong and trustworthy evidence that the treatment works. But finding them is harder than sorting a forest plot by observed effect size. Large effects from small studies are especially vulnerable to sampling error, and extreme estimates are often extreme partly because of luck. Rank studies by the effects you happen to observe and you risk promoting the flukes.

This is where z-curve3 can help. It uses information from the distribution of results to shrink noisy study estimates toward more plausible values, correcting for regression to the mean and selective reporting. From the adjusted estimate it can compute a minimum effect size: a conservative lower-bound estimate of how large the effect could reasonably be after sampling error and uncertainty are taken into account. That makes a different kind of claim from the pooled average. The pooled mean asks for the center of the entire collection. The minimum effect size asks what can be said conservatively about one particular study.

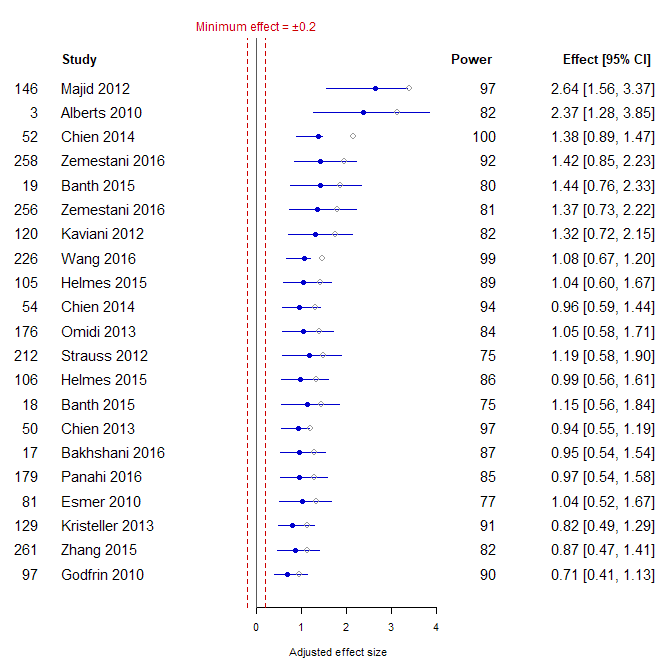
And this brings us back to the blueberry. Moderator analysis asks which characteristics explain differences across studies. The corrected forest plot asks a different question: which individual studies provide the strongest evidence after noisy estimates have been pulled back toward more plausible values? The figure shows those studies, along with an estimate of how likely each result is to reach significance again in an exact replication of the same size. These are the promising fruits for a tasty smoothie. You find them not by blending everything together, and not only by coding broad dimensions, but by looking at the studies one at a time.

Do Western Patients Benefit from Eastern Mindfulness Therapy?

The figure shows a forest plot of the studies with the strongest evidence, sorted by their minimum effect size, from a high of 1.56 down to .41. Each study is identified by its first author and year. Look at which studies produced strong evidence of effectiveness on their own. Names like Majid, Zemestani, Kaviani, Omidi, Bakhshani, Panahi, Zhang, Chien, and Wang are Asian names, and closer inspection of the articles confirms it: these were studies of Asian participants. The strong evidence in this literature comes, overwhelmingly, from Iran and China. The pattern was sitting in the 2018 data; it took a 2021 umbrella review to note, across this body of work, that effects tend to run larger in Asian studies (Goldberg et al., 2021).

Given these results, a meta-analysis that pools all studies tells us nothing about the effectiveness of mindfulness therapy in WEIRD or in non-WEIRD samples. The average is too high for the Western patient, whose studies cluster low, and too low for the Iranian and Chinese patient, whose studies cluster high.

It may seem laudable that the meta-analysis included non-WEIRD samples. But dropping them in the blender is what created the heterogeneity that makes the average useless in the first place. The pooled number tells us nothing about either population on its own — it is an average across both that describes neither. And the fix is not complicated. Before you average a set of studies, you owe one check: do their results scatter by luck alone? If the only thing separating the estimates is sampling error, the studies were plausibly measuring one effect, and the average means something. If they scatter by more than luck — if real differences remain after chance is accounted for — then they were never one thing, and no single number should be reported for all of them.

So do Western patients benefit from Eastern mindfulness therapy? This meta-analysis cannot say. This is not a verdict on mindfulness therapy. It is a verdict on a method. There is nothing weird about studying WEIRD samples, if the question is whether mindfulness therapy helps WEIRD patients. What is weird is to mix populations, discover that the effects vary, and then report the average as if it applied to all of them.

Conclusion

Science is a process. While there are universal criteria that distinguish science from other belief systems, the universal aspect of science is to question itself and to learn from mistakes. This process can take time. Meta-analysis emerged in the 1970s to make sense of inconclusive and sometimes conflicting results in a growing literature of empirical studies. Over time, rules for meta-analyses were formulated. Nowadays, meta-analyses are often considered to be the gold standard to make sense of original studies and meta-analyses are highly cited as authoritative sources to make claims like “Mindfulness therapy works.”

Initial meta-analysis often assumed a single effect size. Over time, methods were developed to examine and quantify heterogeneity in population effect sizes. However, meta-analysts are still trying to figure out how to report heterogeneity and what to with it. This essay points out that heterogeneity in effect sizes cannot be ignored. Studies should be combined to reduce sampling error, but not to hide true variation across populations.

More broadly, psychologists need to become more comfortable to study specific populations rather than claiming that their study tests a universal hypothesis and then apologize for the fact that they studied only US Americans or another WEIRD population. Studies that do want to make universal claims (e.g., Ekman’s research on facial expression) do require cross-cultural data, but not all studies have to test universal hypotheses.

Further Readings

  • Ghai, S. (2021). “It’s time to reimagine sample diversity and retire the WEIRD dichotomy.” Nature Human Behaviour. This is probably the cleanest paper for your purpose. Ghai argues that dividing the world into WEIRD versus non-WEIRD collapses enormous heterogeneity into a binary classification. A sample from India, Nigeria, Chile, and rural China does not become meaningfully similar simply because all are “non-WEIRD.”
    Nature Human Behaviour article
  • Clancy, K. B. H., & Davis, J. L. (2019). “Soylent Is People, and WEIRD Is White: Biological Anthropology, Whiteness, and the Limits of the WEIRD.” Annual Review of Anthropology. This is a deeper conceptual critique. They argue that the individual components of WEIRD are poorly operationalized and that treating inhabitants of “WEIRD societies” as homogeneous erases substantial differences within those societies. Their broader argument is that the label can obscure the actual dimensions researchers need to measure.
    Annual Review article
  • Muthukrishna et al. (2020). “Beyond Western, Educated, Industrial, Rich, and Democratic (WEIRD) Psychology: Measuring and Mapping Scales of Cultural and Psychological Distance.” Psychological Science. This comes partly from the same intellectual tradition as the original WEIRD paper, but it implicitly identifies a major problem with the acronym: cultural variation is better conceived as multidimensional and continuous rather than as membership in two groups. They develop measures of psychological/cultural distance instead.
    Paper information and full-text links
  • Schimmelpfennig et al. (2024). “Methodological concerns underlying a lack of evidence for cultural heterogeneity in the replication of psychological effects.” Communications Psychology. This paper includes Henrich, Heine, and Norenzayan themselves. It explicitly warns against turning the letters of WEIRD into an empirical “WEIRDness” scale. Their point is important: WEIRD was originally a mnemonic/consciousness-raising device, not a theory of which cultural dimensions cause psychological variation. They criticize binary coding and mechanically decomposing countries according to the five letters because this produces classifications with poor theoretical and face validity. Open-access article
  • Jeffrey Sherman’s “There Is Nothing WEIRD About Basic Research: The Critical Role of Convenience Samples in Psychological Science” in American Psychologist (published online 2024; print 2025). Sherman accepts that psychology has a diversity problem, but challenges the inference that every study therefore requires culturally representative or highly diverse sampling. His argument is that the relevant question is what population a claim is intended to generalize to and what moderators the theory predicts. Convenience sampling can be entirely appropriate for basic research. He also stresses that “WEIRD sample” and “convenience sample” are not the same methodological problem.
  • Open manuscript copy

Gary Latham: Primed for Achievement

Gary P. Latham is a professor at the business school of the University of Toronto, where he has spent his career studying goal pursuit — how people successfully accomplish goals. His first article appeared in 1973, “Effects of Goal Setting and Supervision on Worker Behavior in an Industrial Situation.” Over fifty years later he is still publishing (Budworth & Latham, 2025). He has authored around 200 articles and is among the most highly cited scholars in his field, with over 1,000 citations annually in recent years in Web of Science and more than 100,000 on Google Scholar. In short, Latham is a highly successful, highly cited scholar who remains deeply invested in his work.

While Latham has studied goal pursuit from many angles, one line of his research drew on Bargh’s automaticity model. Bargh proposed that behavior can be influenced by situational cues, or primes, without a person’s awareness. The classic study that seemed to demonstrate this showed undergraduates words related to the elderly and then found them walking more slowly afterward (Bargh et al., 1996). It took more than a decade for a replication failure to be published (Doyen et al., 2012) — which does not mean it was the first failed attempt. Colleagues had informally shared that they could not reproduce the finding, but such results were practically impossible to publish. So it was big news when a failure finally appeared in print.

Meanwhile, Daniel Kahneman — who had won the Nobel Memorial Prize in Economics — published a popular book that featured priming studies as strong evidence that behavior is shaped by stimuli outside awareness (Kahneman, 2011, Thinking, Fast and Slow). Kahneman later sent Bargh an open letter asking for new replication studies to establish that priming actually works. Bargh did not produce a convincing demonstration, and as other researchers ran their own replications, many failed.

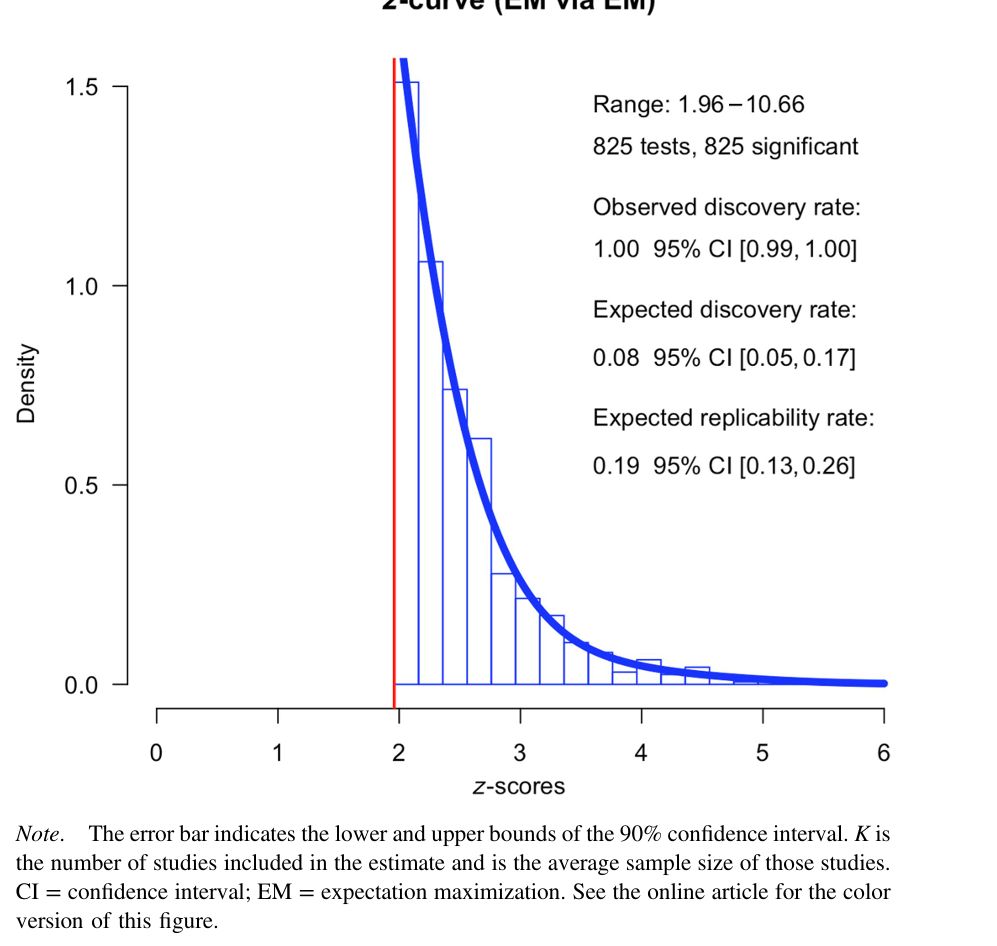
During the replication crisis, while priming was faltering in basic social psychology, Latham was still running priming studies — and in his, it worked (Itzchakov & Latham, 2020). Social psychologists paid little attention to these successes in applied organizational research. I became aware of them only when I searched for strongly supported effects within a meta-analysis of over 800 priming results (Dai et al., 2023), which led me to examine organizational priming more closely.

Latham even wrote an article titled “The Effect of Priming Goals on Organizational-Related Behavior: My Transition from Skeptic to Believer.” He built priming into his theory of goal-directed behavior — even after serious doubts about the underlying phenomenon had taken hold in social psychology (Chen, Latham, & Itzchakov, 2021; Latham & Locke, 2018).

Bargh himself took notice, and welcomed the finding that priming appeared to produce strong effects in real-world settings:

“The research reviewed in Chen et al.’s (this issue) meta-analysis shows that a person’s goal pursuits and motivational states can be induced by external means, or ‘primes’, and then operate in much the same way as if the person made a conscious intention to pursue that goal. Previous demonstrations of this phenomena in psychology laboratories are now extended to real life organizations and settings and shown to produce even stronger effects than before” (Bargh, 2021).

These seemingly robust priming effects in organizational research piqued my curiosity, but I was skeptical — as Latham himself had been, before he turned from Saul to Paul. So I looked more closely at the evidence for priming effects on task performance. What could explain stronger, more robust results in organizational settings than in social psychologists’ own laboratories?

The Secret Sauce: Sample Size?

Priming is not a single, well-defined phenomenon. Studies vary along many dimensions — often called moderators — and even similar-looking studies can produce different results. Why did Bargh et al. (1996) find effects of elderly primes on walking speed across two studies, while Doyen et al. (2012) found nothing?

One obvious reason is chance. Every experiment is a gamble, because its outcome is shaped by sampling error — especially in small samples. A few disinterested participants can drag down the group primed to succeed; in the next study, that same kind of participant lands in the control condition and inflates the apparent effect. Small samples were the norm in priming research (Kahneman, 2017). Many studies were noisy gambles. What made this a crisis rather than mere noise is that the wins were published and the losses mostly were not (Shanks & Vadillo, 2021; Sterling et al., 1995).

To produce reliable evidence, either the effect has to be large or the sample has to be large enough to overcome chance. So the first plausible explanation for more robust organizational results is that researchers in this area — Latham among them — simply used larger samples. Call this the Sample Size as Moderator hypothesis.

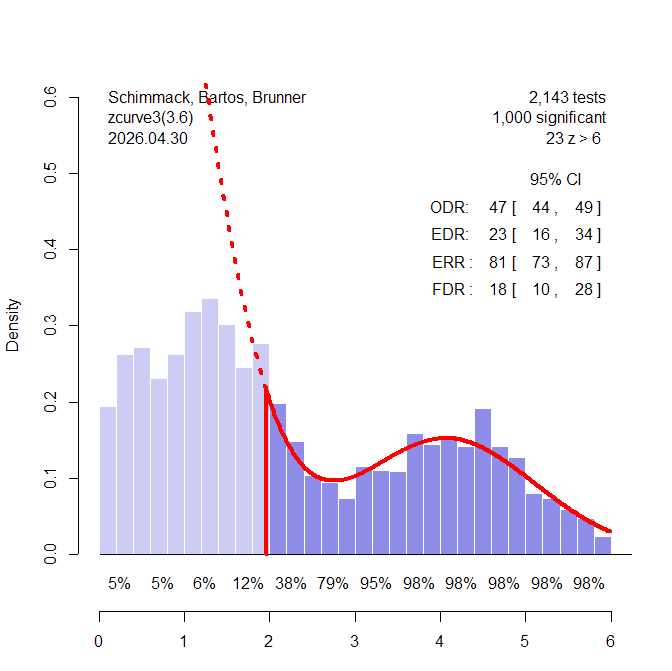
We can test this against the most recent meta-analysis of organizational priming. The open dataset contains 69 effect-size estimates (Latham, Chen, Piccolo, & Itzchakov, 2023). Of these, 31 (45%) are statistically significant at the conventional α = .05 — barely above the 38% found across priming studies generally (Dai et al., 2023). A seven-point gap is no evidence that organizational priming is more robust; both literatures show priming failing about as often as it succeeds. Larger samples are not the secret sauce.

The Secret Sauce: Picture Priming?

Latham et al. (2023) aimed to include every study of priming in organizational settings. A large share came from Latham and his close collaborators — Shantz, Stajkovic, Itzchakov, Piccolo — as their co-authorships show. And when the dataset is broken down by lab, the pattern splits sharply. Studies from Latham and his collaborators succeed 78% of the time. Studies from every other lab succeeded only 24% of the time.

So it is not organizational settings that make priming robust. The effect is not a property of the field; it is a property of one group of researchers. What makes their studies different?

One possibility is the prime itself. Perhaps priming really is context-dependent, and Latham’s group happened onto a type of prime that works where others fail. There are a few candidates to consider. Some studies used subliminal words flashed briefly on screen — attractive because the stimulus is unambiguously outside awareness, but, at least in behavioral priming, apparently ineffective (Schimmack, 2026). Others embedded words in tasks such as scrambled sentences. Participants processed these consciously yet, in interviews, did not believe the words had influenced them — and in many cases they were right: the significant results were chance findings that did not replicate (Schimmack, 2026; Shanks et al., 2013; Shanks & Vadillo, 2019). Neither of these prime types survives scrutiny. But Latham’s signature manipulation was neither subliminal nor verbal. It was a picture.

In the seminal field study by Shantz and Latham (2009), 80 employees were randomly assigned to a control condition and a priming condition. The prime was a picture of a runner winning a race. The priming result was statistically significant, F(1, 77) = 4.95, but not remarkable. The effect-size estimate was moderate, d = .43, with a wide confidence interval ranging from .05 to .93. Notably, Shantz and Latham (2011) also obtained a significant result in a replication study with only a quarter of the sample size, total N = 20, t(18) = 2.23, p < .05. A second replication study with 44 participants was also significant, t(42) = 2.04, p < .05.

Studies with modest effect sizes and small samples are likely to produce non-significant results at some point (Schimmack, 2012). I asked professor Latham whether there were any unpublished studies with non-significant results. He replied that this was not the case.

“All my priming studies worked probably because I do pilot studies”
—Latham, personal communication, July 30, 2026

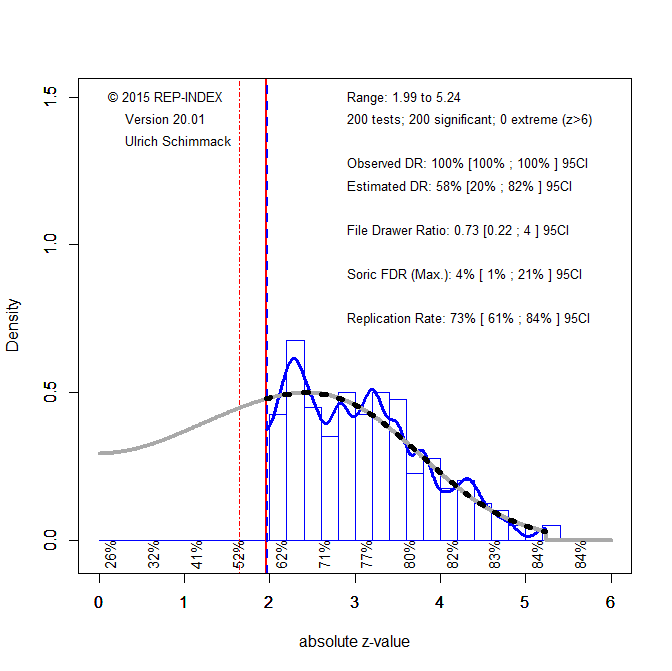
Even without non-significant results, the published estimates probably benefit from inflation. With three independent studies the t-values should vary with a variance near 1. Here the variance of 2.23, 2.23, 2.04 is only 0.01. This is what the Test of Insufficient Variance (TIVA; Keiner & Renkewitz, 2019; Schimmack, 2015) is built to detect: a simulation with t-tests and matching degrees of freedom puts the probability of variance this small or smaller at about 1%. A representative set of studies would have produced some non-significant results — and, for these sample sizes, a lower average effect size.

The Secret Sauce: Feedback as Moderator

The studies with the strongest effects in Dai et al.’s meta-analysis came from Itzchakov and Latham (2020), which reported four studies. Importantly, the main hypothesis was not simply that primes influence behavior. It was that the effect of primes is moderated by performance feedback — primes should work more strongly when paired with feedback.

Supporting this requires a significant interaction, and all four studies delivered one. Once more, luck seems to have helped: the four interaction t-values cluster implausibly tightly, with a variance of 0.014. With samples near 200 the test statistics are effectively normal, so the analytic test suffices: a variance this small has probability p = .002.

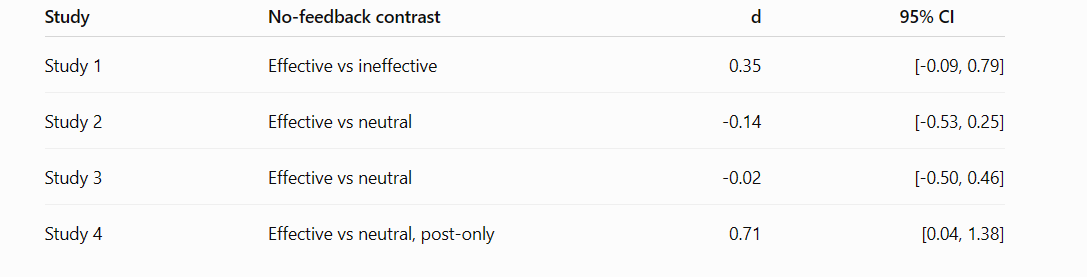
More important are the results for the no-feedback condition that replicates the previous studies. Across the four no-feedback contrasts, three were null (d = 0.35, −0.14, −0.02) and one was significant (Study 4, d = 0.71). Pooled, the no-feedback effect is d = 0.13, with a 95% confidence interval spanning zero, [−0.10, 0.36]. The condition that most directly reproduces the original Shantz and Latham design — a picture prime and nothing else — shows essentially no effect once the four studies are combined.

In other words, Itzchakov and Latham had four opportunities to reproduce Latham’s foundational priming effect in the no-feedback conditions. Three produced nothing, one was significant, and pooled across all four the effect is indistinguishable from zero (d = 0.13, [−0.10, 0.36]). None of this was reported as a replication failure. The studies were presented as successes — because the interaction was significant — with the weak no-feedback effects framed merely as smaller than the feedback effects. But a picture prime that does essentially nothing on its own, and appears to work only alongside feedback, is not the phenomenon Latham built his theory on. It is a narrower claim: not that priming works and feedback amplifies it, but that priming may not work at all without feedback.

Whether priming genuinely works in combination with feedback is a question for future studies. There is a plausible mechanism — feedback could make a goal more concrete or more relevant to performance. But that is a far narrower claim than the original one: that a picture prime, by itself, improves work performance.

Conclusion

Latham described himself as a believer. Kahneman was a believer too. In Thinking, Fast and Slow, he asked readers to believe as well:

“Disbelief is not an option. The results are not made up, nor are they statistical flukes. You have no choice but to accept that the major conclusions of these studies are true.”

Years later, he recanted. In 2017 Kahneman wrote, “I placed too much faith in underpowered studies.” He had come to see that hundreds of statistically significant findings amount to strong evidence only if the studies are reported honestly. If there is a large file drawer of unpublished failures, the published literature can manufacture the illusion of a robust effect.

The evidence of publication bias in the priming literature is no longer in doubt (Dai et al., 2023). The harder question is whether any priming effect survives once that bias is taken into account. In organizational priming the answer appears to be: maybe, but only under narrow conditions. The evidence does not show that priming reliably changes behavior in general. It shows that some effects may appear in specific settings, with specific primes, specific outcomes, and sometimes only when paired with feedback.

Priming is not the first case of scientists finding compelling evidence for something that was not there. Langmuir called it pathological science: honest researchers, following the ordinary rules of their field, converging on an effect that does not exist (Langmuir, 1953). What makes it pathological is not fraud but conviction. The scientists most likely to fool themselves are the ones most committed to the phenomenon — the believers, driven to demonstrate what they already know to be true. The skeptic who doubts everything rarely produces a striking result; the believer who doubts nothing produces a career’s worth. Feynman put the hazard plainly: “The first principle is that you must not fool yourself — and you are the easiest person to fool” (Feynman, 1974).

Latham called himself a believer. That was the problem.

References

Bargh, J. A. (2021). Unconscious goal pursuit in real-life organizations: Commentary on Chen, Latham, Piccolo, and Itzchakov (2020). Applied Psychology: An International Review, 70, 254–261. https://doi.org/10.1111/apps.12259

Bargh, J. A., Chen, M., & Burrows, L. (1996). Automaticity of social behavior: Direct effects of trait construct and stereotype activation on action. Journal of Personality and Social Psychology, 71(2), 230–244. https://doi.org/10.1037/0022-3514.71.2.230

Chen, X., Latham, G. P., Piccolo, R. F., & Itzchakov, G. (2021). An enumerative review and a meta-analysis of primed goal effects on organizational behavior. Applied Psychology: An International Review, 70, 216–253. https://doi.org/10.1111/apps.12239

Dai, W., Yang, T., White, B. X., Palmer, R., Sanders, E. K., McDonald, J. A., Leung, M., & Albarracín, D. (2023). Priming behavior: A meta-analysis of the effects of behavioral and nonbehavioral primes on overt behavioral outcomes. Psychological Bulletin, 149(1–2), 67–98. https://doi.org/10.1037/bul0000374

Doyen, S., Klein, O., Pichon, C.-L., & Cleeremans, A. (2012). Behavioral priming: It’s all in the mind, but whose mind? PLoS ONE, 7(1), e29081. https://doi.org/10.1371/journal.pone.0029081

Feynman, R. P. (1974). Cargo cult science. Engineering and Science, 37(7), 10–13.

Itzchakov, G., & Latham, G. P. (2020). The moderating effect of performance feedback and the mediating effect of self-set goals on the primed goal–performance relationship. Applied Psychology: An International Review, 69(2), 379–414. https://doi.org/10.1111/apps.12176

Kahneman, D. (2011). Thinking, fast and slow. Farrar, Straus and Giroux.

Kahneman, D. (2017). Comment on “Reconstruction of a train wreck: How priming research went off the rails.” Replicability-Index. https://replicationindex.com/2017/02/02/reconstruction-of-a-train-wreck-how-priming-research-went-of-the-rails/

Langmuir, I. (1989). Pathological science (R. N. Hall, Ed.). Physics Today, 42(10), 36–48. (Original work presented 1953). https://doi.org/10.1063/1.881205

Latham, G. P. (2018). The effect of priming goals on organizational-related behavior: My transition from skeptic to believer. In G. Oettingen, A. T. Sevincer, & P. M. Gollwitzer (Eds.), The psychology of thinking about the future (pp. 392–404). Guilford Press.

Latham, G. P., Chen, X., Piccolo, R. F., & Itzchakov, G. (2023). An updated meta-analysis of the primed goal–organizational behaviour relationship. Royal Society Open Science, 10(4), 221494. https://doi.org/10.1098/rsos.221494

Latham, G. P., & Locke, E. A. (2018). Goal setting theory: Controversies and resolutions. In D. S. Ones, N. Anderson, C. Viswesvaran, & H. K. Sinangil (Eds.), The SAGE handbook of industrial, work & organizational psychology (2nd ed., Vol. 1, pp. 103–124). Sage.

Renkewitz, F., & Keiner, M. (2019). How to detect publication bias in psychological research: A comparative evaluation of six statistical methods. Zeitschrift für Psychologie, 227(4), 261–279. https://doi.org/10.1027/2151-2604/a000386

Schimmack, U. (2012). The ironic effect of significant results on the credibility of multiple-study articles. Psychological Methods, 17(4), 551–566. https://doi.org/10.1037/a0029487

Schimmack, U. (2015). The test of insufficient variance (TIVA): A new tool for the detection of questionable research practices [Blog post]. Replicability-Index. https://replicationindex.com/2014/12/30/the-test-of-insufficient-variance-tiva-a-new-tool-for-the-detection-of-questionable-research-practices/

Schimmack, U. (2026). A new look at implicit priming: Making sense of heterogeneity in conceptual replication studies [Manuscript submitted for publication]. Department of Psychology, University of Toronto.

Shanks, D. R., Newell, B. R., Lee, E. H., Balakrishnan, D., Ekelund, L., Cenac, Z., Kavvadia, F., & Moore, C. (2013). Priming intelligent behavior: An elusive phenomenon. PLoS ONE, 8(4), e56515. https://doi.org/10.1371/journal.pone.0056515

Shanks, D. R., & Vadillo, M. A. (2021). Publication bias and low power in field studies on goal priming. Royal Society Open Science, 8(10), 210544. https://doi.org/10.1098/rsos.210544

Shantz, A., & Latham, G. P. (2009). An exploratory field experiment of the effect of subconscious and conscious goals on employee performance. Organizational Behavior and Human Decision Processes, 109(1), 9–17. https://doi.org/10.1016/j.obhdp.2009.01.001

Shantz, A., & Latham, G. P. (2011). The effect of primed goals on employee performance: Implications for human resource management. Human Resource Management, 50(2), 289–299. https://doi.org/10.1002/hrm.20418

Sterling, T. D., Rosenbaum, W. L., & Weinkam, J. J. (1995). Publication decisions revisited: The effect of the outcome of statistical tests on the decision to publish and vice versa. The American Statistician, 49(1), 108–112. https://doi.org/10.1080/00031305.1995.10476125

Vadillo, M. A., Hardwicke, T. E., & Shanks, D. R. (2016). Selection bias, vote counting, and money-priming effects: A comment on Rohrer, Pashler, and Harris (2015) and Vohs (2015). Journal of Experimental Psychology: General, 145(5), 655–663. https://doi.org/10.1037/xge0000157

Yong, E. (2012). Nobel laureate challenges psychologists to clean up their act. Nature. https://doi.org/10.1038/nature.2012.11535

Modeling Heterogeneity in Meta-Analyses

Correction (2026-07-14)
The original post claimed that violations of the normality assumption biases standard random effects estimates. That finding was based on a coding error in the simulation program. The revised post shows the results for simulations with normal distributed effect sizes for H1 and mixtures of H0 and H1. In these simulations only estimates of the weight-function selection model (weightr package) are biased when the unimodal normal distribution assumption is violated.

Introduction

The main purpose of meta-analysis is to combine the results of quantitative studies. The simplest form averages the effect-size estimates of studies. The average is a better estimate of the population effect size because it draws on the combined sample size of the individual studies, and larger samples have less sampling error. A more sophisticated version takes each study’s sampling error into account, weighting studies with larger samples more heavily than those with smaller samples. This weighted average approximates the estimate one would obtain by pooling the raw data, under the assumption that all studies estimate the same effect.

These so-called fixed-effect meta-analyses assume that the samples are all drawn from the same population and that studies used interchangeable procedures, so that they all estimate a single population effect size. This assumption is defensible for a few phenomena grounded in basic sensory or cognitive architecture. Weber’s law, for instance — that the just-noticeable difference between two stimuli is a roughly constant proportion of their magnitude — reflects a property of sensory transduction and varies little across procedures and individuals. But such near-constants are the exception. Most effects in psychology vary with situational and personality factors, within and across cultures. This variation adds real differences in the true effect sizes across studies, over and above sampling error.

In recognition of this true variation, statisticians developed random-effects models (DerSimonian & Laird, 1986). To model the variation in population effect sizes, it is necessary to select a model that describes the unobserved variation in population effect sizes. From a statistical perspective, the easiest model assumes that population effect sizes have a normal distribution. The symmetry of this assumption implies that the estimate obtained from a set of studies is an unbiased estimate of the true average because positive and negative deviations from the average population effect size cancel each other out, just like random sampling errors cancel each other out.


Distribution Assumptions

From a theoretical perspective, it is unlikely that population effect sizes are normally distributed, particularly when the mean effect is small relative to the between-study heterogeneity. The reason is that effects are typically coded so that positive values are consistent with a directional theoretical prediction (e.g., conflicting colors produce slower responses in the Stroop task). While the size of the effect may vary across studies, it is often implausible that the true effect in some studies would be reversed (that conflicting colors would genuinely speed responses). A normal distribution, however, has support over the entire range of effect sizes and therefore always assigns some probability to negative true effects — an implication that is difficult to justify for a directionally predicted effect. When the mean is small relative to the heterogeneity, a normal distribution implies that a non-trivial proportion of true effects are negative, which is often theoretically implausible.

In practice, however, when heterogeneity is small, violations of the normality assumption have small and often negligible effects on meta-analytic estimates of the average effect (Hedges & Vevea, 1996). This helps explain why widely used random-effects models share the assumption that population effect sizes are normally distributed, including standard random-effects meta-analysis (DerSimonian & Laird, 1986) as implemented in commonly used software (Viechtbauer, 2010), selection-model approaches (Vevea & Hedges, 1995; Vevea & Woods, 2005), and the random-effects components of Bayesian model-averaging methods (Bartoš et al., 2023; Maier et al., 2023).


Necessary and Unnecessary Assumptions

It is useful to distinguish between necessary and unnecessary assumptions. All statistical methods require some assumptions to reduce the complex information in data to an interpretable statistic. However, not all assumptions of a model are necessary. In general, models with fewer unnecessary assumptions are preferable because they are robust to violations of these unnecessary assumptions by design. For example, the Pearson correlation coefficient assumes normal distribution of the two variables, whereas rank-order correlations do not. This makes rank-order correlations robust to violations of the normal distribution assumption and it is common practice to prefer rank-order correlations when variables’ distributions are not normal.

In meta-analyses, the assumption that population effect sizes are normally distributed is an unnecessary assumption. The idea of estimating the distribution of effects without assuming a parametric form is not new. Laird (1978) and Lindsay (1983) showed that the mixing distribution in a mixture model can be estimated nonparametrically by maximum likelihood, and that the resulting estimate takes the form of a discrete distribution on a finite set of support points. This provided, in principle, a fully flexible way to model heterogeneity without assuming normality. In practice, however, fitting these models was computationally demanding at the time.

Advances in optimization and computing have since removed these hurdles. Efficient algorithms for estimating mixture models — including modern convex-optimization methods (Koenker & Mizera, 2014; Kim et al., 2020) — now make it possible to fit flexible mixtures quickly and reliably. These developments led to the widespread adoption of nonparametric and empirical-Bayes mixture models in fields that analyze large numbers of effects, most notably genomics (Efron, 2010; Stephens, 2017), where the goal is to characterize the distribution of effects across thousands of tests and to identify which are likely to be real. Similar approaches have been applied in astronomy, education, and other areas that deal with many parallel estimates.


Heterogeneity of Population Effect Sizes

Meta-analysis, however, did not adopt these models, and continued to rely on the normal random-effects model. One reason is that the goal of most meta-analyses has been to estimate a single average effect, for which the shape of the effect-size distribution is largely irrelevant. The additional information provided by a flexible mixture — the structure of the heterogeneity itself — was not part of the question being asked.

This has changed with growing recognition of the distinction between direct and conceptual replication (Zwaan et al., 2018). Experimental psychologists rarely repeat a procedure exactly. Instead, they typically vary paradigms across studies in the belief that this is good scientific practice — probing moderators, boundary conditions, and the generalizability of an effect. As a result, the studies combined in a meta-analysis often estimate genuinely different population effects, and meta-analyses of such conceptual replications frequently show high estimates of heterogeneity (van Erp et al., 2017). In these cases the average effect size is of relatively minor interest, because it merely centers a wide distribution of different population effect sizes — an average across paradigm variants that no single study actually instantiates. The scientifically interesting question is not the average, but how and why the effects differ.


Mixture Models

Mixture models have another advantage over random effects models for meta-analysis. In standard meta-analytic models the population distribution of effect sizes is characterized by the mean and standard deviation of a normal distribution. Importantly, this information is removed from the observed data. It is therefore not possible to use this information to make sense of the heterogeneity in the observed effect size estimates in the data. A large effect size in the data may correspond to a small population effect size because it was inflated by sampling error and vice versa. This explains why heterogeneity often plays a minor role in the interpretation of meta-analyses. Heterogeneity exists, but it cannot be explained.

In contrast, mixture models combined with statistical tools that correct for regression to the mean make it possible to obtain estimates of the population effect size of individual studies. Often these effect size estimates for single studies have large uncertainty (wide confidence intervals), but they can be averaged to identify subgroups of studies with large effect sizes. This makes it possible to explore the heterogeneity in observed studies.


Simulation Study

To demonstrate the capabilities and advantages of mixture models over traditional random-effects models, I conducted a simulation study. To isolate the effect of the distributional assumption, the simulation used unbiased data (no publication selection). This removes selection as a confound and allows inclusion of the adaptive-shrinkage mixture model ash (Stephens, 2017), which was developed for genomics and assumes complete, unselected data. The other two models — the weight-function selection model (Vevea & Woods, 2005) and z-curve — model publication bias but reduce to unbiased estimation when no selection is present.

Z-curve is a meta-analytic mixture model (Brunner & Schimmack, 2020; Bartoš & Schimmack, 2022). Version 1 used the noncentrality parameters (ncp) of significant results to estimate the expected replication rate for direct replication studies. Version 2 used the ncp distribution across all studies to estimate the expected discovery rate. Version 3 adds an empirical-Bayes function that estimates population effect sizes by multiplying ncp estimates by their corresponding sampling errors, recovering effects from the latent distribution of noncentrality parameters.

The simulation used fixed sample sizes across studies, which ensures that mixture models fit in the effect-size metric and in the ncp metric produce identical results. Each condition contained k = 1,000 studies; the large k yields small sampling error in the estimates, making systematic biases more visible. The design crossed 4 means and 4 standard deviations of the population effect-size distribution with 4 proportions of true null hypotheses, producing 64 conditions. The population effect sizes when H1 is true were drawn from a normal distribution. However, mixing true H0 and H1 produces non-normal, bimodal distributions. This violates the distribution assumption of standard meta-analytic methods and could produce biased estimates.

zcurve3.0/SimpleMix_All_Normal_ZC_ASHR_VW_RMA.R at main · UlrichSchimmack/zcurve3.0

Results

These results for the mixture models (z-curve, ash) are not surprising. The models make no distribution assumptions and estimates of the mean closely match the simulated true values (z-curve RMSE = .009; ash RMSE = .010). The weight-function selection model had worse fit (RMSE = .138), but the random effects model fit as well as the mixture models (RMA RMSE = .003).

The results for the estimate of heterogeneity (tau) showed that all models estimated heterogeneity well, (z-curve RMSE = .018, ash RMSE = .027, weightr RMSE = .030, RMA RMSE = .013).

The present results show that the random effects model is robust to violations of the normality assumption even when heterogeneity is large and distributions are bimodal. The same cannot be said for the selection model with a normal assumption (weightr). Here the weight parameters to model selection bias can be biased to fit a normal distribution to non-normal observed data. The main implication is that it is possible to improve the performance of selection models by avoiding the normality assumption and modeling the distribution of population effect sizes with a flexible mixture model.


Implications

The present simulation showed that the random-effects model estimates the mean effect well when data are unbiased, even when its distributional assumptions are violated. This is consistent with a substantial prior literature. Simulation studies have repeatedly found that the pooled mean from the normal random-effects model is robust to non-normal random-effects distributions, including skewed and mixture distributions (Yamaguchi et al., 2017; Rubio-Aparicio et al., 2023; Baur et al., 2025). The robustness follows from the estimator itself: the pooled mean is an inverse-variance weighted average, which is consistent for the population mean regardless of the shape of the effect distribution. Large numbers of studies further protect against non-normality (Rubio-Aparicio et al., 2023), and with k = 1,000 the present simulation is in this favorable regime.

Where the normality assumption does matter is not the mean but the characterization of the distribution around it. The same literature finds that non-normality degrades the coverage of confidence and prediction intervals far more than it biases the mean (Baur et al., 2025), and that a symmetric normal model produces a wrongly symmetric prediction interval and a misleading heterogeneity summary when the true distribution is skewed (Yamaguchi et al., 2017). The recognized advantage of flexible mixture and semi-parametric models is therefore not lower bias on the mean but their ability to reveal latent structure — clusters and subgroups of studies — that the mean and a single heterogeneity parameter discard (Baur et al., 2025).

These are real but secondary limitations. The more fundamental problem is one that no distributional flexibility can address: the random-effects model, and the adaptive-shrinkage mixture model (ash) alike, assume that the observed studies are an unbiased sample of the population. In many literatures this assumption is untenable. In psychology, studies with significant results are far more likely to be published; the proportion of significant results often exceeds 90% (Sterling et al., 1995). Such publication bias inflates effect-size estimates, and correcting for it requires modeling the selection process — something neither the random-effects model nor ash attempts. A flexible distribution alone is not enough; what is needed is a model that combines distributional flexibility with a model of selection.

Z-curve occupies this niche: it combines a selection model, which corrects for publication bias, with a flexible mixture model, which captures heterogeneity without a distributional assumption. This is why z-curve outperforms weight-function models when studies are both heterogeneous and affected by publication bias (Schimmack, 2026).


References:

Bartoš, F., Maier, M., Wagenmakers, E.-J., Doucouliagos, H., & Stanley, T. D. (2023). Robust Bayesian meta-analysis: Model-averaging across complementary publication bias adjustment methods. Research Synthesis Methods, 14(1), 99–116.

Böhning, D. (2000). Computer-assisted analysis of mixtures and applications: Meta-analysis, disease mapping and others. Chapman & Hall/CRC.

DerSimonian, R., & Laird, N. (1986). Meta-analysis in clinical trials. Controlled Clinical Trials, 7(3), 177–188.

Hedges, L. V., & Vevea, J. L. (1996). Estimating effect size under publication bias: Small sample properties and robustness of a random effects selection model. Journal of Educational and Behavioral Statistics, 21(4), 299–332.

Laird, N. (1978). Nonparametric maximum likelihood estimation of a mixing distribution. Journal of the American Statistical Association, 73(364), 805–811.

Lindsay, B. G. (1983). The geometry of mixture likelihoods: A general theory. The Annals of Statistics, 11(1), 86–94.

Maier, M., Bartoš, F., & Wagenmakers, E.-J. (2023). Robust Bayesian meta-analysis: Addressing publication bias with model-averaging. Psychological Methods, 28(1), 107–122.

Stephens, M. (2017). False discovery rates: A new deal. Biostatistics, 18(2), 275–294.

Vevea, J. L., & Hedges, L. V. (1995). A general linear model for estimating effect size in the presence of publication bias. Psychometrika, 60(3), 419–435.

Vevea, J. L., & Woods, C. M. (2005). Publication bias in research synthesis: Sensitivity analysis using a priori weight functions. Psychological Methods, 10(4), 428–443.

Viechtbauer, W. (2010). Conducting meta-analyses in R with the metafor package. Journal of Statistical Software, 36(3), 1–48.

Efron, B. (2010). Large-scale inference: Empirical Bayes methods for estimation, testing, and prediction. Cambridge University Press.

Kim, Y., Carbonetto, P., Stephens, M., & Koenker, R. (2020). A fast algorithm for maximum likelihood estimation of mixture proportions using sequential quadratic programming. Journal of Computational and Graphical Statistics, 29(2), 261–273.

Koenker, R., & Mizera, I. (2014). Convex optimization, shape constraints, compound decisions, and empirical Bayes rules. Journal of the American Statistical Association, 109(506), 674–685.

Laird, N. (1978). Nonparametric maximum likelihood estimation of a mixing distribution. Journal of the American Statistical Association, 73(364), 805–811.

Lindsay, B. G. (1983). The geometry of mixture likelihoods: A general theory. The Annals of Statistics, 11(1), 86–94.

Managing the Terror of Meta-Analyses

Summary

For method folks, the picture tells the full story: z-curve can estimate the true mean of a set of heterogeneous studies better than the weight-function model because the weight function model makes unrealistic assumptions about the distribution of population effect sizes. Added bonus: z-curves estimates are related to actual studies, whereas the estimates of weightr are population estimates that are not connected to the actual studies.

Try it: TMT analysis with z-curve.3.86

The Long Story

The root cause of the crises in psychology is poor training in scientific thinking and scientific methods. Period! I know because I have been teaching at a top-ranked university in North America for over 25 years now. The most common criticism in student evaluations is that my courses are not psychology courses, but statistics course. The reason: I use numbers when I present research findings. But most students can get a degree in psychology without using numbers. Graduate education does not help because students learn from a mentor, who also never learned to think quantitatively. So, psychology is the worst of both worlds. It is neither qualitative research that pays attention to people’s thoughts, feelings, or actual behaviors, nor is it a quantitative science that use valid quantitative information for the same purpose. It is a pseudo-science that produces meaningless numbers that mainly serve the purpose of claiming scientific support for researchers’ personal beliefs.

The problem that quantitative results in published articles cannot be trusted is now widely recognized and has been called a crisis of confidence a credibility crisis, or the replication crisis. However, the problem also exists at the meta-level when questionable published results are combined into a meta-analysis. Don’t get me wrong. Meta-analysis, like all statistical models, are not wrong. They are only wrong when incompetent researchers use these tools without understand how they work and what assumptions these models make.

Meta-analysis is easy to understand and perform when all data are available. We simply combine summary statistics to reduce sampling error and get a more precise estimate of the population effect size. Instead of running one study with N = 1,000 participants, we combine data from 25 studies with 40 participants. The result is practically the same. However, in psychology, the 25 published study are only a fraction of studies that were conducted and produced a significant result (Sterling et al., 1995). This means the effect sizes in the studies are inflated by publication bias and the same bias leads to an inflated effect size estimate in the meta-analysis. Thus, normal meta-analysis that ignore bias are as useful as a wet tissue paper on a 40°C (104°F) day in the middle of a parking lot at noon.

The solution to this problem is to use fancy statistical models that promise to correct for these biases and reveal the truth hidden in a pile of selected and p-hacked studies. The simple truth is that this goal is as attainable as making gold from base metals. However, as readers also do not understand these models and the problem of using them with uninformative data, the results are now routinely included in meta-analytic articles, if only as a sensitivity analysis that can be dismissed if it shows inconvenient or strange results.

Before I show how silly bias-correction of biased literature is, I need to present an example to show that I am not attacking a strawman model of bad meta-analysis. The example comes from a recent meta-analysis of studies that examined the influence of mortality salience on feelings, attitudes, and behaviors (Chen et al., 2025). The meta-analysis is notable for its attempt to deal with publication bias. The title even mentions publication bias in a clever way “Managing the Terror of Publication Bias.” The authors also shared their data. So, the only problem is that they did not consult with experts to make sense of their findings.

Figure 1 shows a simple histogram of the effect size ESTIMATES – these are estimates in small samples with enormous sampling error, not the actual effect sizes without sampling error.

Figure 1.

The most important observation for this blog post is that there are hardly any effect sizes below zero. To understand why this is important, it is important to understand the meaning of the sign of an effect size. In an original study, the sign has no meaning. For example, the height differences between people with XX and XY chromosomes can be positive or negative depending on the coding of XX as 0 or 1 and XY as 1 or 0, respectively.

For a meta-analysis, however, the sign becomes meaningful. In a competently conducted meta-analysis, the sign reflects the substantive hypothesis of a study. If mortality salience is coded as 1 against a control condition coded as 0, and the theory predicted an increase in a dependent variable, a positive sign implies that the result was consistent with the prediction. If the prediction implies a decrease in the DV, a negative sign is consistent with the theory, and the sign has to be reversed. Thus, if researchers mostly make correct predictions about the direction of an effect, we would expect mostly positive signs. Sampling error can still produce negative means in studies, even if the true effect is in the predicted direction, but how often that happens depends on the strength of the effect.

Now we are in the position to make sense of Figure 1. Only 2% of the effect size estimates. There are two possible explanations for this finding. Either TMT studies mostly produce positive results because most studies have true effects or there is selection bias and results that contradict theoretical predictions are not published (a third option would be coding mistakes, where coders code all results as positive and ignore substantive hypotheses).

What happens when these data are analyzed with bias-correction models? It depends on the model. The PET/PEESE model regresses effect sizes on the sampling error under the assumption that all studies have a common effect size and that larger samples are less biased.

The reanalysis that produced Figure 2 reproduced the published estimate of -.114 standard deviations. Thus, even though there are hardly any negative results in the data, the average study is supposed to have made a prediction in the wrong direction because that is what a negative mean means. An analysis that removed the 10% largest effect sizes, produced a positive estimate of .29 standard deviations. It is interesting that removing strong results increases the average. This shows that the results depend on assumptions about the amount of bias for different effect size estimates. Here the largest effect size estimates come also from the smallest studies (N < 10).

The point estimate of .29 should not be confused with the true effect size in each study. After removing sampling error, there is still considerable variability in the effect size estimates that can be quantified with the standard deviation, assuming a normal distribution. The estimate is tau = .40. This also makes it possible to create a prediction interval – a confidence interval for the hypothetical population effect sizes . To get a 95%CI we roughly multiply tau by 2 and get a range of values around the point estimate from .29 – ,80 to .29 + .80. Thus, any particular TMT study could have an effect size anywhere from -.51 to + 1.09. In terms of Cohen’s classification of effect sizes the effect sizes range from a moderate negative effect size to a strong positive effect size. In other words, the data are not telling us anything that we did not know before we ran the analysis. Terror Management effects may sometimes emerge as predicted, sometimes with surprising opposite effects, and sometimes have no notable effects, and we do not know which manipulation produces which effect.

The problem in the published article and many other meta-analysis is that the heterogeneity in effect sizes after taking random sampling error was ignored. The point estimate is only needed to center the prediction interval. The real information is the wide range of possible population effect sizes that are consistent with the model’s assumptions and the data. Every outcome except large negative effect sizes is possible.

Regression models have many limitations and even the developer of this approach has warned against the use of this model for highly heterogenous data (Stanley, 2017). A model that is more suitable for heterogeneous data is the weight-function selection model (Vevea & Woods, 2005). However, this model requires assumptions about selection bias. Chen et al. fitted a model that assumes different selection bias for significant negative results and non-significant results. Importantly, their model assumed the same amount of selection bias for negative non-significant results and positive significant results. This specification is important because Figure 1 shows that there are few negative effect sizes. A better way to see the problem here is to convert effect sizes and sampling error into z-values (z = effect size / standard error) to distinguish between non-significant (z < 1.96) and significant ones.

Figure 3 shows clearly that there is selection against negative results. Sampling error alone cannot explain the drop in effect size estimates from just above zero to just below zero.

The published article reports an estimated average effect size of .36. The model also estimated that only 26% of non-significant results were included in the meta-analysis. In other words, 74% were missing due to to publication bias. Finally, the model estimated that the population effect sizes had high heterogeneity, tau = .71. This leads to a very wide prediction interval around the point estimate of .36 ranging from .36 – 2*.71 to .36 + 2 * .71, which is -1.01 to 1.73. In other words, the model does not even exclude strong negative effect sizes as possible outcomes.

However, this model is misspecified because it ignores that selection against negative non-significant results is stronger than selection against non-significant positive results. I therefore ran the model again with an additional step at p = .5 (one-sided) that separates positive from negative results.. Consistent with the pattern in Figure 3, the model shows stronger selection against negative results (weight = .01, selection 1-weight = 99%) than for nonsignificant positive results (weight = .30, selection bias 70%). This improved model, however, produced a negative estimated average effect size of -.34. It also further increased the estimate of heterogeneity to tau = .96.

To understand this behavior of the model (I am more of a model analyst than a psycho-analyst), we need to understand the model’s assumption about the distribution of the unobserved population effect sizes. The model assumes an unobserved normal distribution, but the data are a truncated distribution at zero with no meaningful negative values. The model therefore fits the positive range of a normal distribution to the observed positive values. If this distribution is very wide, the normal has a large standard deviation and the model extrapolates it into the negative range. This leads to the wide prediction interval ranging from -1.34 to 2.58. Importantly, the negative range is entirely based on distribution assumption of the model . Changing the distribution assumption would change the results.

So, we have to think about the distribution assumption. When studies are more or less identical, there may be some extra variation in population effect sizes aside from sampling error. This variance can be approximated with a normal distribution (Hedges & Vevea, 1996). But when the set of studies has effect sizes ranging from 0 to 2, this is no longer plausible. If the average effect size is small and heterogeneity is large, a normal distribution implies that many substantive hypotheses have the wrong sign, but that is not really plausible. Many studies may have no real effect or really small ones, but it is harder to argue and to believe that researchers often get the sign of an effect wrong, especially when there is a real effect. Reminding people of their death makes them afraid is a reasonable hypothesis, and it would be surprising if studies show the opposite result.

In short, the weight-function model is not wrong, but applying a model that assumes a normal distribution to highly heterogeneous data is wrong. The model predicts many negative results that do not match any observed results. It could be selection bias, but it could also be a false distribution assumption. What to do?

A reasonable approach to make sense of results from the selection model is to focus on the positive side of the distribution. With normal distributions it is easy to get other statistics like the mean of only positive results (or any other subset of studies). We can therefore ignore studies with false substantive hypotheses and focus on studies where researchers made correct predictions about the sign of an effect (H1 is true).

With a mean of -.34 and tau = .956, we get a conditional mean for studies in which H1 is true of .65 standard deviations (a medium to large effect size) with tau of .52. As the lower bound is zero, we only need the upper bound and get .65 + 1.96 * .52 which is 1.67. This would suggest that many studies have strong effect sizes, which seems to contradict the estimated center of the distribution at -.34. This shows how meaningless these point estimates are when heterogeneity is large.

Unfortunately for terror management researchers the truncated moments are not going to rescue their literature because they are hypothetical. The reason is that we are conditioning on an unknown parameter, namely the condition that the hypothesis was true, but for any particular study we do not know whether H1 is true or not. So, the correct way to formulate this result is “if you can identify a study design in which terror management theory makes the right prediction and you can get a fairly precise estimate of the true effect size, you can expect a moderate effect size estimate.

What the weight-function model does not provide is a bias-corrected estimate of the positive effect size estimates in the dataset. The mean of the full distribution includes negative results that were either removed or never obtained. The truncated moment estimate conditions on the unknown status of the null-hypothesis. One is likely too low and the other is likely to high, but neither is conceptually the estimate we want. The average population effect size positive studies that corrects for the selection of nonsignificant results.

To summarize, state of the art meta-analyses in psychology try to deal with the terror of publication bias, but fail to do so. The main reason is that the statistical models that are available do not match the data. They were designed for meta-analysis of close replications with small variation in true effect sizes. They were not intended to be used for meta-analyses of diverse paradigms with large heterogeneity. Other methods that were developed after the replication crisis like p-curve and p-uniform have the same limitation. They work when heterogeneity is small, but they do not work for meta-analyses of diverse studies that are only loosely related by a common hypothesis.

Z-Curve to the Rescue

The quote “Insanity is trying the same thing and expecting a different result” has been attributed to Einstein. Even if that attribution is false, the insight is right. The problem with meta-analytic models is that they try to estimate a single number. This makes sense when the goal is estimation of a single population effect size, but not when every study has a different population effect size.

When we have a heterogenous literature, we need to face heterogeneity head on, and not hide it in some test that is reported and ignored. There is also heterogeneity around the estimate, p < .05. We need to see how much heterogeneity there. But to do that, we first need a model that can deal with heterogeneity without making unrealistic assumptions about the distribution of population effect sizes.

With a fresh look at the problem, we can look to other research areas that have addressed the problem of heterogeneity in effect sizes and large uncertainty about effect sizes of a specific result. Genomics tests millions of DNA segments (SNPs) and tries to find a few segments that show promising results. The goal here is to find the needles in the hey stack rather than averaging across millions of segments that have no relationship with a phenotype. As selection for the strongest observed effects leads to inflated estimates, models are needed to correct for this inflation. However, these corrected estimates are still tight to actual observed results rather than claims about some unobserved distribution of effect sizes. That makes it possible to identify specific segments in the observed data with promising results.

The same logic can be applied to meta-analysis. The goal is no longer to make claims like “the average population effect size is zero” or “the range of plausible effect sizes ranges from -1 to 1.” the goal is now to say “these studies show convincing evidence with meaningful effect sizes.”

One statistical model that can be used to answer this question is zurve (Brunner & Schimmack, 2020; Bartos & Schimmack, 2022). With a few modifications, z-curve can be used for directional meta-analysis where the sign of an effect matters. Rather than fitting z-curve to absolute z-values that ignore the sign and using folded normal components, z-curve can use truncated z-values and truncated normal components. When the model is fitted to only significant results, the difference is minor. More importantly, z-curve estimates of power can also be used to compute bias-corrected effect sizes (Efron, 2005). The reason is that power is a function of effect size and sampling error, so we can use the inverse normal to convert power into a corrected z-value and then multiply it with the sampling error to get a bias corrected effect size. The main challenge is to estimate the sampling error for unobserved non-significant results because their sample sizes are unknown. A simple approach is to use the sampling errors of the just significant results as an approximation. A weighted average of these estimates is the estimate of the true average effect size for the population of studies with positive results before selection for significance. Negative results that are observed are discarded.

Figure 4 shows the results of a simulation study in which the true average power before selection is known. The simulation modeled a beta distribution and graded selection bias. This is important because the weight-function model does well when its assumptions are met. The problem is that the assumptions are are untestable and often questionable. For example, we can simulate a literature with a mean of zero and tau of .4, but this simulation implies that a theories predictions are no better than a coin flip. Once researchers make better predictions, the normal assumption no longer holds.

While z-curve estimates are not perfect, they are conceptually meaningful and closer to the truth than either of the weight-function model’s estimates. We can now apply the model to the TMT data, excluding the few (2%) negative estimates.

The z-curve shows clear evidence of selection bias (the red dotted line is above the light purple bars of the nonsignificant results. However, the EDR estimate of 35% suggests that studies have on average 33% power to produce a significant result. Moreover, an EDR of 33% implies that no more than 10% of the significant results can be false positive results. Even the lower limit of the EDR confidence interval, 20%, allows for only 20% false positive results. This would suggest that many studies, especially significant ones, produced evidence for a true hypotheses with an effect size in the right direction. We can now also quantify the typical effect size. The overall effect size estimate is .63, 95%CI [.46 to .68]. Moreover, we can quantify the average for different ranges of z-values. The average increases from .40 for z-values between 0 and 0.5 to effect sizes greater than 1 for z-values greater than 4.

This finding is surprising, to say the least, because typical effect sizes in psychology are around d = .4 and rarely greater than 1. Before TMT researchers start celebrating, we have to reconcile these findings with the z-curve analysis published in the TMT article.

The z-curve looks notably different in that it does not have a long tail of high z-values. As a result, the EDR estimate is much lower, .08, and the 95% confidence interval includes alpha, 5% to 17%. This implies that there is no t enough evidence to reject the null-hypothesis that all significant results were obtained without a real effect, average effect size: zero, even for z-values greater than 4. So what is it? Is the average effect size close to zero or greater than 1?

To understand the different results, it is important to know that the published z-curve used a different coding of studies than the effect size meta-analysis. I fitted z-curve to these z-values and computed effect size and sampling error estimates from the z-values and degrees of freedom, assuming between-subject designs with equal cell sizes.

The plot is scaled to show the full distribution in the range of non-significant results. The model estimates reproduce the published results. The EDR is 7%, 95%CI = [5%, 17%]. The plot also shows local power for z-values from 0 to 3 stays low. Studies with z-values greater than 4 have acceptable local power but contrary to the previous z-curve, there are hardly any studies. This published z-curve produces dramatically different average effect size estimate, .12 95%CI = .02 to .19. The results also imply much lower heterogeneity because there are hardly any studies with strong evidence (z > 4) and large effect sizes.

Applying the weight-function selection model produces roughly the same results. The average effect size estimate is d = .17, and heterogeneity is small, tau = .17. Now the PET regression result also agrees, intercept = .05, tau = .19.

In conclusion, careful examination of this meta-analysis shows several problems. First, the data were coded inconsistently and different models were given different data. As it turns out, the effect size coding was wrong because F-values were coded as t-values, which dramatically inflates effect size estimates. Second, inconsistent results focused on the point estimate of models, but the point estimate is irrelevant when data are highly heterogenous (due to coding mistakes). Properly interpreted, all models suggest high heterogeneity that allows for large effect sizes among positive results. However, when the data are properly coded, the results show weak evidence that any study produced real effects, a high false positive risk, a small average effect size and small heterogeneity. These results change the final conclusion in the article.

“Given the conflicting findings that emerged across tools and the inherent trade-offs associated with each tool, we caution researchers against drawing firm conclusions about the evidential value of literature through any single analytic tool.”

Correction: The results are consistent and show that most studies provide no evidence for an effect because most effect sizes are small and studies had low power to detect or estimate these effects.

“PET-PEESE can underestimate the effect size when there is publication bias and when p-hacking is present (Carter et al., 2019), which are two conditions likely affecting the literature.”

Here bad research practices are used as an excuse to dismiss the most negative result without mentioning the real problem There is no “effect size.: there is only an average effect size and regression models still allow estimation of heterogeneity that was large in the data the authors used. Even a negative average can be consistent with many true positive effects when heterogeneity is large.

Z-curve can be a powerful tool for inferring the overall composite z-score distribution of a heterogeneous literature. However, unlike the other analyses included in this study, z-curve has not been as thoroughly evaluated by independent researchers so the statistical properties for its power estimates remain under explored. Furthermore, its power estimates are subject to the usual theoretical objections to estimating power from a fixed sample of data (for a recent commentary, see Pek et al., 2022).

This statement ignores that z-curve has been thoroughly evaluated by extensive simulations studies that have been reproduced by the editorial team during an open peer review process. The same cannot be said about the other methods that have not been vetted as rigorously or failed to do well in some conditions (Carter et al., 2019). The reference to Pek is also misleading which has been addressed in several rebuttals to this unfounded claim (Schimmack & Soto, 2026; Soto & Schimmack,2026) with no rejoinder by Pek.

The higher conditional power estimate therefore suggests some evidential value in published studies that yielded significant findings.

The authors are referring to the ERR estimate of 22% [16% , 37%]. Suddenly Pek’s criticism of z-curve is no longer relevant. More importantly, this finding implies that an exact replication of a study with a significant result has a 22% chance of a successful replication outcome. This is abysmal and one of the lowest ever found, not a cause for optimism. Surely reminders of mortality will sometimes have an effect on something, but a research program that uses different designs with an average power of 22% will not be able to identify when a manipulation works or when it is just a chance finding. In fact, the upper limit of the DR estimate is 100%. Thus, these weak studies fail to reject the hypothesis that all studies are pure noise.

“The selection models provide evidence for a small effect consistent with the MS hypothesis… We suggest that the average effect of the literature may be within the range estimated by the selection models and WAAP-WLS (i.e., r is around .18), although this average may have resulted from a mix of effects, many of which are higher than .18, and many of which are lower than .18.

The average estimate is too high once we correct for the coding mistakes. The real effect size is half of this (d = r / 2), and heterogeneity is small. This is the most conesquences conclusoin. Rather than having evidence of a wide range of positive effect sizes, we have evidence that most effect sizes are small and too small to study with the typical sample sizes of this literature.

We encourage future preregistered replications of the MS hypothesis to use smaller es
timates of effect size (i.e., r = .18).

This inflated effect size estimate will only lead to a replication failure. Given the weak evidence in this literature, it may be better to start a new credible research program about coping with awareness of one’s own mortality than to invest more resources into this failed paradigm with questionable manipulations and dependent variables.

Though on their face the liberal and conservative interpretations feel contradictory, some observations are uncontroversial. The first observation is that the TMT literature consists of highly heterogenous.

Even this conclusion turns out to be false when the proper data are analyzed. Heterogeneity was caused by coding mistakes and practically vanishes when the correct data coded by the authors were analyzed. The authors did not notice that their data were inconsistent, even though a simple comparison of the z-values would have shown the discrepancy. It is natural for humans to make errors, but errors also reveal something about the person who committed the error. In this case, it reveals a lack of understanding of the methods, their assumptions, and why they may produce inconsistent results. Here inconsistency was attributed to properties of the models when the real source were inconsistent data. In the future, meta-analysts should not just report inconsistencies, but also try to explain them. That requires understanding of the tools that they use.

For our entire universe of studies, heterogeneity is estimated at τ = .72 under the selection models, which means that for the estimate of g = 0.36 (r = .18) for the entire literature from the selection models, 95% of the effects underlying studies of MS hypothesis, assuming a normal distribution of g, fall between g = −1.05 and 1.77 (or r = −.47 and .66); an extremely wide range of possible effect sizes arising from differences in study design.

The problem with this wide range of population effect sizes is the assumption of a normal distribution. Even if no negative results are observed, the assumption leads to the conclusion that negative effects were obtained but suppressed. But researchers are flexible and it is more likely that they would change the prediction in the direction of a significant result (Kerr, 1998). Thus, it is highly likely that the predicted negative results are phantom studies that do not exist. These predicted effect sizes surely do not correspond to the positive estimates in the dataset.

With these observations in mind, we conclude that there must be some nonzero underlying effects in the studies we examined.

That sounds more reassuring than it is. We have over 800 results and some of these are not false positives. Great, now what? We do not know which of these results are true or false positives. So, we haven’t really learned anything about mortality awareness from this meta-analysis. Fortunately, the analysis of the data without the coding mistake is more conclusive. Terror management research is an example of a pathological science. Researchers conduct studies but never learn form their data because they find a way to keep their theory alive. A proper analysis shows that we can put this literature to rest. That is ok. The history of science is filled with failures. It is also filled with examples where researchers are unable to learn from their errors. However, science moves on and experimental social psychology with little priming manipulations will be a little footnote in the history books.

P.S. And z-curve works and can now also estimate effect sizes.

Selection Bias in Erik van Zwet’s Concerns about z-curve

In a blog post on Andrew Gelman’s blog, Erik van Zwet voiced serious concerns about the performance of z-curve, a meta-analytic method to detect selection bias. The main concern was that z-curve failed to detect selection bias in a scenario where most observed data come from high-powered studies (noncentrality parameter z = 4) but some come from tests of true H0 (effect size is zero, z = 0). In some cases, there may only be a couple of false positive results and that provides too little information about the file drawer of missing tests of H0).

The first problem that I already addressed is that EvZ’s criticism was invalid because it generalized from a single unrealistic scenario to all other situations and did not mention that z-curve had been validated and performed well in these situations (Schimmack, 2026).

Another selection bias in EvZ’s criticism of z-curve is that he only examined the performance of z-curve and did not compare it to the performance of other models. One advantage of z-curve is that it works even if there is little or no variation in sample sizes, which is a requirement for all regression based methods like Funnel plots, Eggert regression, or PET/PEESE. Thus, the most relevant competitor for z-curve are selection models like Vevea and Wood’s (2005) random-effects, step-function model implemented in the r-package weightr.

I tested the model using the same simulation design that was used to examine the performance of z-curve with identical data. Here I focus on the EvZ scenario where most statistically significant results come tests with high power (d = .6, N = 200, z ~ 4.24, power ~ 98%). Thus, there are few non-significant results that can be suppressed by publication bias.

All simulations had 70% selection bias. That is only 30% of the non-significant results were reported and the distribution was flat. First I examined the performance of weightr with k = 100 significant results. All 100 simulations failed to provide estimates of the selection weight for non-significant results. With k = 300 significant results, bias was detected 92% of the time. With k = 1,000, bias was detected in all 100 simulations.

I then examined performance when 20% of the significant results are false positives – and the other 80% come from the same high-powered distribution as before. Figure 1 shows results for a run with k = 1,000 significant results for z-curve. With k = 1,000 z-curve has no problem detecting the selection bias because the distribution of the significant results is clearly bimodal with the mode for the studies with weak power in the non-significant range. Z-curve shows that there are more observed significant results, observed discover rate ODR = 47% than z-curve predicts based on the distribution of the significant results, expected discovery rate, EDR = 23%. The difference is highly significant, p < .000001.

In contrast, the step-function model falsely interprets the higher percentage of non-significant results as evidence that significant results are missing, w(p-value in .025 to .5 range) = 2.24, 95% 2.05 to 2.43. The reason is that the model does not allow for bimodal distributions and assumes a normal distribution of effect sizes, which also implies a normal distribution of z-values when sample sizes are fixed. This problem with the step-function selection model was already reported by Hedges & Vevea (1995). When the simulated data matched the assumed normal distribution, the model worked well. When the distribution did not match the assumed distribution, the model produced bias estimates. The advantage of z-curve is that it does not make a strong distribution assumption and allows for bimodal distributions like the one in Figure 1.

Conclusion

This blog post shows further evidence that EvZ’ expression of concerns about z-curve are biased and do not provide a balanced account of the strengths and weaknesses of z-curve. It is unreasonable to expect a model to perform well in an edge case that also provides problems for other models. In fact, z-curve handles the problem of bimodal distributions better than other models that assume unimodal distributions. If a heterogeneous literature contains a mixture of studies that tested true and false hypotheses, z-curve is actually the superior method and there are no alternatives because most meta-analytic methods were designed to analyze data where all studies are fairly similar and variation in population effect sizes is small. However, many meta-analyses in psychology show evidence of large heterogeneity and the true distribution of effect sizes across studies is unknown. For these kind of data, z-curve is currently the most appropriate statistical tool.

Men are created equal, p-values are not.

Is there still something new to say about p-values? Yes, there is. Most discussions of p-values focus on a scenario where a researcher tests a new hypothesis computes a p-value and now has to interpret the result. The status quo follows Fisher’s – 100 year old – approach to compare the p-value to a value of .05. If the p-value is below .05 (two-sided), the inference is that the population effect size deviates from zero in the same direction as the observed effect in the sample. If the p-value is greater than .05 the results are deemed inconclusive.

This approach to the interpretation of the data assumes that we have no other information about our hypothesis or that we do not trust this information sufficiently to incorporate it in our inference about the population effect size. Over the past decade, Bayesian psychologists have argued that we should replace p-values with Bayes-Factors. The advantage of Bayes-Factors is that they can incorporate prior information to draw inferences from data. However, if no prior information is available, the use of Bayesian statistics may cause more harm than good. To use priors without prior information, Bayes-Factors are computed with generic, default priors that are not based on any information about a research question. Along with other problems of Bayes-Factors, this is not an appealing solution to the problem of p-values.

Here I introduce a new approach to the interpretation of p-values that has been called empirical Bayesian and has been successfully applied in genomics to control the field-wise false positive rate. That is, prior information does not rest on theoretical assumptions or default values, but rather on prior empirical information. The information that is used to interpret a new p-value is the distribution of prior p-values.

P-value distributions

Every study is a new study because it relies on a new sample of participants that produces sampling error that is independent of the previous studies. However, studies are not independent in other characteristics. A researcher who conducted a study with N = 40 participants is likely to have used similar sample sizes in previous studies. And a researcher who used N = 200 is also likely to have used larger sample sizes in previous studies. Researchers are also likely to use similar designs. Social psychologists, for example, prefer between-subject designs to better deceive their participants. Cognitive psychologists care less about deception and study simple behaviors that can be repeated hundreds of times within an hour. Thus, researchers who used a between-subject design are likely to have used a between-subject design in previous studies and researchers who used a within-subject design are likely to have used a within-subject design before. Researchers may also be chasing different effect sizes. Finally, researchers can differ in their willingness to take risks. Some may only test hypotheses that are derived from prior theories that have a high probability of being correct, whereas others may be willing to shoot for the moon. All of these consistent differences between researchers (i.e., sample size, effect size, research design) influence the unconditional statistical power of their studies, which is defined as the long-run probability of obtaining significant results, p < .05.

Over the past decade, in the wake of the replication crisis, interest in the distribution of p-values has increased dramatically. For example, one approach uses the distribution of significant p-values, which is known as p-curve analysis (Simonsohn et al., 2014). If p-values were obtained with questionable research practices when the null-hypothesis is true (p-hacking), the distribution of significant p-values is flat. Thus, if the distribution is monotonically decreasing from 0 to .05, the data have evidential value. Although p-curve analyses has been extended to estimate statistical power, simulation studies show that the p-curve algorithm is systematically biased when power varies across studies (Bartos & Schimmack, 2020; Brunner & Schimmack, 2020).

As shown in simulation studies, a better way to estimate power is z-curve (Bartos & Schimmack, 2020; Brunner & Schimmack, 2020). Here I show how z-curve analyses of prior p-values can be used to demonstrate that p-values from one researcher are not equal to p-values of other researchers when we take their prior research practices into account. By using this prior information, we can adjust the alpha level of individual researchers to take their research practices into account. To illustrate this use of z-curve, I first start with an illustration how different research practices influence p-value distributions.

Scenario 1: P-hacking

In the first scenario, we assume that a researcher only tests false hypotheses (i.e., the null-hypothesis is always true (Bem, 2011; Simonsohn et al., 2011). In theory, it would be easy to spot false positives because replication studies would produce produce 19 non-significant results for every significant one and significant ones would have different signs. However, questionable research practices lead to a pattern of results where only significant results in one direction are reported, which is the norm in psychology (Sterling, 1959, Sterling et al., 1995; Schimmack, 2012).

In a z-curve analysis, p-values are first converted into z-scores, z = -qnorm(p/2) with qnorm being the inverse normal function and p being a two-sided p-value. A z-curve plot shows the histogram of all z-scores, including non-significant ones (Figure 1).

Visual inspection of the z-curve plot shows that all 200 p-values are significant (on the right side of the criterion value z = 1.96). it also shows that the mode of the distribution as at the significance criterion. Most important, visual inspection shows a steep drop from the mode to the range of non-significant values. That is, while z = 1.96 is the most common value, z = 1.95 is never observed. This drop provides direct visual information that questionable research practices were used because normal sampling error cannot produce such dramatic changes in the distribution.

I am skipping the technical details how the z-curve model is fitted to the distribution of z-scores (Bartos & Schimmack, 2020). It is sufficient to know that the model is fitted to the distribution of significant z-scores with a limited number of model parameters that are equally spaced over the range of z-scores from 0 to 6 (7 parameters, z = 0, z = 1, z = 2, …. z = 6). The model gives different weights to these parameters to match the observed distribution. Based on these estimates, z-curve.2.0 computes several statistics that can be used to interpret single p-values that have been published or future p-values by the same researcher, assuming that the same research practices are used.

The most important statistic is the expected discovery rate (EDR), which corresponds to the average power of all studies that were conducted by a researcher. Importantly, the EDR is an estimate that is based on only the significant results, but makes predictions about the number of non-significant results. In this example with N = 200 participants, the EDR is 7%. Of course, we know that it really is only 5% because the expected discovery rate for true hypotheses that are tested with alpha = .05 is 5%. However, sampling error can introduce biases in our estimates. Nevertheless, even with only 200 observations, the estimate of 7% is relatively close to 5%. Thus, z-curve tells us something important about the way these p-values were obtained. They were obtained in studies with very low power that is close to the criterion value for a false positive result.

Z-curve uses bootstrap to compute confidence intervals around the point estimate of the EDR. the 95%CI ranges from 5% to 18%. As the interval includes 5%, we cannot reject the hypothesis that all tests were false positives (which in this scenario is also the correct conclusion). At the upper end we can see that mean power is low, even if some true hypotheses are being tested.

The EDR can be used for two purposes. First, it can be used to examine the extent of selection for significance by comparing the EDR to the observed discovery rate (ODR; Schimmack, 2012). The ODR is simply the percentage of significant results that was observed in the sample of p-values. In this case, this is 200 out of 200 or 100%. The discrepancy between the EDR of 7% and 100% is large and 100% is clearly outside the 95%CI of the EDR. Thus, we have strong evidence that questionable research practices were used, which we know to be true in this simulation because the 200 tests were selected from a much larger sample of 4,000 tests.

Most important for the use of z-curve to interpret p-values is the ability to estimate the maximum False Discovery Rate (Soric, 1989). The false discovery rate is the percentage of significant results that are false positives or type-I errors. The false discovery rate is often confused with alpha, the long-run probability of making a type-I error. The significance criterion ensures that no more than 5% of significant and non-significant results are false positives. When we test 4,000 false hypotheses (i.e., the null-hypothesis is true) were are not going to have more than 5% (4,000 * .05 = 200) false positive results. This is true in general and it is true in this example. However, when only significant results are published, it is easy to make the mistake to assume that no more than 5% of the published 200 results are false positives. This would be wrong because the 200 were selected to be significant and they are all false positives.

The false discovery rate is the percentage of significant results that are false positives. It no longer matters whether non-significant results are published or not. We are only concerned with the population of p-values that are below .05 (z > 1.96). In our example, the question is how many of the 200 significant results could be false positives. Soric (1989 demonstrated that the EDR limits the number of false positive discoveries. The more discoveries there are, the lower is the risk that discoveries are false. Using a simple formula, we can compute the maximum false discovery rate from the EDR.

FDR = (1/(EDR – 1)*(.05/.95), with alpha = .05

With an EDR of 7%, we obtained a maximum FDR of 68%. We know that the true FDR is 100%, thus, the estimate is too low. However, the reason is that sampling error can have dramatic effects on the FDR estimates when the EDR is low. With an EDR of 6%, the FDR estimate goes up to 82% and with an EDR estimate of 5% it is 100%. To take account of this uncertainty, we can use the 95%CI of the EDR to compute a 95%CI for the FDR estimate, 24% to 100%. Now we see that we cannot rule out that the FDR is 100%.

In short, scenario 1 introduced the use of p-value distributions to provide useful information about the risk that the published results are false discoveries. In this extreme example, we can dismiss the published p-values as inconclusive or as lacking in evidential value.

Scenario 2: The Typical Social Psychologist

It is difficult to estimate the typical effect size in a literature. However, a meta-analysis of meta-analyses suggested that the average effect size in social psychology is Cohen’s d = .4 (Richard et al., 2003). A smaller set of replication studies that did not select for significance estimated an effect size of d = .3 for social psychology (d = .2 for JPSP, d = .4 for Psych Science; Open Science Collaboration, 2015). The later estimate may include an unknown number of hypotheses where the null-hypothesis is true and the true effect size is zero. Thus, I used d = .4 as a reasonable effect size for true hypotheses in social psychology (see also LeBel, Campbell, & Loving, 2017).

It is also known that a rule of thumb in experimental social psychology was to allocate n = 20 participants to a condition, resulting in a sample size of N = 40 in studies with two groups. In a 2 x 2 design, the main effect would be tested with N = 80. However, to keep this scenario simple, I used d = .4 and N = 40 for true effects. This affords 23% power to obtain a significant result.

Finkel, Eastwick, and Reis (2017) argued that power of 25% is optimal if 75% of the hypotheses that are being tested are true. However, the assumption that 75% of hypotheses are true may be on the optimistic side. Wilson and Wixted (2018) suggested that the false discovery risk is closer to 50%. With 23% power for true hypotheses, this implies a false discovery rate of Given uncertainty about the actual false discovery rate in social psychology, I used a scenario with 50% true and 50% false hypotheses.

I kept the number of significant results at 200. To obtain 200 significant results with an equal number of true and false hypotheses, we need 1,428 tests. The 714 true hypotheses contribute 714*.23 = 164 true positives and the 714 false hypotheses produce 714*.05 = 36 false positive results; 164 + 36 = 200. This implies a false discovery rate of 36/200 = 18%. The true EDR is (714*.23+714*.05)/(714+714) = 14%.

The z-curve plot looks very similar to the previous plot, but they are not identical. Although the EDR estimate is higher, it still includes zero. The maximum FDR is well above the actual FDR of 18%, but the 95%CI includes the actual value of 18%.

A notable difference between Figure 1 and Figure 2 is the expected replication rate (ERR), which corresponds to the average power of significant p-values. It is called the estimated replication rate (ERR) because it predicts the percentage of significant results if the studies that were selected for significance were replicated exactly (Brunner & Schimmack, 2020). When power is heterogeneous, power of the studies with significant results is higher than power of studies with non-significant results (Brunner & Schimmack, 2020). In this case, with only two power values, the reason is that false positives have a much lower chance to be significant (5%) than true positives (23%). As a result, the average power of significant studies is higher than the average power of all studies. In this simulation, the true average power of significant studies is the weighted average of true and false positives with significant results, (164*.23 +36*.05)/(164+36) = 20%. Z-curve perfectly estimated this value.

Importantly, the 95% CI of the ERR, 11% to 34%, does not include zero. Thus, we can reject the null-hypotheses that all of the significant results are false positives based on the ERR. In other words, the significant results have evidential value. However, we do not know the composition of this average. It could be a large percentage of false positives and a few true hypotheses with high power or it could be many true positives with low power. We also do not know which of the 200 significant results is a true positive or a false positive. Thus, we would need to conduct replication studies to distinguish between true and false hypotheses. And given the low power, we would only have a 23% chance of successfully replicating a true positive result. This is exactly what happened with the reproducibility project. And the inconsistent results lead to debates and require further replications. Thus, we have real-world evidence how uninformative p-values are when they are obtained this way.

Social psychologists might argue that the use of small samples is justified because most hypotheses in psychology are true. Thus, we can use prior information to assume that significant results are true positives. However, this logic fails when social psychologists test false hypotheses. In this case, the observed distribution of p-values (Figure 1) is not that different from the distribution that is observed when most significant results are true positives that were obtained with low power (Figure 2). Thus, it is doubtful that this is really an optimal use of resources (Finkel et al., 2015). However, until recently this was the way experimental social psychologists conducted their research.

Scenario 3: Cohen’s Way

In 1962 (!), Cohen conducted a meta-analysis of statistical power in social psychology. The main finding was that studies had only a 50% chance to get significant results with a median effect size of d = .5. Cohen (1988) also recommended that researchers should plan studies to have 80% power. However, this recommendation was ignored.

To achieve 80% power with d = .4, researchers need N = 200 participants. Thus, the number of studies is reduced from 5 studies with N = 40 to one study with N = 200. As Finkel et al. (2017) point out, we can make more discoveries with many small studies than a few large ones. However, this ignores that the results of the small studies are difficult to replicate. This was not a concern when social psychologists did not bother to test whether their discoveries are false discoveries or whether they can be replicated. The replication crisis shows the problems of this approach. Now we have results from decades of research that produced significant p-values without providing any information whether these significant results are true or false discoveries.

Scenario 3 examines what social psychology would look like today, if social psychologists had listened to Cohen. The scenario is the same as in the second scenario, including publication bias. There are 50% false hypotheses and 50% true hypotheses with an effect size of d = .4. The only difference is that researchers used N = 200 to test their hypotheses to achieve 80% power.

With 80% power, we need 470 tests (compared to 1,428 in Scenario 2) to produce 200 significant results, 235*.80 + 235*.05 = 188 + 12 = 200. Thus, the EDR is 200/470 = 43%. The true false discovery rate is 6%. The expected replication rate is 188*.80 + 12*.05 = 76%. Thus, we see that higher power increases replicability from 20% to 76% and lowers the false discovery rate from 18% to 6%.

Figure 3 shows the z-curve plot. Visual inspection shows that Figure 3 looks very different from Figures 1 and 2. The estimates are also different. In this example, sampling error inflated the EDR to be 58%, but the 95%CI includes the true value of 46%. The 95%CI does not include the ODR. Thus, there is evidence for publication bias, which is also visible by the steep drop in the distribution at 1.96.

Even with a low EDR of 20%, the maximum FDR is only 21%. Thus, we can conclude with confidence that at least 79% of the significant results are true positives. Remember, in the previous scenario, we could not rule out that most results are false positives. Moreover, the estimated replication rate is 73%, which underestimates the true replication rate of 76%, but the 95%CI includes the true value, 95%CI = 61% – 84%. Thus, if these studies were replicated, we would have a high success rate for actual replication studies.

Just imagine for a moment what social psychology might look like in a parallel universe where social psychologists followed Cohen’s advice. Why didn’t they? The reason is that they did not have z-curve. All they had was p < .05, and using p < .05, all three scenarios are identical. All three scenarios produced 200 significant results. Moreover, as Finkel et al. (2015) pointed out, smaller samples produce 200 significant results quicker than large samples. An additional advantage of small samples is that they inflate point estimates of the population effect size. Thus, the social psychologists with the smallest samples could brag about the biggest (illusory) effect sizes as long as nobody was able to publish replication studies with larger samples that deflated effect sizes of d = .8 to d = .08 (Joy-Gaba & Nosek, 2010).

This game is over, but social psychology – and other social sciences – have published thousands of significant p-values, and nobody knows whether they were obtained using scenario 1, 2, or 3, or probably a combination of these. This is where z-curve can make a difference. P-values are no longer equal when they are considered as a data point from a p-value distribution. In scenario 1, a p-value of .01 and even a p-value of .001 has no meaning. In contrast, in scenario 3 even a p-value of .02 is meaningful and more likely to reflect a true positive than a false positive result. This means that we can use z-curve analyses of published p-values to distinguish between probably false and probably true positives.

I illustrate this with three concrete examples from a project that examined the p-value distributions of over 200 social psychologists (Schimmack, in preparation). The first example has the lowest EDR in the sample. The EDR is 11% and because there are only 210 tests, the 95%CI is wide and includes 5%.

The maximum EDR estimate is high with 41% and the 95%CI includes 100%. This suggests that we cannot rule out the hypothesis that most significant results are false positives. However, the replication rate is 57% and the 95%CI, 45% to 69%, does not include 5%. Thus, some tests tested true hypotheses, but we do not know which ones.

Visual inspection of the plot shows a different distribution than Figure 2. There are more just significant p-values, z = 2.0 to 2.2 and more large z-scores (z > 4). This shows more heterogeneity in power. A comparison of the ODR with the EDR shows that the ODR falls outside the 95%CI of the EDR. This is evidence of publication bias or the use of questionable research practices. One solution to the presence of publication bias is to lower the criterion for statistical significance. As a result, the large number of just significant results is no longer significant and the ODR decreases. This is a post-hoc correction for publication bias. For example, we can lower alpha to .005.

As expected, the ODR decreases considerably from 70% to 39%. In contrast, the EDR increases. The reason is that many questionable research practices produce a pile of just significant p-values. As these values are no longer used to fit the z-curve, it predicts a lot fewer non-significant p-values. The model now underestimates p-values between 2 and 2.2. However, these values do not seem to come from a sampling distribution. Rather they stick out like a tower. By excluding them, the p-values that are still significant with alpha = .005 look more credible. Thus, we can correct for the use of QRPs by lowering alpha and by examining whether these p-values produced interesting discoveries. At the same time, we can ignore the p-values between .05 and .005 and await replication studies to provide empirical evidence whether these hypotheses receive empirical support.

The second example was picked because it was close to the median EDR (33) and ERR (66) in the sample of 200 social psychologists.

The larger sample of tests (k = 1,529) helps to obtain more precise estimates. A comparison of the ODR, 76%, and the 95%CI of the EDR, 12% to 48%, shows that publication bias is present. However, with an EDR of 33%, the maximum FDR is only 11% and the upper limit of the 95%CI is 39%. Thus, we can conclude with confidence that fewer than 50% of the significant results are false positives, however numerous findings might be false positives. Only replication studies can provide this information.

In this example, lowering alpha to .005 did not align the ODR and the EDR. This suggests that these values come from a sampling distribution where non-significant results were not published. Thus, adjusting the there is no simple fix to adjust the significance criterion. In this situation, we can conclude that the published p-values are unlikely to be false positives, but that replication studies are needed to ensure that published significant results are not false positives.

The third example is the social psychologists with the highest EDR. In this case, the EDR is actually a little bit lower than the ODR, suggesting that there is no publication bias. The high EDR also means that the maximum FDR is very small and even the upper limit of the 95%CI is only 7%.

Another advantage of data without publication bias is that it is not necessary to exclude non-significant results from the analysis. Fitting the model to all p-values produces much tighter estimates of the EDR and the maximum FDR.

The upper limit of the 95%CI for the FDR is now 4%. Thus, we conclude that no more than 5% of the p-values less than .05 are false positives. Even p = .02 is unlikely to be a false positive. Finally, the estimated replication rate is 84% with a tight confidence interval ranging from 78% to 90%. Thus, most of the published p-values are expected to replicate in an exact replication study.

I hope these examples make it clear how useful it can be to evaluate single p-values with prior information about the p-values distribution of a lab. As labs differ in their research practices, significant p-values are also different. Only if we ignore the research context and focus on a single result p = .02 equals p = .02. But once we see the broader distribution, p-values of .02 can provide stronger evidence against the null-hypothesis than p-values of .002.

Implications

Cohen tried and failed to change the research culture of social psychologists. Meta-psychological articles have puzzled why meta-analyses of power failed to increase power (Maxwell, 2004; Schimmack, 2012; Sedelmeier & Gigerenzer, 1989). Finkel et al. (2015) provided an explanation. In a game where the winner publishes as many significant results as possible, the optimal strategy is to conduct as many studies as possible with low power. This strategy continues to be rewarded in psychology, where jobs, promotions, grants, and pay raises are based on the number of publications. Cohen (1990) said less is more, but that is not true in a science that does not self-correct and treats every p-value less than .05 as a discovery.

To improve psychology as a science, we need to change the incentive structure and author-wise z-curve analyses can do this. Rather than using p < .05 (or p < .005) as a general rule to claim discoveries, claims of discoveries can be adjusted to the research practices of a researchers. As demonstrated here, this will reward researchers who follow Cohen’s rules and punish those who use questionable practices to produce p-values less than .05 (or Bayes-Factors > 3) without evidential value. And maybe, there is a badge for credible p-values one day.

(incomplete) References

Richard, F. D., Bond, C. F., Jr., & Stokes-Zoota, J. J. (2003). One hundred years of social psychology quantitatively described. Review of General Psychology, 7, 331–363. http://dx.doi.org/10.1037/1089-2680.7.4.331

The Replicability Index Is the Most Powerful Tool to Detect Publication Bias in Meta-Analyses

Abstract

Methods for the detection of publication bias in meta-analyses were first introduced in the 1980s (Light & Pillemer, 1984). However, existing methods tend to have low statistical power to detect bias, especially when population effect sizes are heterogeneous (Renkewitz & Keiner, 2019). Here I show that the Replicability Index (RI) is a powerful method to detect selection for significance while controlling the type-I error risk better than the Test of Excessive Significance (TES). Unlike funnel plots and other regression methods, RI can be used without variation in sampling error across studies. Thus, it should be a default method to examine whether effect size estimates in a meta-analysis are inflated by selection for significance. However, the RI should not be used to correct effect size estimates. A significant results merely indicates that traditional effect size estimates are inflated by selection for significance or other questionable research practices that inflate the percentage of significant results.

Evaluating the Power and Type-I Error Rate of Bias Detection Methods

Just before the end of the year, and decade, Frank Renkewitz and Melanie Keiner published an important article that evaluated the performance of six bias detection methods in meta-analyses (Renkewitz & Keiner, 2019).

The article makes several important points.

1. Bias can distort effect size estimates in meta-analyses, but the amount of bias is sometimes trivial. Thus, bias detection is most important in conditions where effect sizes are inflated to a notable degree (say more than one-tenth of a standard deviation, e.g., from d = .2 to d = .3).

2. Several bias detection tools work well when studies are homogeneous (i.e. ,the population effect sizes are very similar). However, bias detection is more difficult when effect sizes are heterogeneous.

3. The most promising tool for heterogeneous data was the Test of Excessive Significance (Francis, 2013; Ioannidis, & Trikalinos, 2013). However, simulations without bias showed that the higher power of TES was achieved by a higher false-positive rate that exceeded the nominal level. The reason is that TES relies on the assumption that all studies have the same population effect size and this assumption is violated when population effect sizes are heterogeneous.

This blog post examines two new methods to detect publication bias and compares them to the TES and the Test of Insufficient Variance (TIVA) that performed well when effect sizes were homogeneous (Renkewitz & Keiner , 2019). These methods are not entirely new. One method is the Incredibility Index, which is similar to TES (Schimmack, 2012). The second method is the Replicability Index, which corrects estimates of observed power for inflation when bias is present.

The Basic Logic of Power-Based Bias Tests

The mathematical foundations for bias tests based on statistical power were introduced by Sterling et al. (1995). Statistical power is defined as the conditional probability of obtaining a significant result when the null-hypothesis is false. When the null-hypothesis is true, the probability of obtaining a significant result is set by the criterion for a type-I error, alpha. To simplify, we can treat cases where the null-hypothesis is true as the boundary value for power (Brunner & Schimmack, 2019). I call this unconditional power. Sterling et al. (1995) pointed out that for studies with heterogeneity in sample sizes, effect sizes or both, the discoery rate; that is the percentage of significant results, is predicted by the mean unconditional power of studies. This insight makes it possible to detect bias by comparing the observed discovery rate (the percentage of significant results) to the expected discovery rate based on the unconditional power of studies. The empirical challenge is to obtain useful estimates of unconditional mean power, which depends on the unknown population effect sizes.

Ioannidis and Trialinos (2007) were the first to propose a bias test that relied on a comparison of expected and observed discovery rates. The method is called Test of Excessive Significance (TES). They proposed a conventional meta-analysis of effect sizes to obtain an estimate of the population effect size, and then to use this effect size and information about sample sizes to compute power of individual studies. The final step was to compare the expected discovery rate (e.g., 5 out of 10 studies) with the observed discovery rate (8 out of 10 studies) with a chi-square test and to test the null-hypothesis of no bias with alpha = .10. They did point out that TES is biased when effect sizes are heterogeneous (see Renkewitz & Keiner, 2019, for a detailed discussion).

Schimmack (2012) proposed an alternative approach that does not assume a fixed effect sizes across studies, called the incredibility index. The first step is to compute observed-power for each study. The second step is to compute the average of these observed power estimates. This average effect size is then used as an estimate of the mean unconditional power. The final step is to compute the binomial probability of obtaining as many or more significant results that were observed for the estimated unconditional power. Schimmack (2012) showed that this approach avoids some of the problems of TES when effect sizes are heterogeneous. Thus, it is likely that the Incredibility Index produces fewer false positives than TES.

Like TES, the incredibility index has low power to detect bias because bias inflates observed power. Thus, the expected discovery rate is inflated, which makes it a conservative test of bias. Schimmack (2016) proposed a solution to this problem. As the inflation in the expected discovery rate is correlated with the amount of bias, the discrepancy between the observed and expected discovery rate indexes inflation. Thus, it is possible to correct the estimated discovery rate by the amount of observed inflation. For example, if the expected discovery rate is 70% and the observed discovery rate is 90%, the inflation is 20 percentage points. This inflation can be deducted from the expected discovery rate to get a less biased estimate of the unconditional mean power. In this example, this would be 70% – 20% = 50%. This inflation-adjusted estimate is called the Replicability Index. Although the Replicability Index risks a higher type-I error rate than the Incredibility Index, it may be more powerful and have a better type-I error control than TES.

To test these hypotheses, I conducted some simulation studies that compared the performance of four bias detection methods. The Test of Insufficient Variance (TIVA; Schimmack, 2015) was included because it has good power with homogeneous data (Renkewitz & Keiner, 2019). The other three tests were TES, ICI, and RI.

Selection bias was simulated with probabilities of 0, .1, .2, and 1. A selection probability of 0 implies that non-significant results are never published. A selection probability of .1 implies that there is a 10% chance that a non-significant result is published when it is observed. Finally, a selection probability of 1 implies that there is no bias and all non-significant results are published.

Effect sizes varied from 0 to .6. Heterogeneity was simulated with a normal distribution with SDs ranging from 0 to .6. Sample sizes were simulated by drawing from a uniform distribution with values between 20 and 40, 100, and 200 as maximum. The number of studies in a meta-analysis were 5, 10, 20, and 30. The focus was on small sets of studies because power to detect bias increases with the number of studies and power was often close to 100% with k = 30.

Each condition was simulated 100 times and the percentage of significant results with alpha = .10 (one-tailed) was used to compute power and type-I error rates.

RESULTS

Bias

Figure 1 shows a plot of the mean observed d-scores as a function of the mean population d-scores. In situations without heterogeneity, mean population d-scores corresponded to the simulated values of d = 0 to d = .6. However, with heterogeneity, mean population d-scores varied due to sampling from the normal distribution of population effect sizes.


The figure shows that bias could be negative or positive, but that overestimation is much more common than underestimation.  Underestimation was most likely when the population effect size was 0, there was no variability (SD = 0), and there was no selection for significance.  With complete selection for significance, bias always overestimated population effect sizes, because selection was simulated to be one-sided. The reason is that meta-analysis rarely show many significant results in both directions.  

An Analysis of Variance (ANOVA) with number of studies (k), mean population effect size (mpd), heterogeneity of population effect sizes (SD), range of sample sizes (Nmax) and selection bias (sel.bias) showed a four-way interaction, t = 3.70.   This four-way interaction qualified main effects that showed bias decreases with effect sizes (d), heterogeneity (SD), range of sample sizes (N), and increased with severity of selection bias (sel.bias).  

The effect of selection bias is obvious in that effect size estimates are unbiased when there is no selection bias and increases with severity of selection bias.  Figure 2 illustrates the three way interaction for the remaining factors with the most extreme selection bias; that is, all non-significant results are suppressed. 

The most dramatic inflation of effect sizes occurs when sample sizes are small (N = 20-40), the mean population effect size is zero, and there is no heterogeneity (light blue bars). This condition simulates a meta-analysis where the null-hypothesis is true. Inflation is reduced, but still considerable (d = .42), when the population effect is large (d = .6). Heterogeneity reduces bias because it increases the mean population effect size. However, even with d = .6 and heterogeneity, small samples continue to produce inflated estimates by d = .25 (dark red). Increasing sample sizes (N = 20 to 200) reduces inflation considerably. With d = 0 and SD = 0, inflation is still considerable, d = .52, but all other conditions have negligible amounts of inflation, d < .10.

As sample sizes are known, they provide some valuable information about the presence of bias in a meta-analysis. If studies with large samples are available, it is reasonable to limit a meta-analysis to the larger and more trustworthy studies (Stanley, Jarrell, & Doucouliagos, 2010).

Discovery Rates

If all results are published, there is no selection bias and effect size estimates are unbiased. When studies are selected for significance, the amount of bias is a function of the amount of studies with non-significant results that are suppressed. When all non-significant results are suppressed, the amount of selection bias depends on the mean power of the studies before selection for significance which is reflected in the discovery rate (i.e., the percentage of studies with significant results). Figure 3 shows the discovery rates for the same conditions that were used in Figure 2. The lowest discovery rate exists when the null-hypothesis is true. In this case, only 2.5% of studies produce significant results that are published. The percentage is 2.5% and not 5% because selection also takes the direction of the effect into account. Smaller sample sizes (left side) have lower discovery rates than larger sample sizes (right side) because larger samples have more power to produce significant results. In addition, studies with larger effect sizes have higher discovery rates than studies with small effect sizes because larger effect sizes increase power. In addition, more variability in effect sizes increases power because variability increases the mean population effect sizes, which also increases power.

In conclusion, the amount of selection bias and the amount of inflation of effect sizes varies across conditions as a function of effect sizes, sample sizes, heterogeneity, and the severity of selection bias. The factorial design covers a wide range of conditions. A good bias detection method should have high power to detect bias across all conditions with selection bias and low type-I error rates across conditions without selection bias.

Overall Performance of Bias Detection Methods

Figure 4 shows the overall results for 235,200 simulations across a wide range of conditions. The results replicate Renkewitz and Keiner’s finding that TES produces more type-I errors than the other methods, although the average rate of type-I errors is below the nominal level of alpha = .10. The error rate of the incredibility index is practically zero, indicating that it is much more conservative than TES. The improvement for type-I errors does not come at the cost of lower power. TES and ICI have the same level of power. This finding shows that computing observed power for each individual study is superior than assuming a fixed effect size across studies. More important, the best performing method is the Replicability Index (RI), which has considerably more power because it corrects for inflation in observed power that is introduced by selection for significance. This is a promising results because one of the limitation of the bias tests examined by Renkewitz and Keiner was the low power to detect selection bias across a wide range of realistic scenarios.

Logistic regression analyses for power showed significant five-way interactions for TES, IC, and RI. For TIVA, two four-way interactions were significant. For type-I error rates no four-way interactions were significant, but at least one three-way interaction was significant. These results show that results systematic vary in a rather complex manner across the simulated conditions. The following results show the performance of the four methods in specific conditions.

Number of Studies (k)

Detection of bias is a function of the amount of bias and the number of studies. With small sets of studies (k = 5), it is difficult to detect power. In addition, low power can suppress false-positive rates because significant results without selection bias are even less likely than significant results with selection bias. Thus, it is important to examine the influence of the number of studies on power and false positive rates.

Figure 5 shows the results for power. TIVA does not gain much power with increasing sample sizes. The other three methods clearly become more powerful as sample sizes increase. However, only the R-Index shows good power with twenty studies and still acceptable studies with just 10 studies. The R-Index with 10 studies is as powerful as TES and ICI with 10 studies.

Figure 6 shows the results for the type-I error rates. Most important, the high power of the R-Index is not achieved by inflating type-I error rates, which are still well-below the nominal level of .10. A comparison of TES and ICI shows that ICI controls type-I error much better than TES. TES even exceeds the nominal level of .10 with 30 studies and this problem is going to increase as the number of studies gets larger.

Selection Rate

Renkewitz and Keiner noticed that power decreases when there is a small probability that non-significant results are published. To simplify the results for the amount of selection bias, I focused on the condition with n = 30 studies, which gives all methods the maximum power to detect selection bias. Figure 7 confirms that power to detect bias deteriorates when non-significant results are published. However, the influence of selection rate varies across methods. TIVA is only useful when only significant results are selected, but even TES and ICI have only modest power even if the probability of a non-significant result to be published is only 10%. Only the R-Index still has good power, and power is still higher with a 20% chance to select a non-significant result than with a 10% selection rate for TES and ICI.

Population Mean Effect Size

With complete selection bias (no significant results), power had ceiling effects. Thus, I used k = 10 to illustrate the effect of population effect sizes on power and type-I error rates. (Figure 8)

In general, power decreased as the population mean effect sizes increased. The reason is that there is less selection because the discovery rates are higher. Power decreased quickly to unacceptable levels (< 50%) for all methods except the R-Index. The R-Index maintained good power even with the maximum effect size of d = .6.

Figure 9 shows that the good power of the R-Index is not achieved by inflating type-I error rates. The type-I error rate is well below the nominal level of .10. In contrast, TES exceeds the nominal level with d = .6.

Variability in Population Effect Sizes

I next examined the influence of heterogeneity in population effect sizes on power and type-I error rates. The results in Figure 10 show that hetergeneity decreases power for all methods. However, the effect is much less sever for the RI than for the other methods. Even with maximum heterogeneity, it has good power to detect publication bias.

Figure 11 shows that the high power of RI is not achieved by inflating type-I error rates. The only method with a high error-rate is TES with high heterogeneity.

Variability in Sample Sizes

With a wider range of sample sizes, average power increases. And with higher power, the discovery rate increases and there is less selection for significance. This reduces power to detect selection for significance. This trend is visible in Figure 12. Even with sample sizes ranging from 20 to 100, TIVA, TES, and IC have modest power to detect bias. However, RI maintains good levels of power even when sample sizes range from 20 to 200.

Once more, only TES shows problems with the type-I error rate when heterogeneity is high (Figure 13). Thus, the high power of RI is not achieved by inflating type-I error rates.

Stress Test

The following analyses examined RI’s performance more closely. The effect of selection bias is self-evident. As more non-significant results are available, power to detect bias decreases. However, bias also decreases. Thus, I focus on the unfortunately still realistic scenario that only significant results are published. I focus on the scenario with the most heterogeneity in sample sizes (N = 20 to 200) because it has the lowest power to detect bias. I picked the lowest and highest levels of population effect sizes and variability to illustrate the effect of these factors on power and type-I error rates. I present results for all four set sizes.

The results for power show that with only 5 studies, bias can only be detected with good power if the null-hypothesis is true. Heterogeneity or large effect sizes produce unacceptably low power. This means that the use of bias tests for small sets of studies is lopsided. Positive results strongly indicate severe bias, but negative results are inconclusive. With 10 studies, power is acceptable for homogeneous and high effect sizes as well as for heterogeneous and low effect sizes, but not for high effect sizes and high heterogeneity. With 20 or more studies, power is good for all scenarios.

The results for the type-I error rates reveal one scenario with dramatically inflated type-I error rates, namely meta-analysis with a large population effect size and no heterogeneity in population effect sizes.

Solutions

The high type-I error rate is limited to cases with high power. In this case, the inflation correction over-corrects. A solution to this problem is found by considering the fact that inflation is a non-linear function of power. With unconditional power of .05, selection for significance inflates observed power to .50, a 10 fold increase. However, power of .50 is inflated to .75, which is only a 50% increase. Thus, I modified the R-Index formula and made inflation contingent on the observed discovery rate.

RI2 = Mean.Observed.Power – (Observed Discovery Rate – Mean.Observed.Power)*(1-Observed.Discovery.Rate). This version of the R-Index reduces power, although power is still superior to the IC.

It also fixed the type-I error problem at least with sample sizes up to N = 30.

Example 1: Bem (2011)

Bem’s (2011) sensational and deeply flawed article triggered the replication crisis and the search for bias-detection tools (Francis, 2012; Schimmack, 2012). Table 1 shows that all tests indicate that Bem used questionable research practices to produce significant results in 9 out of 10 tests. This is confirmed by examination of his original data (Schimmack, 2018). For example, for one study, Bem combined results from four smaller samples with non-significant results into one sample with a significant result. The results also show that both versions of the Replicability Index are more powerful than the other tests.

Testp1/p
TIVA0.008125
TES0.01856
IC0.03132
RI0.0000245754
RI20.000137255

Example 2: Francis (2014) Audit of Psychological Science

Francis audited multiple-study articles in the journal Psychological Science from 2009-2012. The main problem with the focus on single articles is that they often contain relatively few studies and the simulation studies showed that bias tests tend to have low power if 5 or fewer studies are available (Renkewitz & Keiner, 2019). Nevertheless, Francis found that 82% of the investigated articles showed signs of bias, p < .10. This finding seems very high given the low power of TES in the simulation studies. It would mean that selection bias in these articles was very high and power of the studies was extremely low and homogeneous, which provides the ideal conditions to detect bias. However, the high type-I error rates of TES under some conditions may have produced more false positive results than the nominal level of .10 suggests. Moreover, Francis (2014) modified TES in ways that may have further increased the risk of false positives. Thus, it is interesting to reexamine the 44 studies with other bias tests. Unlike Francis, I coded one focal hypothesis test per study.

I then applied the bias detection methods. Table 2 shows the p-values.

YearAuthorFrancisTIVATESICRI1RI2
2012Anderson, Kraus, Galinsky, & Keltner0.1670.3880.1220.3870.1110.307
2012Bauer, Wilkie, Kim, & Bodenhausen0.0620.0040.0220.0880.0000.013
2012Birtel & Crisp0.1330.0700.0760.1930.0040.064
2012Converse & Fishbach0.1100.1300.1610.3190.0490.199
2012Converse, Risen, & Carter Karmic0.0430.0000.0220.0650.0000.010
2012Keysar, Hayakawa, &0.0910.1150.0670.1190.0030.043
2012Leung et al.0.0760.0470.0630.1190.0030.043
2012Rounding, Lee, Jacobson, & Ji0.0360.1580.0750.1520.0040.054
2012Savani & Rattan0.0640.0030.0280.0670.0000.017
2012van Boxtel & Koch0.0710.4960.7180.4980.2000.421
2011Evans, Horowitz, & Wolfe0.4260.9380.9860.6280.3790.606
2011Inesi, Botti, Dubois, Rucker, & Galinsky0.0260.0430.0610.1220.0030.045
2011Nordgren, Morris McDonnell, & Loewenstein0.0900.0260.1140.1960.0120.094
2011Savani, Stephens, & Markus0.0630.0270.0300.0800.0000.018
2011Todd, Hanko, Galinsky, & Mussweiler0.0430.0000.0240.0510.0000.005
2011Tuk, Trampe, & Warlop0.0920.0000.0280.0970.0000.017
2010Balcetis & Dunning0.0760.1130.0920.1260.0030.048
2010Bowles & Gelfand0.0570.5940.2080.2810.0430.183
2010Damisch, Stoberock, & Mussweiler0.0570.0000.0170.0730.0000.007
2010de Hevia & Spelke0.0700.3510.2100.3410.0620.224
2010Ersner-Hershfield, Galinsky, Kray, & King0.0730.0040.0050.0890.0000.013
2010Gao, McCarthy, & Scholl0.1150.1410.1890.3610.0410.195
2010Lammers, Stapel, & Galinsky0.0240.0220.1130.0610.0010.021
2010Li, Wei, & Soman0.0790.0300.1370.2310.0220.129
2010Maddux et al.0.0140.3440.1000.1890.0100.087
2010McGraw & Warren0.0810.9930.3020.1480.0060.066
2010Sackett, Meyvis, Nelson, Converse, & Sackett0.0330.0020.0250.0480.0000.011
2010Savani, Markus, Naidu, Kumar, & Berlia0.0580.0110.0090.0620.0000.014
2010Senay, Albarracín, & Noguchi0.0900.0000.0170.0810.0000.010
2010West, Anderson, Bedwell, & Pratt0.1570.2230.2260.2870.0320.160
2009Alter & Oppenheimer0.0710.0000.0410.0530.0000.006
2009Ashton-James, Maddux, Galinsky, & Chartrand0.0350.1750.1330.2700.0250.142
2009Fast & Chen0.0720.0060.0360.0730.0000.014
2009Fast, Gruenfeld, Sivanathan, & Galinsky0.0690.0080.0420.1180.0010.030
2009Garcia & Tor0.0891.0000.4220.1900.0190.117
2009González & McLennan0.1390.0800.1940.3030.0550.208
2009Hahn, Close, & Graf0.3480.0680.2860.4740.1750.390
2009Hart & Albarracín0.0350.0010.0480.0930.0000.015
2009Janssen & Caramazza0.0830.0510.3100.3920.1150.313
2009Jostmann, Lakens, & Schubert0.0900.0000.0260.0980.0000.018
2009Labroo, Lambotte, & Zhang0.0080.0540.0710.1480.0030.051
2009Nordgren, van Harreveld, & van der Pligt0.1000.0140.0510.1350.0020.041
2009Wakslak & Trope0.0610.0080.0290.0650.0000.010
2009Zhou, Vohs, & Baumeister0.0410.0090.0430.0970.0020.036

The Figure shows the percentage of significant results for the various methods. The results confirm that despite the small number of studies, the majority of multiple-study articles show significant evidence of bias. Although statistical significance does not speak directly to effect sizes, the fact that these tests were significant with a small set of studies implies that the amount of bias is large. This is also confirmed by a z-curve analysis that provides an estimate of the average bias across all studies (Schimmack, 2019).

A comparison of the methods shows with real data that the R-Index (RI1) is the most powerful method and even more powerful than Francis’s method that used multiple studies from a single study. The good performance of TIVA shows that population effect sizes are rather homogeneous as TIVA has low power with heterogeneous data. The Incredibility Index has the worst performance because it has an ultra-conservative type-I error rate. The most important finding is that the R-Index can be used with small sets of studies to demonstrate moderate to large bias.

Discussion

In 2012, I introduced the Incredibility Index as a statistical tool to reveal selection bias; that is, the published results were selected for significance from a larger number of results. I compared the IC with TES and pointed out some advantages of averaging power rather than effect sizes. However, I did not present extensive simulation studies to compare the performance of the two tests. In 2014, I introduced the replicability index to predict the outcome of replication studies. The replicability index corrects for the inflation of observed power when selection for significance is present. I did not think about RI as a bias test. However, Renkewitz and Keiner (2019) demonstrated that TES has low power and inflated type-I error rates. Here I examined whether IC performed better than TES and I found it did. Most important, it has much more conservative type-I error rates even with extreme heterogeneity. The reason is that selection for significance inflates observed power which is used to compute the expected percentage of significant results. This led me to see whether the bias correction that is used to compute the Replicability Index can boost power, while maintaining acceptable type-I error rates. The present results shows that this is the case for a wide range of scenarios. The only exception are meta-analysis of studies with a high population effect size and low heterogeneity in effect sizes. To avoid this problem, I created an alternative R-Index that reduces the inflation adjustment as a function of the percentage of non-significant results that are reported. I showed that the R-Index is a powerful tool that detects bias in Bem’s (2011) article and in a large number of multiple-study articles published in Psychological Science. In conclusion, the replicability index is the most powerful test for the presence of selection bias and it should be routinely used in meta-analyses to ensure that effect sizes estimates are not inflated by selective publishing of significant results. As the use of questionable practices is no longer acceptable, the R-Index can be used by editors to triage manuscripts with questionable results or to ask for a new, pre-registered, well-powered additional study. The R-Index can also be used in tenure and promotion evaluations to reward researchers that publish credible results that are likely to replicate.

References

Francis, G. (2013). Replication, statistical consistency, and publication bias. Journal of Mathematical Psychology, 57, 153–169. https://doi.org/10.1016/j.jmp.2013.02.003

Ioannidis, J. P. A., & Trikalinos, T. A. (2007). An exploratory test for an excess of significant findings. Clinical Trials: Journal of the Society for Clinical Trials, 4, 245–253. https://doi.org/10.1177/1740774507079441

 R. J. Light; D. B. Pillemer (1984). Summing up: The Science of Reviewing Research. Cambridge, Massachusetts: Harvard University Press.

Renkewitz, F., & Keiner, M. (2019). How to Detect Publication Bias in Psychological Research
A Comparative Evaluation of Six Statistical Methods. Zeitschrift für Psychologie, 227, 261-279. https://doi.org/10.1027/2151-2604/a000386.

Schimmack, U. (2012). The ironic effect of significant results on the credibility of multiple-study articles. Psychological Methods, 17, 551–566. doi:10.1037/a0029487

Schimmack, U. (2014, December 30). The test of insufficient variance (TIVA): A new tool for the detection of questionable research practices [Blog Post]. Retrieved from http://replicationindex.com/2014/12/30/the-test-ofinsufficient-
variance-tiva-a-new-tool-for-the-detection-ofquestionable-
research-practices/

Schimmack, U. (2016). A revised introduction to the R-Index. Retrieved
from https://replicationindex.com/2016/01/31/a-revisedintroduction-
to-the-r-index/

Sterling, T. D., Rosenbaum, W. L., & Weinkam, J. J. (1995). Publication decisions revisited: The effect of the outcome of statistical tests on the decision to publish and vice versa. The American Statistician, 49, 108–112.

Baby Einstein: The Numbers Do Not Add Up

A small literature suggests that babies can add and subtract. Wynn (1992) showed 5-month olds a Mickey Mouse doll, covered this toy, and placed another doll behind the cover to imply addition (1 + 1 = 2). A second group of infants saw two Mickey Mouse dolls, that were covered and then one Mickey Mouse was removed (2 – 1 = 1). When the cover was removed, either 1 or 2 Mickeys were visible. Infants looked longer at the incongruent display, suggesting that they expected 2 Mickeys in the addition scenario and one Mickey in the subtraction scenario.

Both studies produced just significant results; Study 1, t(30) = 2.078, p = .046 (two-tailed), Study 2 , t(14) = 1.795, p = .047 (one-tailed). Post-2011, these just significant results raise a red flag about the replicability of these results.

This study produced a small literature that was meta-analyzed by Christodoulou, Lac, and Moore (2017). The headline finding was that a random-effects meta-analysis showed a significant effect, d = .34, “suggesting that the phenomenon Wynn originally reported is reliable.”

The problem with effect-size meta-analysis is that effect sizes are inflated when published results are selected for significance. Christodoulou et al. (2017) examined the presence of publication bias using a variety of statistical tests that produced inconsistent results. The Incredibility Index showed that there were just as many significant results (k = 12) as one would predict based on median observed power (k = 11). Trim-and-fill suggested some bias, but the corrected effect size estimate would still be significant, d = .24. However, PEESE showed significant evidence of publication bias, and no significant effect after correcting for bias.

Christodoulou et al. (2017) dismiss the results obtained with PEESE that would suggest the findings are not robust.

For instance, the PET-PEESE has been criticized on grounds that it severely penalizes samples with a small N (Cunningham & Baumeister, 2016), is inappropriate for syntheses involving a limited number of studies (Cunningham & Baumeister, 2016), is sometimes inferior in performance compared to estimation methods that do not correct for publication bias (Reed, Florax, & Poot, 2015), and is premised on acceptance of the assumption that large sample sizes confer unbiased effect size estimates (Inzlicht, Gervais, & Berkman, 2015). Each of the other four tests used have been criticized on various grounds as well (e.g., Cunningham & Baumeister, 2016)

These arguments are not very convincing. Studies with larger samples produce more robust results than studies with smaller samples. Thus, placing a greater emphasizes on larger samples is justified by the smaller sampling error in these studies. In fact, random effects meta-analysis gives too much weight to small samples. It is also noteworthy that Baumeister and Inzlicht are not unbiased statisticians. Their work has been criticized as unreliable using PEESE and their responses are at least partially motivated by defending their work.

I will demonstrate that the PEETSE results are credible and that the other methods failed to reveal publication bias because effect-size meta-analyses fail to reveal the selection bias in original articles. For example, Wynn’s (1992) seminal finding was only significant with a one-sided test. However, the meta-analysis used a two-sided p-value of .055, which was coded as a non-significant result. This is a coding mistake because the result was used to reject the null-hypothesis with a different alpha level. A follow-up study by McCrink and Wynn (2004) reported a significant interaction effect with opposite effects for addition and subtraction, p = .016. However, the meta-analysis coded addition and subtraction separately, which produced one significant, p = .01, and one non-significant result, p = .504. The coding by subgroups is common in meta-analysis to conduct moderator analyses. However, this practices mutes the selection bias, which makes it more difficult to detect selection bias. Thus, bias tests need to be applied to the focal tests that supported authors’ main conclusions.

I recoded all 12 articles that reported 14 independent tests of the hypothesis that babies can add and subtract. I found only two articles that reported a failure to reject the null-hypothesis. Wakeley,Rivera, and Langer’s (2000) article is a rare example of an article in a major journal that reported a series of failed replication studies before 2011. “Unlike Wynn, we found no systematic evidence of either imprecise or precise adding and subtracting in young infants” (p. 1525). Moore and Cocas (2006) published two studies. Study 2 reported a non-significant result with an effect in the opposite direction. They clearly stated that this result failed to replicate Wynn’s results. “This test failed to reveal a reliable difference between the two groups’ fixation preferences, t(87) = -1.31, p = .09” However, they continued to examine the data with an Analysis of Variance that produced a significant four-way interaction, F(1, 85) = 4.80, p = .031. If this result had been used as the focal test, there would be only 2 non-significant results. However, I coded the study as reporting a non-significant result. Thus, the success rate across 14 studies in 12 articles is 11/14 = 78.6%. Without Wakeley et al.’s exceptional report of replication failures, the success rate would have been 93%, which is the norm in psychology publications (Sterling, 1959; Sterling et al., 1995).

The mean observed power of the 14 studies was MOP = 57%. The binomial probabilty of obtaining 11 or more significant results in 14 studies with 57% power is p = .080. This shows significant bias with the typical alpha level of .10 for bias tests due to the low power of these tests in small samples.

I also developed a more powerful bias tests that corrects for the inflation in the estimate of observed mean power that is based on the replicability index (Schimmack, 2016). Simulation studies show that this method has higher power, while maintaining good type-I error rates. To correct for inflation, I subtract the difference between the success rate and observed mean power from the observed mean power (simulation studies show that the mean is superior to the median that was used in the 2016 manuscript). This yields a value of .57 – (.79 – .57) = .35. The binomial probability of obtaining 11 out of 14 significant results with just 35% power is p = .001. These results confirm the results obtained with PEESE that publication bias contributes to the evidence in favor of babies’ math abilities.

To examine the credibilty of the published literature, I submitted the 11 significant results to a z-curve analysis (Brunner & Schimmack, 2019). The z-curve analysis also confirms the presence of publication bias. Whereas the observed discovery rate is 79%, 95%CI = 57% to 100%, the expected discovery rate is only 6%, 95%CI = 5% to 31%. As the confidence intervals do not overlap, the difference is statistically significant. The expected replication rate is 15%. Thus, if the 11 studies could be replicated exactly only 2 rather than 11 are expected to be significant again. The 95%CI included a value of 5% which means that all studies could be false positives. This shows that the published studies do not provide empirical evidence to reject the null-hypothesis that babies cannot add or subtract.

Meta-analyses also have another drawback. They focus on results that are common across studies. However, subsequent studies are not mere replication studies. Several studies in this literature examined whether the effect is an artifact of the experimental procedure and showed that performance is altered by changing the experimental setup. These studies first replicate the original finding and then show that the effect can be attributed to other factors. Given the low power to replicate the effect, it is not clear how credible this evidence is. However, it does show that even if the effect were robust, it does not warrant the conclusion that infants can do math.

Conclusion

The problems with bias tests in standard meta-analysis are by no means unique to this article. It is well known that original articles publish nearly exclusively confirmatory evidence with success rates over 90%. However, meta-analyses often include a much larger number of non-significant results. This paradox is explained by the coding of original studies that produces non-significant results that were either not published or not the focus of an original article. This coding practices mutes the signal and makes it difficult to detect publication bias. This does not mean that the bias has disappeared. Thus, most published meta-analysis are useless because effect sizes are inflated to an unknown degree by selection for significance in the primary literature.

The Black Box of Meta-Analysis: Personality Change

Psychologists treat meta-analyses as the gold standard to answer empirical questions. The idea is that meta-analyses combine all of the relevant information into a single number that reveals the answer to an empirical question. The problem with this naive interpretation of meta-analyses is that meta-analyses cannot provide more information than the original studies contained. If original studies have major limitations, a meta-analytic integration does not make these limitations disappear. Meta-analyses can only reduce random sampling error, but they cannot fix problems of original studies. However, once a meta-analysis is published, the problems are often ignored and the preliminary conclusion is treated as an ultimate truth.

In this regard meta-analyses are like collateralized debt obligations that were popular until problems with CDOs triggered the financial crisis in 2008. A collateralized debt obligation (CDO) pools together cash flow-generating assets and repackages this asset pool into discrete tranches that can be sold to investors. The problem is when a CDO is considered to be less risky than the actual debt in the CDO actually is and investors believe they get high returns with low risks, when the actual debt is much more risky than investors believe.

In psychology, the review process and publication in a top journal give the appeal that information is trustworthy and can be cited as solid evidence. However, a closer inspection of the original studies might reveal that the results of a meta-analysis rest on shaky foundations.

Roberts et al. (2006) published a highly-cited meta-analysis in the prestigious journal Psychological Bulletin. The key finding of this meta-analysis was that personality levels change with age in longitudinal studies of personality.

The strongest change was observed for conscientiousness. According to the figure, conscientiousness doesn’t change much during adolescence, when the prefrontal cortex is still developing, but increases from d ~ .4 to d ~ .9 from age 30 to age 70 by about half a standard deviation.

Like many other consumers, I bought the main finding and used the results in my Introduction to Personality lectures without carefully checking the meta-anlysis. However, when I analyzed new data from longitudinal studies with large national representative samples, I could not find the predicted pattern (Schimmack, 2019a, 2019b, 2019c). Thus, I decided to take a closer look at the meta-analysis.

Roberts and colleagues list all the studies that were used with information about sample sizes, personality dimensions, and the ages that were studied. Thus, it is easy to find the studies that examined conscientiousness with participants who were 30 years or older at the start of the study.

Study NWeightStart1Max.IntervalES
Costa et al. (2000)22740.4441990.00
Costa et al. (1980)4330.08366440.00
Costa & McCrae (1988)3980.0835646NA
Labouvie-Vief & Jain (2002)3000.0639639NA
Branje et al. (2004)2850.064224NA
Small et al. (2003)2230.046866NA
P. Martin (2002)1790.03655460.10
Costa & McCrae (1992)1750.0353770.06
Cramer (2003)1550.03331414NA
Haan, Millsap, & Hartka (1986)1180.02331010NA
Helson & Kwan (2000)1060.02334247NA
Helson & Wink (1992)1010.0243990.20
Grigoriadis & Fekken (1992)890.023033
Roberts et al. (2002)780.024399
Dudek & Hall (1991)700.01492525
Mclamed et al. (1974)620.013633
Cartwright & Wink (1994)400.01311515
Weinryb et al. (1992)370.013922
Wink & Helson (1993)210.00312525
Total N / Average51441.00411119

There are 19 studies with a total sample size of N = 5,144 participants. However, sample sizes vary dramatically across studies from a low of N = 21 to a high of N = 2,274. Table 1 shows the proportion of participants that would be used to weight effect sizes according to sample sizes. By far the largest study found no significant increase in conscientiousness. I tried to find information about effect sizes from the other studies, but the published articles didn’t contain means or the information was from an unpublished source. I did not bother to obtain information from samples with less than 100 participants, because they contribute only 8% to the total sample size. Even big effects would be washed out by the larger samples.

The main conclusion that can be drawn from this information is that there is no reliable information to make claims about personality change throughout adulthood. If we assume that conscientiousness changes by half a standard deviation over a 40 year period, the average effect size for a decade is d = .12. For studies with even shorter retest intervals, the predicted effect size is even weaker. It is therefore highly speculative to extrapolate from this patchwork of data and make claims about personality change during adulthood.

Fortunately, much better information is now available from longitudinal panels with over thousand participants who have been followed for 12 (SOEP) or 20 (MIDUS) years with three or four retests. Theories of personality stability and change need to be revisited in the light of this new evidence. Updating theories in the face of new data is at the basis of science. Citing an outdated meta-analysis as if it provided a timeless answer to a question is not.