Replicability Index: A Blog by Dr. Ulrich Schimmack

Blogging about statistical power, replicability, and the credibility of statistical results in psychology journals since 2014. Home of z-curve, a method to examine the credibility of published statistical results.

Show your support for open, independent, and trustworthy examination of psychological science by getting a free subscription. Register here.

“For generalization, psychologists must finally rely, as has been done in all the older sciences, on replication” (Cohen, 1994).

DEFINITION OF REPLICABILITY:  In empirical studies with sampling error, replicability refers to the probability of a study with a significant result to produce a significant result again in an exact replication study of the first study using the same sample size and significance criterion (Schimmack, 2017). 

See Reference List at the end for peer-reviewed publications.

Mission Statement

The purpose of the R-Index blog is to increase the replicability of published results in psychological science and to alert consumers of psychological research about problems in published articles.

To evaluate the credibility or “incredibility” of published research, my colleagues and I developed several statistical tools such as the Incredibility Test (Schimmack, 2012); the Test of Insufficient Variance (Schimmack, 2014), and z-curve (Version 1.0; Brunner & Schimmack, 2020; Version 2.0, Bartos & Schimmack, 2021). 

I have used these tools to demonstrate that several claims in psychological articles are incredible (a.k.a., untrustworthy), starting with Bem’s (2011) outlandish claims of time-reversed causal pre-cognition (Schimmack, 2012). This article triggered a crisis of confidence in the credibility of psychology as a science. 

Over the past decade it has become clear that many other seemingly robust findings are also highly questionable. For example, I showed that many claims in Nobel Laureate Daniel Kahneman’s book “Thinking: Fast and Slow” are based on shaky foundations (Schimmack, 2020).  An entire book on unconscious priming effects, by John Bargh, also ignores replication failures and lacks credible evidence (Schimmack, 2017).  The hypothesis that willpower is fueled by blood glucose and easily depleted is also not supported by empirical evidence (Schimmack, 2016). In general, many claims in social psychology are questionable and require new evidence to be considered scientific (Schimmack, 2020).  

Each year I post new information about the replicability of research in 120 Psychology Journals (Schimmack, 2021).  I also started providing information about the replicability of individual researchers and provide guidelines how to evaluate their published findings (Schimmack, 2021). 

Replication is essential for an empirical science, but it is not sufficient. Psychology also has a validation crisis (Schimmack, 2021).  That is, measures are often used before it has been demonstrate how well they measure something. For example, psychologists have claimed that they can measure individuals’ unconscious evaluations, but there is no evidence that unconscious evaluations even exist (Schimmack, 2021a, 2021b). 

If you are interested in my story how I ended up becoming a meta-critic of psychological science, you can read it here (my journey). 

References

Brunner, J., & Schimmack, U. (2020). Estimating population mean power under conditions of heterogeneity and selection for significance. Meta-Psychology, 4, MP.2018.874, 1-22
https://doi.org/10.15626/MP.2018.874

Schimmack, U. (2012). The ironic effect of significant results on the credibility of multiple-study articles. Psychological Methods, 17, 551–566
http://dx.doi.org/10.1037/a0029487

Schimmack, U. (2020). A meta-psychological perspective on the decade of replication failures in social psychology. Canadian Psychology/Psychologie canadienne, 61(4), 364–376. 
https://doi.org/10.1037/cap0000246

Mastodon

David Lykken’s (1971) Critique of Exploratory Factor Analysis Is Still Valid


Reference: Lykken, D. T. (1971). Multiple factor analysis and personality research. Journal of Experimental Research in Personality, 5, 161–170.

In 1971, David T. Lykken published a remarkable article titled Multiple Factor Analysis and Personality Research in the Journal of Experimental Research in Personality (now Journal of Research in Personality). More than half a century later, the article remains highly relevant to one of the fundamental problems in personality psychology:

What can we learn about the structure of personality from analyzing correlations among psychological measures with multiple factor analysis, now commonly called exploratory factor analysis (EFA)?

Factor analysis has played an enormous role in personality psychology. The Big Five, HEXACO, and various higher-order personality models are all closely connected to exploratory analyses of correlations among personality items, adjectives, or scales. Most instruments used to measure broad personality traits have been influenced by EFA results. The widespread use of these measures encourages the assumption that they measure specific traits. That is, scale scores are treated as measures of distinct underlying personality dispositions.

The basic procedure is familiar. Researchers collect a large number of personality measures, calculate their correlations, extract a smaller number of factors, rotate the solution, and assign names to the resulting dimensions. These factors often appear psychologically meaningful. They may be recognizable across datasets and may even predict important outcomes. But does this establish that the factors correspond to fundamental psychological dispositions?

Lykken thought not.

His article was written at the invitation of the journal’s editors to stimulate debate about the scientific role of factor analysis. He acknowledged Paul Meehl and Auke Tellegen for helpful comments, although he emphasized that they did not necessarily share his conclusions.

Indeed, Tellegen subsequently became an influential advocate of using EFA to identify the structure of affective experiences. Watson and Tellegen (1985) proposed that Positive Affect (PA) and Negative Affect (NA) are two largely independent dimensions of affect. Their model was based on the consistent appearance of two factors in orthogonally rotated exploratory factor analyses. This model subsequently guided the development of the widely used Positive and Negative Affect Schedule (PANAS; Watson et al., 1988).

This provides a particularly revealing example of Lykken’s concern. The independence of the two rotated factors is imposed by the orthogonal rotation procedure. It is not an empirical discovery that positive and negative emotional experiences are independent. Moreover, the PANAS scales were deliberately constructed using items with minimal secondary loadings, helping produce relatively independent scale scores.

The resulting scales may be useful measures of positive and negative activation, but their relatively low correlation does not establish that positive and negative emotional experiences are independent. The controversy illustrates how a statistical representation of a covariance matrix can be transformed into a substantive claim about psychological structure.

Thus, even within Lykken’s immediate intellectual circle, the fundamental issue he raised in 1971 remained unresolved: Does exploratory factor analysis reveal the underlying structure of psychological phenomena, or does it merely provide a convenient statistical representation of their correlations?

Lykken was not opposed to quantitative psychology or to the study of personality differences. Quite the contrary. He was an influential University of Minnesota psychologist whose research included temperament, psychophysiology, and behavioral genetics. He even coauthored a study with Tellegen showing that individual differences in subjective well-being are substantially influenced by genetic factors (Lykken & Tellegen, 1996).

Thus, Lykken’s criticism of EFA did not come from an outsider who questioned the existence or importance of personality traits. It came from a personality psychologist who regarded stable individual differences as important phenomena requiring scientific explanation but questioned whether EFA was an appropriate tool for discovering their underlying structure.

Three Uses of Factor Analysis

Lykken began by distinguishing three applications of factor analysis.

The first is data reduction. When researchers have hundreds of correlated measures, a smaller number of statistical dimensions may summarize much of the information. This can be useful, especially when the goal is to simplify a dataset without losing too much information.

The second is hypothesis testing. If a theory predicts that several measures reflect a common underlying disposition, researchers can examine whether their correlations are consistent with that prediction.

The third application is dimensional discovery: using exploratory factor analysis to discover the fundamental psychological variables responsible for individual differences.

Lykken acknowledged that factor analysis is useful for the first two aims, but he was deeply skeptical about its ability to discover dimensions that correspond to actual psychological dispositions responsible for differences in behavior and life outcomes.

In other words, EFA can help describe individual differences, but identifying statistical dimensions is not the same as discovering the psychological mechanisms that explain those differences. A factor that summarizes correlations among several measures does not necessarily represent a common cause of those correlations.

Lykken began by distinguishing three applications of factor analysis.

The first is data reduction. When researchers have hundreds of correlated measures, a smaller number of statistical dimensions may summarize much of the information. This can be useful, especially when the goal is to simplify a dataset without losing too much information.

The second is hypothesis testing. If a theory predicts that several measures reflect a common underlying disposition, researchers can examine whether their correlations are consistent with that prediction.

The third application is dimensional discovery: using exploratory factor analysis to discover the fundamental psychological variables responsible for individual differences.

Lykken acknowledged that EFA is useful for the first two aims, but he was deeply skeptical about its ability to discover dimensions that map on actual personality dispositions that explain differences in behavior and life-outcomes. In other words, EFA can help with the description of personality differences, but it cannot be used to explain behavior.

The distinction is easy to overlook because the statistical computations are similar. However, the scientific claims are radically different. A statistical factor may efficiently summarize several correlated measures without representing a distinct psychological mechanism. Conversely, a psychological mechanism may be causally important without producing a strong factor in the available measurements.

Lykken’s central criticism concerned the unwarranted movement from the first claim to the second.

The Problem With Assuming That Nature Has a Simple Factor Structure

Traditional factor analysis is often motivated by the assumption that correlations among observed variables result from a relatively small number of underlying common factors.

A classic representation is a hierarchy in which narrow characteristics reflect broader dispositions, which may themselves reflect still more general dispositions.

This arrangement has an appealing simplicity. It suggests that a complex psychological system can be understood by identifying a relatively small number of fundamental dimensions.

Lykken questioned whether biological and psychological systems actually have this organization.

He compared personality research with the study of biological organs and complex machines.

An engineer trying to understand an unfamiliar computer would not simply measure its outputs, extract factors, and assume that the resulting dimensions correspond to its internal components.

Instead, the engineer would investigate how the system operates, identify its functional subsystems, and determine how those subsystems interact.

Similarly, a biologist studying the kidney would seek to understand its anatomical and physiological organization.

Lykken emphasized that the structure of biological systems is often hierarchical, but not necessarily a neat hierarchy in which a small number of broad causes produce progressively narrower effects.

Furthermore, important biological mechanisms do not necessarily generate the largest individual differences.

A process can be essential to survival and still show little variability across healthy individuals.

Consequently, extracting the dimensions that account for the most variance does not necessarily identify the mechanisms that are most important for understanding the system.

This is a fundamental limitation of using correlations among people to discover the organization of psychological processes.

The Problem of Mixing Different Levels of Abstraction

One of Lykken’s most insightful observations concerned the levels of abstraction represented by factors.

He described unpublished analyses of anxiety items that produced factors corresponding to several different kinds of fear.

Some concerned highly specific situations, such as roller coasters. Others concerned broader categories, such as heights or physical danger. Still another represented general fearfulness.

But these characteristics do not occupy the same conceptual level.

Fear of roller coasters is a special instance of fear of heights, which overlaps with a broader fear of physical danger, which may itself reflect general fearfulness.

A single exploratory analysis had placed these dimensions alongside one another as though they represented comparable factors.

This is not merely an issue of choosing better labels.

The factor analysis did not distinguish the hierarchy of psychological characteristics that the researcher was trying to discover.

Lykken pointed out that researchers might obtain a more orderly solution if they already understood the relevant hierarchy and selected their items accordingly.

But that creates an obvious problem: if the structure is already known, what exactly has the exploratory analysis discovered?

This observation is particularly relevant to contemporary personality research.

Personality questionnaires often combine broad domain indicators, narrow facet indicators, and highly specific behavioral descriptions.

There is no guarantee that an exploratory factor analysis will identify these levels correctly.

A prominent factor might represent a broad disposition, a particularly well-represented narrow facet, or some mixture of characteristics at different levels.

The factor’s position in an exploratory solution does not settle the question.

Five Electrical Circuits: An Ingenious Demonstration

Lykken’s most convincing argument involved artificial systems whose actual structure was known.

He constructed five different electrical circuits containing resistors and capacitors.

The circuits differed in the number of components, their arrangement, and the ways in which the components were connected.

For each circuit, he generated 50 simulated individuals by varying component values. He then obtained ten measurements describing the circuit’s response to inputs at different frequencies.

These measurements were subjected to factor analysis.

If factor analysis could discover the underlying structure of such systems, the different circuits should have produced solutions revealing their different internal components.

That did not happen.

All five circuits produced two-factor solutions, despite their different internal structures.

The extracted factors were not recognizable as the actual resistors or capacitors.

An engineer familiar with the circuits could have identified their internal structure from the original measurements more directly.

The factor solutions were orderly statistical descriptions, but they did not reveal how the circuits worked.

This demonstration remains powerful because it avoids the familiar difficulty of evaluating personality research: we do not know the true psychological mechanisms in advance.

With the electrical circuits, the mechanisms were known.

The results showed that a successful factor analysis could fail to recover them.

One can object that the circuits were not designed to satisfy the assumptions of factor analysis. But that is precisely the issue.

Why should we assume that psychological systems are organized in ways that satisfy those assumptions?

A factor-analytic method may perform very well when data are generated by a factor model. That does not establish that it can discover the structure of systems generated by other kinds of mechanisms.

Factor Analysis of Automobiles: Plausible Factors Without Useful Explanations

Lykken’s second example is equally illuminating.

He collected 17 measurements from road tests of approximately 100 automobiles. The variables included engine characteristics, vehicle dimensions, acceleration, fuel economy, and price.

Four factors accounted for approximately 86% of the common variance.

The rotated factors were readily interpretable.

One factor was associated with acceleration and engine size. Another was associated with braking and price. A third characterized smaller, economical automobiles. The fourth involved measures such as hill-climbing performance, price, and oil capacity.

A researcher could assign plausible labels to these dimensions.

But would the factors help an automotive engineer understand what determines automobile performance?

Lykken argued that they would not.

Consider the association between automobile weight and acceleration.

Across the sample, heavier vehicles tended to have more powerful engines and therefore could accelerate faster.

Yet the physical relationship within an automobile is different. Holding engine power constant, increasing vehicle weight reduces acceleration.

The observed correlation across automobiles reflected how manufacturers combined different components in particular vehicle designs.

It did not reveal the causal effect of vehicle weight.

This distinction is extremely important for psychology.

A correlation across individuals does not necessarily reveal how the same variables are causally related within an individual.

For example, people who report high motivation may also report high stress. But increasing motivation within a particular individual may not increase stress in the same way.

The between-person correlation can reflect many different combinations of underlying processes.

Lykken was warning against interpreting correlations among people as though they directly revealed the organization of the mechanisms operating within people.

That warning remains relevant to modern personality theories that interpret higher-order factors as underlying regulatory or motivational systems.

Why Interpretability Is Not Enough

The electrical-circuit and automobile examples illustrate another central problem.

Factor analysis almost always produces patterns that researchers can interpret.

Once a factor is defined by its strongest loadings, psychologists are skilled at finding a plausible common theme.

A factor involving kindness, generosity, sincerity, and courtesy might be called Agreeableness.

A factor involving energy, assertiveness, and sociability might be called Extraversion.

These interpretations may be useful for describing the measures.

But assigning a meaningful label is not evidence that the factor corresponds to a distinct causal process.

This is particularly problematic when the factors are subsequently reified.

A statistical dimension called Extraversion becomes a psychological disposition called Extraversion. Researchers then explain correlated behaviors by claiming that they are caused by Extraversion.

The explanatory argument risks becoming circular.

We observe that people who describe themselves as sociable also tend to describe themselves as outgoing. We extract a common factor called Extraversion. We then explain the correlation between sociability and outgoingness by invoking Extraversion.

That explanation becomes scientifically informative only when the latent disposition has implications beyond the correlations used to define it.

This is why independent validation matters.

A personality construct becomes more credible when it predicts new observations, relates systematically to independently measured biological or behavioral processes, and survives demanding tests of competing explanations.

Factor analysis can contribute to that process, but it cannot substitute for it.

Discovery Versus Verification

Lykken’s distinction between the context of discovery and the context of verification is one of the most enduring lessons of the article.

Exploratory factor analysis can be useful for generating hypotheses.

Researchers can inspect different dimensional solutions, try alternative rotations, examine clusters of variables, and search for patterns worth investigating.

There is nothing wrong with using statistical methods creatively to identify potentially interesting relationships.

The problem arises when the exploratory procedure is treated as though it had already verified the resulting psychological theory.

Lykken described a study by Meehl, Lykken, Schofield, and Tellegen that used factor analysis to identify patterns among indicators of schizophrenia-related characteristics.

They also conducted a separate exercise in which judges attempted to reproduce factor labels from subsets of high-loading items.

This demonstrated that the factor interpretations could be reproduced without simply relying on the original researcher’s intuition.

But Lykken emphasized that such agreement did not establish that the factors represented distinct psychological mechanisms.

A cluster of related clinical ratings might reflect observer expectations, a genuine common cause, or several processes producing similar symptoms.

The labels could be reliable without the proposed explanation being correct.

This distinction is as relevant today as it was in 1971.

Replicating an exploratory factor structure across datasets is valuable evidence of a stable statistical pattern.

But it is not necessarily a decisive test of the substantive theory used to interpret that pattern.

Common Method Variance: An Especially Modern Problem

Another remarkable passage concerns a study of stress tolerance using several measurement methods.

The researchers included rating scales, perceptual-motor tests, MMPI scores, and physiological measures.

Factor analysis identified five major factors.

However, these factors were largely associated with the different methods used to collect the data.

In other words, the statistical analysis primarily recovered shared method variance rather than the psychological constructs that the researchers hoped to identify.

Lykken recognized that this was a problem for interpreting the factors.

The broader lesson is that observed covariance can arise from several sources.

Measures may correlate because they assess the same substantive characteristic. But they may also correlate because they share a method, response process, item format, or source of systematic error.

A factor analysis does not automatically distinguish these possibilities.

This problem is especially important in personality psychology, where much research relies on self-report questionnaires.

People differ not only in their substantive personality characteristics but also in how they describe and evaluate themselves.

A generally favorable self-description can produce positive correlations among desirable characteristics from different personality domains.

A corresponding tendency to reject undesirable descriptions can create additional covariance.

Such correlations may be reproduced across samples without establishing a substantive general personality disposition.

The relevant scientific task is therefore not simply to recover the covariance matrix. It is to determine which processes generate its different components.

What Lykken’s Critique Means for the Big Five

Lykken published his critique before the Big Five became the dominant taxonomy in personality psychology.

Nevertheless, his argument applies directly to contemporary lexical factor analyses.

There is substantial evidence that familiar broad dimensions recur in personality ratings. The Big Five are useful descriptive summaries, and measures based on them predict many important outcomes.

These accomplishments should not be dismissed.

But they establish less than is sometimes claimed.

The existence of five prominent dimensions in a correlation matrix does not establish that personality consists of five fundamental causal dispositions.

A five-factor solution may reflect a useful compression of a much more complicated structure.

The distinction becomes particularly important when moving from broad factors to higher-order constructs such as Stability, Plasticity, or a General Factor of Personality.

If the first-order factors are themselves mixtures of substantive dispositions and systematic measurement variance, their correlations cannot be interpreted straightforwardly as evidence for additional substantive common causes.

Extracting another factor from those correlations does not resolve the underlying measurement problem.

It simply summarizes the correlations at another level.

Lykken’s objection to interpreting statistical hierarchies as biological hierarchies is therefore especially relevant to claims about fundamental personality organization.

What Has Changed Since 1971?

Modern structural equation modeling (SEM) allows researchers to specify and compare more differentiated measurement models.

Instead of assuming that five common factors explain all shared covariance among hundreds of personality items, researchers can distinguish multiple sources of variation.

For example, a hierarchical measurement model can include:

  • Narrow personality facets measured by multiple items.
  • Broader factors representing covariance among facets.
  • Secondary loadings where items reflect more than one disposition.
  • Facet-specific residual covariance.
  • Systematic measurement factors, such as acquiescence or general evaluative halo.

This makes it possible to examine whether a proposed personality structure reproduces the observed covariance matrix after accounting for narrower substantive dimensions and measurement effects.

Structural equation modeling does not change the fact that patterns of correlations alone cannot reveal the causal mechanisms that produce them. However, it offers important advantages over conventional EFA.

EFA is essentially a restrictive measurement model that relates observed variables to unobserved factors. It separates common variance from item-specific variance, including random measurement error. However, it generally assumes that residual covariances are zero and does not distinguish substantive common variance from systematic measurement variance. Consequently, an EFA factor may reflect a mixture of substantive personality characteristics and shared measurement biases.

SEM can be used to specify more differentiated measurement models that include method factors as well as substantive factors. This makes it possible to estimate substantive trait variance separately from identifiable sources of systematic measurement error and potentially obtain more valid measures of the intended constructs.

However, these factors are still statistical representations of covariance among the observed variables. Better measurement models do not automatically reveal the causal mechanisms underlying personality differences.

The most important additional advantage of SEM is that the correlations among factors in the measurement model can be examined using structural models derived from substantive theories. This makes it possible to test whether different theories predict the observed patterns of relationships among latent constructs.

SEM is sometimes conflated with confirmatory factor analysis (CFA), and CFA is often presented as a method for confirming factor structures previously identified by EFA. This is one possible application, particularly when the goal is to develop and validate a measure of a single construct.

However, SEM is not limited to confirming exploratory factor structures. When multiple constructs are modeled simultaneously, it offers opportunities to evaluate both measurement and substantive theories.

First, researchers can test whether a theoretically specified measurement model adequately reproduces the observed covariance matrix. A model that fails this test provides a questionable basis for interpreting its factors as measures of the intended constructs.

Second, researchers can examine whether a theoretically specified structural model accounts for the correlations among these factors without producing a substantial loss of model fit.

For example, a theory may predict that several personality facets are related because they share a broader underlying disposition. Another theory may predict that the correlations arise from multiple narrower dispositions or shared measurement biases. SEM allows researchers to specify these explanations and evaluate whether their implied covariance structures are consistent with the data.

Good model fit does not prove that a causal theory is correct, because different causal models can generate the same correlations. Nevertheless, poor fit can provide evidence against a theory’s statistical implications, and comparisons among competing models can help determine which explanations remain viable.

These applications of SEM go well beyond extracting exploratory factors or confirming simple factor structures. They provide an opportunity to move from describing correlations toward testing the empirical implications of explanatory theories.

One important development is the availability of structural equation modeling.

Modern SEM allows researchers to specify and compare more differentiated measurement models.

Instead of assuming that five common factors explain all shared covariance among hundreds of personality items, researchers can distinguish multiple sources of variation.

For example, a hierarchical measurement model can include:

  • Narrow personality facets measured by multiple items.
  • Broader factors representing covariance among facets.
  • Secondary loadings where items reflect more than one disposition.
  • Facet-specific residual covariance.
  • Systematic measurement factors, such as acquiescence or general evaluative halo.

This makes it possible to examine whether a proposed personality structure reproduces the observed covariance matrix after accounting for narrower substantive dimensions and measurement effects.

Structural equation modeling does not change the fact that patterns of correlations do not reveal causal mechanisms. However, it offers important advantages over conventional EFA. EFA is essentially a restrictive measurement model that relates observed variables to unobserved factors. By separating common from unique variance, it can reduce the influence of random measurement error on estimates of common factors. However, common variance may also reflect systematic measurement error, which conventional EFA does not distinguish from substantive trait variance. SEM can be used to specify measurement models with method factors to obtain better measures of substantive factors. However, these factors are still descriptive and depend on the observed variables.

The real advantage of SEM is that the correlations among the factors in the measurement model can be modeled using structural theories that predict specific patterns of relationships among them. This makes it possible to test the empirical implications of competing causal theories.

SEM is sometimes equated with Confirmatory Factor Analysis (CFA), and it is often assumed that its only role is to confirm the results of an EFA. Confirming a previously identified factor structure is one application of CFA, but SEM can do considerably more, especially when multiple constructs are modeled simultaneously.

Here, SEM offers two important opportunities. First, it is possible to test whether a theoretically specified measurement model adequately fits the data. Second, it is possible to examine whether a structural model can explain the pattern of correlations among the latent factors without substantially reducing model fit.

These applications of SEM go well beyond EFA and the confirmation of simple factor structures. They offer an opportunity to move from description to testing the predictions of explanatory theories.

SEM was still developing as a statistical method when Lykken published his criticism of EFA in 1971. However, it subsequently became a highly influential tool in twin research for estimating genetic and environmental contributions to individual differences. Lykken used biometric structural models in his own twin research.

These analyses typically relied on personality scale scores rather than item-level measurement models that simultaneously distinguished substantive trait variance from systematic measurement variance. It would have been difficult, although not impossible, to conduct these studies using more elaborate measurement models.

For analyses of single personality traits, the additional complexity might not always have changed the main conclusions concerning genetic influences. However, accounting explicitly for measurement error and systematic method variance can change estimates of genetic and environmental contributions.

Multivariate twin models that simultaneously represented numerous personality facets, broad factors, and method effects would have been particularly challenging to estimate with the statistical software and computing resources available at the time. Advances in statistical software and computer hardware have substantially reduced these technical obstacles.

Given his skepticism about exploratory dimensional discovery in 1971, it is reasonable to ask whether Lykken would have supported contemporary efforts to replace EFA-derived sum scores with more comprehensive SEM measurement models that adequately fit the observed data.

Whether Lykken would have embraced modern SEM as a way to advance personality research remains speculative. However, his criticism of using EFA to discover the underlying structure of personality leaves little doubt that he would have been skeptical of subsequent attempts to interpret EFA-derived personality hierarchies as representations of biological systems. In particular, he explicitly rejected the assumption that biological systems have the simple hierarchical structure often imposed by factor-analytic models:

“Now the structure of organisms, while hierarchical, certainly does not have the simple-minded Christmas-tree shape envisaged by MFA” (Lykken, 1971, p. 163).

Conclusion

Why did Lykken’s criticism have so little impact on personality research, even among close colleagues with whom he collaborated?

One possible explanation is that identifying the limitations of an established method is not sufficient to change scientific practice. As Thomas Kuhn emphasized, scientific paradigms are rarely abandoned simply because their problems become apparent. Researchers also need a viable alternative that allows them to make progress.

In 1971, such an alternative was not readily available for investigating complex personality structures. Today, advances in structural equation modeling, statistical software, and computing power have made it possible to specify and test measurement models that would have been prohibitively difficult to estimate at the time.

Lykken’s criticism therefore deserves renewed attention, not because its arguments have suddenly become valid, but because researchers now have better tools to address the problems he identified. The opportunity is to move beyond extracting and naming factors toward developing and testing explicit theories of personality structure.

Two Decades of Meta-Trait Research: A Paradigm with Few Findings

A Critical Review of the Cybernetic Theory of Meta-Traits

To understand psychological science, it is necessary to understand how academia works. Research at universities is organized around paradigms (Kuhn, 1962). A paradigm consists of shared ideas, assumptions, methods, and practices—something like a scientific culture.

Psychology is organized into broader research paradigms that roughly correspond to scientific disciplines. Developmental psychologists study children and developmental changes. Experimental cognitive psychologists study mental processes, often using computer-based tasks and reaction times. Personality psychologists typically collect data from moderately large samples (often N = 100 or more), measure individual differences on multiple variables, and examine the correlations among these measures. This approach is often described as multivariate or correlational, in contrast to experimental research that manipulates independent variables to study their effects on specific outcomes.

Within the personality paradigm, we can distinguish smaller paradigms, or mini-paradigms, organized around specific theories, constructs, or measurement instruments.

For example, the life-satisfaction paradigm, strongly associated with Ed Diener’s research, focuses on subjective evaluations of people’s lives rather than an objectively defined concept of happiness. Much of this research also relies on the Satisfaction With Life Scale developed by Diener and colleagues.

Other paradigms are organized around specific models and instruments for measuring personality. The Big Five paradigm can itself be divided into smaller research traditions that use different instruments to operationalize the five broad personality dimensions. Competing paradigms, such as HEXACO, propose alternative structures and corresponding measurement instruments.

One Big Five mini-paradigm is the Cybernetic Meta-Trait Paradigm, developed by Colin DeYoung in collaboration with Jordan Peterson and colleagues beginning in 2002.

The aim of this blog post is to examine what we have learned from more than 20 years of research in this paradigm. To do so, I conducted a literature review with the assistance of my AI collaborator, which can locate, read, and summarize scientific publications much faster than I can. The objective is not simply to count publications or summarize findings, but to evaluate what this research program has contributed to our scientific understanding of personality.

What Is the Cybernetic Metatrait Paradigm?

The empirical starting point was Digman’s (1997) observation that the Big Five personality dimensions are often systematically correlated.

Digman proposed that these correlations might reflect two broader personality dispositions, which he called Alpha and Beta. These names were descriptive placeholders rather than explanations of the psychological processes responsible for the correlations.

DeYoung, Peterson, and Higgins (2002) proposed the more theoretically meaningful labels Stability and Plasticity.

Stability refers to the common variance among Agreeableness, Conscientiousness, and Emotional Stability (low Neuroticism). Plasticity refers to the common variance between Extraversion and Openness to Experience.

However, giving statistical factors psychologically meaningful names does not establish what they are. Correlations among self-reported personality characteristics cannot, by themselves, reveal the psychological mechanisms responsible for those correlations.

DeYoung subsequently developed a more comprehensive theory, presented in Cybernetic Big Five Theory (2015). This theory conceptualizes personality as a system of goal-directed regulation and adaptation. Stability reflects the maintenance of goals and organized functioning in the face of disruption, whereas Plasticity reflects exploration, adaptation, and engagement with new possibilities.

The theory thus moves beyond describing correlations among personality measures toward proposing psychological functions that might explain them.

But proposing a theory and finding empirical observations consistent with it does not establish that the theory is correct. This is particularly important in correlational research, where different causal models can generate similar patterns of observed associations. Convincing evidence for a theory therefore requires also to present evidence against competing theories. However, this work is rarely conducted by researchers within a paradigm because it acknowledges competing paradigms and the possibility that the assumptions of ones own paradigm might be false.

The central question of this review is whether research within the cybernetic meta-trait paradigm has produced findings that answer broader questions in personality research outside the paradigm.

Do the Metatraits Even Exist?

Much of the research conducted over the past two decades has focused on a more fundamental question: Do Stability and Plasticity actually exist? Are the Big Five dimensions genuinely correlated because of broader personality dispositions, or do their observed correlations arise from the way personality is measured?

Ashton and Lee (2008) challenged the interpretation of higher-order factors by emphasizing the effects of measurement and the heterogeneity of the traits represented by broad personality scales. Most research on metatraits has relied on Big Five sum scores. However, these scores combine variance associated with broad personality dimensions with variance associated with narrower characteristics that may overlap across domains.

For example, an Extraversion scale emphasizing Excitement Seeking may correlate with an Openness scale emphasizing Novelty Seeking. Both measure aspects of an adventurous disposition. In contrast, an Extraversion scale emphasizing sociability and an Openness scale emphasizing enjoyment of intellectually demanding activities, such as solving puzzles, may show much weaker correlations. Consequently, correlations among Big Five sum scores do not necessarily imply the existence of higher-order personality dispositions. They may reflect the particular content of the instruments used to measure the Big Five.

An important empirical challenge is therefore to establish that the proposed higher-order structure is not an artifact of overlapping item content, secondary factor loadings, or evaluative response biases. Recently, DeYoung and colleagues (2026) published another article arguing that Stability and Plasticity are genuine higher-order personality traits. I have critically examined the methodological problems underlying this claim in several previous blog posts (Schimmack, 2019, 2020, 2022, 2026). The most recent analysis, Lost in Factor Space: The Search for Personality Meta-Traits (Schimmack, 2026), specifically challenges the use of estimated Big Five factor scores to test hypotheses about correlations among latent personality traits.

The present review addresses a different question. For the sake of argument, I will assume that Stability and Plasticity are genuine personality dispositions. What have more than two decades of research taught us about their psychological nature, and what contributions have these constructs made to broader theories of personality?

For the sake of argument, I will assume that Stability and Plasticity are genuine personality dispositions. I will also accept the proposed hierarchical organization in which these broad dispositions influence the Big Five and, through them, narrower personality traits such as helpfulness, courage, argumentativeness, and neatness.

The question is what follows from accepting these assumptions.

What have 20 years of research taught us about the psychological nature of Stability and Plasticity? What role do these metatraits play in explaining personality and behavior?

More specifically, has the Cybernetic Metatrait Paradigm produced findings that are important for personality psychology generally, or has it mainly generated research of interest to scientists already committed to the metatrait framework?

A productive scientific paradigm should do more than demonstrate the existence of the constructs around which it is organized. It should clarify their nature, identify the mechanisms responsible for them, and explain phenomena that competing theories cannot explain equally well.

What Do Metatraits Contribute to the Prediction of Behavior and Life Outcomes?

Personality psychology has three major aims: to identify and classify personality traits, to investigate their causes, and to understand how they influence behavior, feelings, and thoughts.

Personality psychology has arguably made the greatest progress toward the third aim. Personality measures predict a wide range of behaviors and consequential life outcomes, sometimes over remarkably long periods. For example, personality characteristics assessed around the time of marriage can predict the likelihood of divorce years later.

These findings demonstrate that relatively stable individual differences contain information about people’s future lives. The challenge is to understand which dispositions are responsible for these predictions and how they influence particular outcomes.

This is where the cybernetic metatraits face a fundamental problem.

Metatraits are, by definition, more remote from specific behaviors and outcomes than the narrower personality traits they are supposed to influence. The theory proposes that Stability and Plasticity contribute to individual differences in the Big Five, which in turn contribute to more specific personality dispositions.

Consequently, under a hierarchical common-cause model, the influences of metatraits on specific outcomes should be reflected in the narrower dispositions through which they operate.

An Example: Personality and Life Satisfaction

One of the most robust findings in life-satisfaction research is that Neuroticism is among the strongest Big Five predictors of life satisfaction. People who are prone to negative emotions, worry, and dissatisfaction tend to evaluate their lives less favorably.

This is not a particularly surprising finding. What makes it important is the stability of these individual differences and their predictive associations over long periods.

However, Neuroticism is a broad personality dimension that includes several distinguishable characteristics, such as anxiety, irritability, emotional vulnerability, and depressiveness.

These narrower traits need not have identical relationships with life satisfaction.

For example, irritability may create interpersonal problems without necessarily having the same relationship with a person’s own life satisfaction as depressiveness. Anxiety may produce unpleasant experiences, but it can also motivate vigilance and avoidance of threatening situations.

The Depression facet of Neuroticism is the strongest predictor of low life-satisfaction and it is stronger than the broad Neuroticism disposition (Anglim et al., 2020; Schimmack et al., 2004). This finding shows that moving down the hierarchy towards specific traits can increase prediction and clarify the meaning of findings. So what can the meta-trait of Stability add to this finding?

Stability is defined as a higher-order disposition contributing to individual differences in Emotional Stability, Agreeableness, and Conscientiousness. For the sake of argument, assume that Stability really exists as a common psychological cause of these three personality dimensions. How would this improve our prediction of life satisfaction? It doesn’t.

Suppose depressiveness is the strongest specific predictor of life satisfaction. If Stability influences depressiveness through Neuroticism, then some portion of depressiveness reflects the influence of Stability. But this influence is already represented in the depressiveness measure. Other components of Stability could predict life satisfaction through additional pathways. For example, Conscientiousness might contribute through goal achievement, and Agreeableness through interpersonal relationships. Yet these pathways can be investigated directly by measuring the relevant narrower traits. A broad Stability score does not explain which mechanisms matter. Indeed, it risks obscuring the different ways in which personality influences life satisfaction.

A Mathematical Problem for the Predictive Utility of Metatraits

The problem is not merely that metatraits are more abstract than the Big Five. It follows from a basic property of multiple regression. Adding predictors cannot reduce the proportion of variance explained by an ordinary least-squares regression model in the same sample.

Consider Plasticity, which is defined by the shared variance between Extraversion and Openness. If we measure Extraversion and Openness separately, we can use both variables to predict any outcome. Alternatively, we can combine them into a single Plasticity score.

But the second approach cannot explain more variance than a multiple regression using both Extraversion and Openness, provided Plasticity is computed as a linear combination of those two scores. The multiple regression is free to assign different weights to Extraversion and Openness. It can therefore reproduce the prediction obtained from the Plasticity composite or improve upon it.

More generally, a multiple regression using all five Big Five scores must explain at least as much variance as one using only Stability and Plasticity scores derived from those same variables.

This is not an empirical hypothesis about the relationships between personality and life outcomes. It is a mathematical property of regression. Thus, metatraits have no inherent advantage in predicting outcomes once their constituent traits have been measured.

Why the Big Five Are Useful but Metatraits May Not Be

There is an important reason why broad personality measures such as the Big Five have become so successful. Each Big Five domain represents a large number of more specific personality characteristics.

A comprehensive assessment of personality might require hundreds of items covering dozens of facets. However, administering such extensive measures is often impractical. Big Five instruments provide an economical alternative.

For example, Neuroticism measures tend to capture variance associated with anxiety, stress sensitivity, emotional vulnerability, irritability, and depressiveness. A brief Neuroticism scale may therefore predict a variety of outcomes associated with these characteristics, even when it does not measure the most relevant specific trait very precisely.

Consider life satisfaction again. A short Neuroticism scale containing anxiety-related items may still predict life satisfaction because anxiety and depressiveness share substantial variance. The measure indirectly captures some of the depressive disposition that is particularly relevant to the outcome.

The practical advantage of the Big Five is that a small number of measures can cover a broad range of personality characteristics and predict many different outcomes. However, this advantage is much less obvious for the metatraits.

Plasticity is defined as the shared variance between Extraversion and Openness. Yet there is no independently established measure of Plasticity that does not rely on indicators of its constituent personality dimensions. Consequently, researchers typically estimate Plasticity from measures of Extraversion and Openness. Once these dimensions have been measured, however, averaging the two measures destroys important information about Extraversion and Openness.

Take life-satisfaction as an example, again. Extraversion is a positive predictor of life-satisfaction, but Openness is not (Anglim et al., 2020). These findings are informative because they suggest that characteristics associated with Extraversion, especially positive emotionality, are more relevant to life satisfaction than many of the cognitive and experiential tendencies associated with Openness.

Now suppose we average Extraversion and Openness to create a Plasticity score. We have combined a useful predictor with another variable that contributes comparatively little. Under these circumstances, averaging the two typically dilutes the predictive association and obscures the difference between the domains.

Rather than improving our understanding of life satisfaction, the Plasticity composite discards information that is scientifically relevant to explaining it.

What about Understanding Personality Traits?

The limited usefulness of metatraits for predicting behavior and life outcomes leaves understanding the structure of personality as the central objective of the metatrait paradigm.

Why are some personality traits correlated with each other? What psychological mechanisms produce these correlations? And why do some traits share variance while others are largely independent?

These questions are at the heart of Cybernetic Big Five Theory. DeYoung proposes that Stability and Plasticity are not merely statistical summaries of correlations among the Big Five, but broader psychological dispositions that help explain why these correlations exist.

The important question is what answers the meta-trait paradigm has provided to these questions. The theoretical assumptions are spelled out in DeYoung’s Cybernetic Big Five Theory (2015).

Cybernetics is the study of goal-directed systems that regulate their behavior through feedback. A thermostat is a simple example. It monitors the temperature, compares it with a desired state, and adjusts its actions to maintain that state.

Human behavior is much more complicated, but the general principle is similar. People pursue goals, monitor their progress, respond to obstacles, and adjust their behavior when circumstances change.

DeYoung argues that individual differences in personality reflect differences in the functioning of these regulatory systems. Within this framework, the two metatraits represent two fundamental requirements of adaptive behavior.

Stability is the capacity to maintain goals and organized functioning despite disruptions. It supposedly explains why people who are emotionally stable also tend to be conscientious and agreeable.

Plasticity is the capacity to explore new possibilities and adapt to changing circumstances. It supposedly explains why people who are extraverted also tend to be open to new experiences and ideas.

The theory is appealing because successful adaptation requires both functions. An organism that cannot maintain its goals will have difficulty achieving them. An organism that cannot explore new possibilities will have difficulty adapting when existing strategies no longer work.

But this general observation does not explain individual differences in personality. Everybody needs some ability to maintain goals and explore alternatives. The question is whether people differ in two general psychological capacities that produce correlations among the Big Five.

More specifically, what makes emotionally stable people more conscientious and agreeable? And why should people who enjoy social interactions also enjoy intellectual exploration?

Can We Identify the Biological Causes of Metatraits?

It is difficult to study the causal mechanisms underlying personality traits. Personality traits are relatively stable individual differences, and their biological causes are likely to involve complex interactions among genes, brain systems, and environmental influences. The challenge becomes even greater when the aim is to explain abstract dispositions such as Stability and Plasticity, rather than narrower characteristics such as anxiety, sociability, or impulsivity.

Nevertheless, Cybernetic Big Five Theory makes some relatively straightforward predictions that can be tested empirically.

The theory proposes that dopamine contributes to Plasticity, whereas serotonin contributes to Stability. One way to test these hypotheses is to examine whether drugs that alter these neurotransmitter systems produce changes in personality traits.

For example, if serotonin is a common biological cause of Stability, drugs that alter serotonergic functioning should produce coordinated changes in the three constituent Big Five dimensions: Neuroticism, Agreeableness, and Conscientiousness. Similarly, if dopamine is a common cause of Plasticity, drugs that alter dopaminergic functioning should affect both Extraversion and Openness.

Of course, neurotransmitter systems are complicated. Dopamine and serotonin act through different receptors and pathways, and pharmacological interventions are not perfectly selective. Moreover, acute changes in behavior are not necessarily equivalent to enduring changes in personality.

However, these complications do not make pharmacological studies irrelevant. They make it necessary to specify which biological mechanisms are hypothesized to influence the meta-traits and what pattern of personality changes should follow from manipulating them.

What Have Pharmacological Studies Found?

There is evidence that drugs affecting serotonergic functioning can change personality scores.

For example, Knutson et al. (1998) administered the selective serotonin reuptake inhibitor (SSRI) paroxetine or a placebo to healthy volunteers for four weeks. The treatment reduced negative affect and hostility and increased affiliative behavior.

Tang et al. (2009) conducted a placebo-controlled study of paroxetine in patients with major depression. They found substantial reductions in Neuroticism and increases in Extraversion. These effects remained significant after statistically controlling for improvements in depressive symptoms.

These findings are important because they demonstrate that pharmacological interventions can produce changes in personality measures.

However, the observed pattern does not correspond to the predictions of a simple serotonin–Stability theory.

Lower Neuroticism is consistent with an increase in Stability. But the studies do not establish corresponding increases in Agreeableness and Conscientiousness. Moreover, paroxetine increased Extraversion, which belongs to Plasticity rather than Stability.

Thus, the existing findings suggest that serotonergic interventions influence particular personality characteristics rather than demonstrating coordinated changes in the traits defining Stability.

The evidence for dopamine and Plasticity is even more limited.

Researchers have manipulated dopaminergic functioning using drugs such as haloperidol and sulpiride. However, the studies reviewed here primarily examined whether personality moderated the effects of these drugs on cognitive or behavioral tasks.

Such findings do not demonstrate that the drugs change personality traits.

The relevant experiment would be to administer a drug that alters dopaminergic functioning and examine whether Extraversion and Openness change together, as predicted by a common Plasticity mechanism.

I did not identify a controlled pharmacological study that provides this test.

Why Has There Been So Little Direct Experimental Research?

This raises a question about the scientific progress of the metatrait paradigm.

If dopamine and serotonin are central to the proposed explanations of Plasticity and Stability, why have researchers not conducted more experiments directly testing their effects on the constituent personality traits?

The metatrait paradigm has existed for more than 20 years. During this period, researchers have repeatedly examined whether Stability and Plasticity can be identified in personality data and whether metatrait scores correlate with various psychological outcomes.

Yet the central biological hypotheses have received comparatively little direct empirical investigation. Of course, pharmacological studies are expensive, ethically constrained, and difficult to interpret. Demonstrating changes in enduring personality dispositions may also require longer treatment periods and repeated assessments.

Nevertheless, the relevant research designs are feasible. Studies of antidepressant medications have already demonstrated that personality scores can change following pharmacological interventions. A research program that proposes biological causes of personality differences should ultimately investigate whether manipulating these causes produces the predicted changes.

What Has the Meta-Trait Paradigm Explained?

In conclusion, the cybernetic metatrait paradigm has produced few findings that substantially advance our understanding of personality beyond the paradigm itself.

Without independent measures of Stability and Plasticity, metatraits cannot improve the prediction of behaviors and life outcomes beyond the lower-order traits from which they are constructed. The Big Five, and especially their narrower facets, provide more detailed information about the personality characteristics that matter for particular outcomes.

The metatraits’ potential contribution is therefore primarily explanatory. If Stability and Plasticity are genuine higher-order dispositions, they might explain why certain personality traits are correlated.

However, after more than 20 years of research, the proposed biological mechanisms remain poorly understood. Theories linking Stability to serotonin and Plasticity to dopamine have generated relatively little direct experimental evidence. Moreover, the available pharmacological findings do not provide the coordinated changes in personality traits that would support a straightforward interpretation of these biological mechanisms.

This raises a broader question about the importance of the phenomenon that originally motivated the paradigm.

Digman (1997) observed surprisingly strong correlations among Big Five measures, challenging the assumption that the five major personality dimensions are largely independent.

Subsequent research demonstrated that some of these correlations reflect measurement artifacts, including evaluative biases and overlapping item content. When these influences are taken into account, correlations among the substantive Big Five dimensions are often substantially weaker.

This leaves a more limited theoretical question: Do the remaining correlations reflect systematic influences of broader personality dispositions, or do they arise from several distinct mechanisms that produce modest associations among particular traits?

That is a legitimate scientific question. However, its importance for personality psychology should not be exaggerated.

Most individual differences in personality are not captured by the two metatraits. They are found at lower levels of the personality hierarchy, including the Big Five and the many narrower dispositions that contribute to them.

These narrower traits are more closely related to the behaviors, emotions, and thoughts that personality psychologists seek to understand. They can also be connected to more specific psychological and biological mechanisms.

Consequently, research programs that focus on these lower levels of the personality hierarchy appear more promising for advancing both the prediction and explanation of personality.

The central limitation of the meta-trait paradigm is not that Stability and Plasticity may fail to exist. It is that their existence may not be particularly important.

References

Anglim, J., Horwood, S., Smillie, L. D., Marrero, R. J., & Wood, J. K. (2020). Predicting psychological and subjective well-being from personality: A meta-analysis. Psychological Bulletin, 146(4), 279–323. https://doi.org/10.1037/bul0000226

DeYoung, C. G. (2013). The neuromodulator of exploration: A unifying theory of the role of dopamine in personality. Frontiers in Human Neuroscience, 7, Article 762. https://doi.org/10.3389/fnhum.2013.00762

DeYoung, C. G. (2015). Cybernetic Big Five Theory. Journal of Research in Personality, 56, 33–58. https://doi.org/10.1016/j.jrp.2014.07.004

Schimmack, U. (2019a, August 13). When personality psychologists are high. Replicability-Index. https://replicationindex.com/2019/08/13/when-personality-psychologists-are-high/

Schimmack, U. (2019b, September 7). Testing hierarchical models of personality with confirmatory factor analysis. Replicability-Index. https://replicationindex.com/2019/09/07/testing-hierarchical-models-of-personality-with-confirmatory-factor-analysis/

Schimmack, U. (2019c, September 13). Confirmation bias is everywhere: Serotonin and the meta-trait of stability. Replicability-Index. https://replicationindex.com/2019/09/13/stability-serotonin/

Schimmack, U. (2020, October 25). No evidence for a higher-oder plasticity factor. Replicability-Index. https://replicationindex.com/2020/10/25/no-evidence-for-a-higher-oder-plasticity-factor/

Schimmack, U. (2022, January 25). More madness than genius: Meta-traits of personality. Replicability-Index. https://replicationindex.com/2022/01/25/more-madness-than-genius-meta-traits-of-personality/

Schimmack, U. (2026, October 31). Lost in factor space: The search for personality meta-traits. Replicability-Index. https://replicationindex.com/2026/10/31/lost-in-factor-space-the-search-for-personality-meta-traits/

Schimmack, U., Oishi, S., Furr, R. M., & Funder, D. C. (2004). Personality and life satisfaction: A facet-level analysis. Personality and Social Psychology Bulletin, 30(8), 1062–1075. https://doi.org/10.1177/0146167204264292

Getting Results in Structural Equation Modeling

I first learned structural equation modeling with Ralf Schwarzer at the Free University Berlin. Alexander Grob taught me how to achieve good model fit when I was a post-doctoral student at the University of Illinois. Since then I have learned by experience and with a few tips from Linda Muthen. In the beginning, I would often encounter convergence problems. That is, the software (usually MPLUS) terminated without results. Over time, I learned how to diagnose these problems and avoid them. However, knowledge about these solutions is not widely shared and I see published articles that report conversion failure as a result. However, convergence failures are not a result. They reveal a problem in testing a model that may occur for a simple reason (e.g., not specifying a negative starting value for a negative loading).

I hope that AI will make it easier for people to find problems in their code (or just ask AI to write the code), but here are some resources that I (well AI) found that may help to avoid these problems.

———————————————————————————————

Yes. There are several useful resources in the SEM community, including dedicated troubleshooting guides, tutorials with executable code, and methodological papers on model identification. Some align closely with what you are proposing for OPeRA.

The most relevant resources are these:

1. Tutorials specifically addressing convergence and identification

Where Did I Go Wrong with My Model? Ten Tips for Getting Results in SEM

Structural Equation Modeling: A Multidisciplinary Journal (2023).

A practical troubleshooting article covering identification problems, poorly fitting measurement models, convergence warnings, and stepwise model development. Probably the best general starting point. Get Access

The Empirical Check for Identification

From A lavaan Compendium for Structural Equation Modeling in Educational Research.

Particularly relevant to your concern about whether adding secondary loadings or correlated residuals makes a model unidentified. It demonstrates how to generate data from the specified model and investigate whether its parameters can be recovered. tdjorgensen.github.io

Mplus User’s Guide — Chapter 14: General Convergence Problems

Official Mplus guidance on diagnosing optimization failures, examining TECH5/TECH8 output, changing starting values, rescaling variables, and estimating parts of a model separately before assembling the full specification. This is remarkably close to your proposed diagnostic approach. statmodel.com

Video lessons on SEM convergence problems

A short instructional series shared by an SEM researcher in the lavaan discussion community. The examples use Stata, but the underlying diagnostics apply to other SEM programs. groups.google.com

2. Especially relevant to your personality models

Two additional tutorials address the kinds of complex factor structures you have been working with.

Marsh & Alamer (2024): When and How to Use Set-Exploratory Structural Equation Modelling

This open-access paper compares CFA with set-ESEM, which allows selected cross-loadings rather than requiring every secondary loading to be zero. It includes real-data examples and lavaan code.

The authors show that restrictive CFA specifications can distort factor correlations and structural parameters. This is directly relevant to your concern about the inflated HH–Agreeableness correlation in Blötner’s model. Wiley Online Library

Bifactor ESEM Tutorial

This provides executable specifications for general and specific factors. It is useful for understanding why bifactor models can become difficult to identify and what constraints different parameterizations impose. bpb-us-e1.wpmucdn.com

3. What seems to be missing

The existing resources tend to concentrate on either statistical identification or technical troubleshooting.

What I find less developed is the kind of case-based model-development tutorial you have in mind:

Start with a theoretically interesting model that does not converge. Fit simpler nested models, identify the specific component responsible for failure, investigate whether the problem is numerical or structural, impose defensible constraints, and then assess whether the resulting model provides a substantively interpretable account of the data.

Such a tutorial would also distinguish three outcomes that researchers sometimes conflate: convergence, acceptable fit, and theoretical validity.

That would be especially useful for personality researchers working with many correlated facets, secondary loadings, hierarchical structures, and method factors.

4. An opportunity for OPeRA

I would not present OPeRA as introducing convergence diagnostics to SEM. The expertise and instructional materials clearly exist.

Instead, OPeRA could bring established SEM expertise into personality-structure research, using actual personality datasets to illustrate problems that arise in complex measurement models.

It could also invite methodological specialists to contribute reproducible tutorials, with Mplus and lavaan scripts and example data.

The Jorgensen identification chapter and Marsh and Alamer’s set-ESEM paper would be particularly good foundations.

The HEXACO Paradigm: Confusing the Map With the Territory

In The Structure of Scientific Revolutions, Thomas Kuhn (1962) described how scientific communities develop around a paradigm. A paradigm involves more than a theory. It includes assumptions about what exists, which questions are worth asking, which methods are appropriate, and what constitutes acceptable evidence. These shared assumptions make cumulative research possible. However, they can also prevent researchers from recognizing the limitations of established practices.

Paradigms are like cultures, and like cultures, they can contain subcultures. For example, academic psychologists generally favor quantitative methods to provide empirical evidence for theoretical claims. Within academic psychology, experimental psychologists emphasize the manipulation of independent variables to test causal hypotheses. Personality psychologists, in contrast, rely primarily on correlational evidence because personality traits are difficult or impossible to manipulate directly.

This does not make personality psychology inherently less scientific. Astronomy also relies extensively on observational data, yet few would question its status as a science.

However, there is an important difference between astronomy and mainstream personality psychology.

Astronomers distinguish between the objects they study and the instruments used to observe them. A star is not defined by the measurements obtained with a particular telescope. Different instruments provide different information about the same object, and astronomers develop theories that explain these observations, taking the properties of the instruments into account.

Personality psychologists are less consistent in maintaining this distinction. Personality inventories often serve simultaneously as measurement instruments and definitions of the constructs they supposedly measure.

Consider Extraversion. Personality psychologists have proposed several theories about its psychological nature, emphasizing sociability, positive affect, reward sensitivity, or approach motivation. However, proposing a theory is not the same as providing empirical support for it. The existence of competing theories does not tell us which, if any, identifies the psychological disposition responsible for individual differences in Extraversion.

Meanwhile, researchers continue to use questionnaire sum scores labeled Extraversion as if the theoretical construct were already established. Different inventories combine different behaviors and characteristics, producing positively correlated but nonidentical scores. Yet there is no generally accepted explanatory model that specifies precisely what Extraversion is, demonstrates how its underlying disposition produces the observed responses, and establishes which inventory provides the most valid measurement.

Extraversion is therefore an established label for a family of correlated questionnaire scores, but not an equally well-established explanatory construct.

Another way to understand this problem is to compare personality taxonomies with geographical maps.

Maps represent real properties of Earth, including the distribution of land and water, elevation, and the location of geographical features. We can evaluate their accuracy by comparing them with observations of the physical world.

However, maps also use coordinate systems whose reference points are conventional rather than natural. Longitude provides a familiar example.

Greenwich became the internationally accepted reference for longitude in 1884. Before that, different countries used different prime meridians. The choice of Greenwich did not reveal a fundamental property of Earth. It established a common reference system that made navigation and geographical communication easier.

Changing the prime meridian changes the longitude assigned to a location. It does not change the location itself.

Personality inventories are similar to coordinate systems. They organize individual differences within a multidimensional personality space. The Big Five, the Big Five Aspect Scales, and HEXACO provide different ways of representing that space.

The existence of parallel and competing paradigms has advantages and disadvantages. The advantage is that competing paradigms can lead to empirical tests of competing predictions and lead to new discoveries. The disadvantage is that it is difficult to integrate research findings from different paradigms. For descriptive paradigms, the later problem can be resolved by translating findings from one descriptive system into another. For example, we can translate 15.00 Berlin into the local time in Sydney just like we can convert inches into centimeters or Fahrenheit into Celsius.

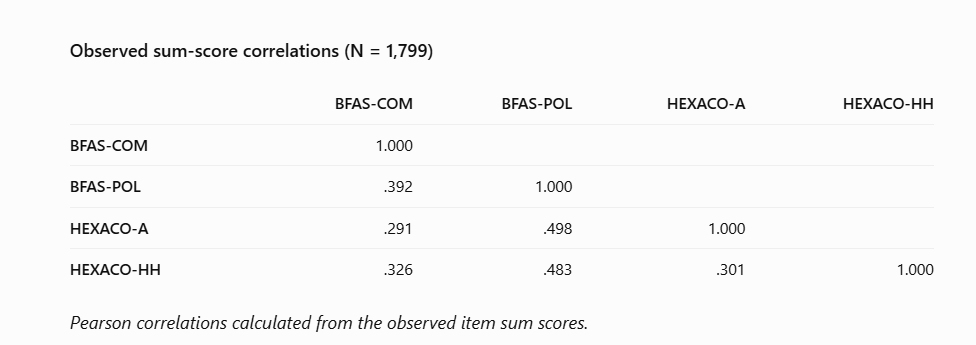
In personality space, we can use the correlations among dimensions from different inventories to translate findings from one system into another. A recent article by Ashton and Lee, the inventors of the HEXACO paradigm, provides an example. The authors focused on the description of pro- and anti-social traits with the Big Five Aspect Scales (BFAS) and their own HEXACO dimensions.

The BFAS uses two dimensions, Compassion (COM) and Politeness (POL), to represent individual differences in prosocial and antisocial characteristics. Although these names reflect the content of the scales, they do not establish that the dimensions measure compassion or politeness as independently defined psychological constructs. To avoid confusing labels with theoretical constructs, I will refer to these dimensions as BFAS-COM and BFAS-POL.

HEXACO also uses two dimensions to organize much of this domain: Agreeableness and Honesty-Humility. Importantly, HEXACO Agreeableness differs from Big Five Agreeableness, and Honesty-Humility refers to a particular combination of characteristics represented by its questionnaire items. I will therefore refer to these dimensions as HEXACO-A and HEXACO-HH.

Both systems provide two-dimensional representations of interpersonal individual differences. Specific characteristics, such as kindness, sympathy, helpfulness, forgiveness, or fairness, can be located within either system based on their correlations with the respective dimensions.

We can examine how closely these two systems correspond by calculating correlations among their four sum scores.

The correlations show that the two coordinate systems are related but not aligned. HEXACO-A correlates .29 with BFAS-COM and .50 with BFAS-POL. Similarly, HEXACO-HH correlates .33 with BFAS-COM and .48 with BFAS-POL. Thus, both HEXACO dimensions are more strongly associated with BFAS-POL than with BFAS-COM.

More importantly, these are not simply two different orientations of the same two-dimensional space. If they were, we could translate scores from one system into the other without losing information. Instead, each system captures information that is not represented by the other.

Some of this difference may reflect measurement error, but it may also reflect the fact that interpersonal personality characteristics cannot be adequately represented in just two dimensions.

The important conclusion is that BFAS and HEXACO provide different descriptive representations of interpersonal personality characteristics. Neither system can be assumed to represent the fundamental psychological structure simply because its dimensions were obtained through factor analysis.

The Confusion of Objects and Instruments in the HEXACO Paradigm

The main problem with personality paradigms organized around specific inventories is that researchers may come to treat their preferred descriptive framework as a theoretically privileged representation of personality.

Lee and Ashton (2026) provide an example. They examined the relationships between BFAS-POL and the HEXACO dimensions and concluded that BFAS Politeness is best understood as roughly an equal blend of HEXACO Agreeableness and Honesty-Humility.

This interpretation goes beyond demonstrating correlations among questionnaire scores. It suggests that the HEXACO dimensions provide the appropriate framework for understanding BFAS Politeness.

But why should we privilege the HEXACO coordinate system?

We would not claim that a location northwest of Greenwich is best understood as a blend of North and West. North and West are coordinates, not fundamental ingredients of a geographical location. A different coordinate system could describe the same location differently.

Similarly, the observation that BFAS-POL correlates with both HEXACO-A and HEXACO-HH does not establish that these HEXACO dimensions are the fundamental psychological dispositions underlying BFAS-POL.

Lee and Ashton go beyond describing correlations. They argue that personality measures must distinguish the six HEXACO dimensions for personality phenomena to be properly understood (p. 7). This is a theoretical claim about the privileged status of the HEXACO framework.

But the analyses do not establish that these six dimensions represent fundamental personality dispositions rather than one useful organization of correlated characteristics.

Observations obtained with one instrument do not explain observations obtained with another. Measurements from one telescope do not explain measurements from a second telescope. Both are observations that require an explanatory theory of the objects and processes producing them.

The same principle applies to personality questionnaires. Correlations among sum scores describe relationships among observations. They do not identify the psychological dispositions responsible for those relationships.

The methods needed to investigate these questions already exist. Structural equation modeling makes it possible to specify latent personality dispositions, distinguish them from their observed indicators, and test whether proposed measurement and structural models adequately reproduce the observed data.

I applied this approach to the same data used by Lee and Ashton, specifying a simple model of the relationships among the 40 items used to construct BFAS-COM, BFAS-POL, HEXACO-A, and HEXACO-HH. The model reproduced the broad pattern of sum-score correlations but failed to adequately reproduce the complete item covariance structure.

The purpose here is not to present an alternative model or claim that a particular personality theory is correct. The point is that an explanatory interpretation should be formulated as a testable model rather than inferred from correlations among questionnaire scores.

There is also a broader problem with the competing descriptive frameworks.

Neither BFAS nor the two HEXACO dimensions provide a comprehensive representation of prosocial and antisocial personality characteristics. The HEXACO dimensions capture much more of the information represented by BFAS-POL than by BFAS-COM. Conversely, HEXACO-HH represents characteristics that are only partly captured by BFAS-POL.

These differences suggest that interpersonal personality characteristics may require more than two dimensions for an adequate representation. Measurement error and differences in item content may also contribute to the imperfect correspondence.

The fundamental question is not whether BFAS or HEXACO provides the better map of personality space. It is whether we can develop and empirically test theories of the psychological dispositions that these maps attempt to represent.

Until we distinguish theoretical constructs from the instruments used to measure them, personality psychology risks confusing its coordinate systems with the underlying structure of personality.

Lost in Factor Space: The Search for Personality Meta-Traits

Shaky Scientific (Epistemiological) Foundations of Personality Psychology

Personality psychology lacks solid scientific foundations. Behaviorism was impoverished, but at least it was based on clear rules. Only the effects of situational manipulations on observable behavior were admissible empirical observations, and theories were not allowed to invoke metaphysical constructs like thoughts and feelings to explain behavior.

Modern empirical psychology has moved on from behaviorism, but behaviorism still influences the thinking of psychologists without their awareness. Personality psychology survived behaviorism, but it kept one of its rules: causal questions can only be answered with experiments. This is a problem for a research area that cannot run experiments with random assignment to study causality.

Are taller people more confident because of their height? We cannot simply assign people to a tall or short condition, alter their height, and see what happens. Behaviorism simply decided that such questions are not psychological questions. Nowadays, hundreds of articles report correlations of personality traits with each other or other variables, but personality psychologists have not revised the way they think about causality.

For the most part, they have accepted that observational research cannot test causal theories and frame their research in terms of prediction: can my personality item sum score predict something of interest? For example, does a Conscientiousness scale predict GPA? The answer is yes, the correlation is about r = .2, and no definition of conscientiousness or causal theory is needed to explain the correlation.

However, personality psychologists sometimes make causal assumptions, even if these assumptions are not spelled out explicitly to avoid criticism of causal claims based on correlational research.

The most common causal assumption in personality research is that responses to similar items correlate because they measure a common trait. For example, responses to the items “I am talkative” and “I am outgoing” are correlated, and this correlation is used as evidence that both items measure a common trait, a personality disposition. This justifies averaging the responses to create a personality item sum score and calling it sociability. Importantly, the name of a personality item sum score is arbitrary. It could also be called T346, or “that thing that is reflected in the shared variance between responses to items like talkative and outgoing.”

No theoretical definition of a construct and no theory of measurement is needed. Sociability is whatever a specific sociability scale measures. Here lies the contradiction: a causal assumption, a common trait, is used to justify summing the items, and then an operational definition is used to avoid ever testing that assumption.

The problem with this approach to measurement becomes more obvious when we go beyond correlations among items that are synonymous or semantically similar. For example, take the items “I am often in a good mood” and “I am talkative.” Responses to these items are also positively correlated, but the items have distinct meanings. While it may be easier to imagine that people in a good mood talk a lot, it is also easy to imagine people who are in a good mood while absorbed in a solitary activity (flow) without engaging in any social interaction.

Research on the relationships among specific traits like sociability, good humor, anxiety, and anger is nearly 100 years old and took off when Thurstone (1934) developed multiple-factor analysis to study these relationships systematically. In the 1980s, the Big Five model emerged, and it has dominated personality psychology for nearly half a century. However, a clear definition of the Big Five is still elusive.

The reason is that personality psychologists rarely study the Big Five factors. Instead, they create more and more Big Five scales that average a set of items and are given Big Five names. The problem is that these sum scores depend on the items that are summed, and different sum scores produce different results. Thus, Extraversion is not a clearly defined construct. It is a label for scales that tend to correlate moderate to highly with each other because they contain overlapping sets of related items.

These sum scores cannot be used to study the Big Five factors. For example, we can create an Extraversion sum score by averaging the items “I am often in a good mood” and “I talk a lot.” Now we can show that this sum score correlates with a Good Humor scale that contains the item “I am often in a good mood” and with a Sociability scale that contains the item “I talk a lot.” However, these correlations are no longer empirical observations of something interesting. Scales that share items will be correlated, just as 6 and 9 are both divisible by 3 because both are products of 3 and another number (3 × 2 = 6, 3 × 3 = 9). The shared items guarantee the correlation, just as the shared factor of 3 guarantees divisibility.

Unfortunately, many personality psychologists seem unable to realize that these correlations do not tell us anything theoretically interesting or are simply not interested in scientific theories of personality. To examine why Good Humor and Sociability are correlated we need distinct measures of each construct not sum scores that average across items from both measures.

But when faced with a correlation between two observed measures, the alarm bells go off because we are now asking a causal question without experimental evidence. As this is considered improper, the question is never asked.

The simple solution to this problem is to shed the experimental dogma and treat personality psychology like any other science that cannot manipulate the objects it studies. Take astronomy as an example. We resolved the question whether Earth revolves around the sun or vice versa without randomly assigning planets and stars to different experimental conditions. Welcome to personality science, where we test causal theories without random assignment and without directly observable phenomena.

In personality science, Big Five theory makes clear predictions. It assumes that correlations among specific traits are influenced by five broader dispositions. People who are more often in a good mood are also more likely to be talkative because both dispositions reflect a broader disposition called Extraversion. Importantly, Extraversion is just a label, and it is confusing to use the everyday meaning of the term as if we knew what this broader disposition is. A better name might be Factor I, following the numbering of the factors in the lexical tradition (Norman, 1963; Goldberg, 1990), which evokes no associations with bubbly conversation partners.

The nature of Factor I is unknown, but we infer that it exists from the observation that Good Humor and Sociability are correlated. This makes Factor I a causal theory, and the theory could be wrong. Maybe there is another reason why the two traits are correlated. Personality psychologists avoid testing this theory by using sum scores and giving them labels. A sum score is simply a fact about how people answered a set of questions; no theory is needed to call it Extraversion. To keep the two apart, we can refer to factors by number (Factor I) and to scale scores by their labels, together with the instrument used: BFI Extraversion, BFI-2 Extraversion, NEO-FFI Extraversion, and so on. A scale can be used without examining whether it is related to Factor I, or without knowing what Factor I is. How well BFI Extraversion measures Factor I is an empirical question, and the answer may differ for each instrument.

From Exploratory Factor Analysis to Confirmatory Factor Analysis

Thurstone’s original method was exploratory factor analysis (EFA). It did not impose constraints on the relationships between specific traits and broader factors. Researchers chose the number of factors, and the method produced the best possible loadings (the relationships between observed variables and factors) given the correlations among the measures. The model usually did not reproduce all of the correlations, but fit to the data was not a major concern. Often the goal was not to test a theory, but simply to reduce a large number of items to a few sum scores.

Since then, the measurement methods have been developed further in a field called psychometrics. In psychometric measurement models, correlations among items are also explained by unobserved factors (often called latent variables), but these models differ from EFA in two important ways. First, researchers can specify a predicted pattern of loadings and thereby test a theory about why items are correlated; this approach is called confirmatory factor analysis (CFA; Jöreskog, 1969). Second, a good theory should explain the full pattern of correlations, so model fit matters.

Personality psychologists tried these methods to find evidence for Big Five theory, but their models did not fit the data (McCrae et al., 1996). Instead of asking whether their theory might be at least partially wrong, they concluded that confirmatory factor analysis is not appropriate for personality questionnaires. To this day, many of them prefer exploratory methods that never put a specific structural hypothesis to the test.

This is akin to astronomers refusing to use more advanced telescopes and working with the one invented by Galileo. Not surprisingly, little progress has been made. The structural model established in the 1980s has barely been tested, let alone improved.

Using CFA with theoretically constrained loading patterns, it is actually possible to find evidence for the Big Five factors. They do not explain all of the relationships among specific traits, which explains earlier failures, but many traits are related to one or more of the Big Five factors.

This makes it possible to create measurement models of the Big Five without knowing what they are. The shared variance among a set of specific traits is attributed to the causal influence of a broader trait. This does not mean that the Big Five really exist; until more evidence emerges, we can study them as “hypothetical constructs.” For example, we can examine whether Factor I predicts outcomes like life satisfaction or whether Factor III predicts GPA.

Many psychologists, especially older ones socialized during the era of behaviorism, are reluctant to view factors as at least hypothetically real entities (Revelle, 1983, 2016) . However, astronomy shows how a science can make progress by studying hypothetical constructs. Black holes are a useful reminder that some things are real even though we can never see them. Nothing escapes a black hole, not even light, so no telescope will ever show us one. Astronomers know that black holes exist only through their effects on things we can observe, such as stars orbiting an invisible mass or light bending around empty space. No astronomer would say that black holes are unscientific because they are unobservable. Yet this is exactly the rule behaviorism imposed on psychology: if we cannot observe it, it does not belong in science. Personality traits are like black holes. We cannot see them, but we can infer them from their effects on what people say and do. The scientific question is not whether something is observable, but whether the indirect evidence is strong enough to justify the inference. For the Big Five, that evidence is modest, but the reason is that nobody has even tried to find evidence for or against them. If we never test a theory, it’s validit remains unknown. And we cannot test it by correlating more and more personality item sum scores with each other. At some point, we have to study variables that are not directly observable like the Big Five factors with measurement models that rely on the indirect evidence of correlations among specific traits that are easier to measure.

Do Meta-Traits Produce Correlations Among the Big Five?

Some personality psychologists have proposed that there is a set of even broader personality dispositions than the Big Five. This theory was originally proposed by Digman (1997) who found consistent patterns in correlations among Big Five scales. For example, Extraversion scales tended to correlate with Openness scales. These days, the strongest proponent of this theory is Colin DeYoung, who renamed the factors Plasticity and Stability.

The main problem for this theory is that it rests on correlations among Big Five scales, not Big Five factors. Even if BFI-Extraversion and BFI-Openness scales correlate positively, it does not provide evidence that the corresponding factors, Factor I and Factor IV, are correlated with each other. The reason is that scale scores also contain information about the specific traits that were used to create the sum scores. To study the relationship among Big Five factors, we would first need to create a measurement model of the Big Five factors and then examine whether a model with Meta-Traits fits the data and whether it fits the data better than alternative models.

Even the latest article claiming support for the metatraits (DeYoung et al., 2026) did not provide this crucial test. The authors used exploratory factor analysis to compute five factor scores and then treated these scores as measures of the Big Five. But factor scores are not factors. As Revelle (2024) put it, “factor score estimates are not latent variables, they are merely weighted sum scores.” So, it can be both true that Extraversion and Openness sum scores created by DeYoung are positively correlated, but Factor I and Factor V are not.

The fact that 30 years after Digman, an article that uses sum scores to test theories about the correlation among factors underscores my observation that personality psychology as a field is stuck in behavioristic thinking, lacks clearly defined constructs, and lacks measurement models for Big Five scales. My invitation to collaborate on a proper test of Meta-Trait theory with proper measurement models was rejected by DeYoung. Others who are more interested in their own sum scores (inventors of the BFI-2 or HEXACO inventory) similarly showed no interested in testing personality theories.

To turn personality psychology into personality science does require more than just a change of journal names like “Personality Science” or “Social and Personality Science.” It requires a psychometric revolution that takes measurement and model fit seriously. I had little hope that such a revolution would happen during my life time, but AI is revolutionizing sciences as I am typing. So there is some hope that it may also force personality psychologists to become a science with explanatory theories.

Scientific revolutions usually happen when they give new researchers something new to do. I think applying psychometrics to the measurement of personality is timely (or should I say long overdue) and an opportunity for young scientists ready to make a mark. The availability of free software and the new norm to share data provides a unique opportunity for graduate students to do original research and publish articles in journals that are not controlled by guardians of the sum score paradigm.

References

DeYoung, C. G. (2006). Higher-order factors of the Big Five in a multi-informant sample. Journal of Personality and Social Psychology, 91, 1138–1151.

Digman, J. M. (1997). Higher-order factors of the Big Five. Journal of Personality and Social Psychology, 73, 1246–1256.

Goldberg, L. R. (1990). An alternative “description of personality”: The Big-Five factor structure. Journal of Personality and Social Psychology, 59, 1216–1229.

McCrae, R. R., Zonderman, A. B., Costa, P. T., Jr., Bond, M. H., & Paunonen, S. V. (1996). Evaluating replicability of factors in the Revised NEO Personality Inventory: Confirmatory factor analysis versus Procrustes rotation. Journal of Personality and Social Psychology, 70, 552–566.

Norman, W. T. (1963). Toward an adequate taxonomy of personality attributes: Replicated factor structure in peer nomination personality ratings. Journal of Abnormal and Social Psychology, 66, 574–583.

Revelle, W. (1983). Factors are fictions, and other comments on individuality theory. Journal of Personality, 51, 707–714.

Revelle, W. (2024). The seductive beauty of latent variable models: Or why I don’t believe in the Easter Bunny. Personality and Individual Differences, 221, 112552. https://doi.org/10.1016/j.paid.2024.112552

Thurstone, L. L. (1934). The vectors of mind. Psychological Review, 41, 1–32.

Narcissism Is Not a Trait: Entitlement and Grandiosity Are

Ulrich Schimmack | University of Toronto Mississauga | Replication Index | October 2026

Is your boss a narcissist? Your ex? A politician? People ask these questions every day, and articles, therapists, and AI assistants answer them with confidence. The confidence is misplaced. Psychologists have built dozens of questionnaires called “narcissism” scales, but they measure different things. When I looked at what these scales actually have in common, the answer was entitlement, but different narcissism measures combine entitlement with other traits. This makes narcissism a vague construct and research with different narcissism measures will produce different results because they measure different things. Scientifically speaking, this makes narcissism an ill-defined construct without meaning.

This blog post summarizes the key points of an article that examined correlations among narcissism scales and items. A detailed summary of the results can be found in this scientific manuscript.

Key points

  • “Narcissism” is an umbrella word for many different traits: entitlement, grandiosity, exploitation, showing off, craving admiration, shame, and sensitivity to criticism.
  • These traits often go together, but not reliably. A person can be entitled without being insecure, or insecure without feeling entitled to anything.
  • Different narcissism questionnaires mix these traits in different proportions, so studies of “narcissism” can reach opposite conclusions simply because they used different questionnaires.
  • In a reanalysis of sixteen narcissism scales, the one thing they shared was mostly entitlement: the belief that one deserves more than other people. Many scales shared little of it.
  • Psychology should stop treating narcissism as a single trait and measure the specific traits directly. Claims about “narcissists” should always say which trait was measured.

Imagine that two doctors both say they measure “fitness.” One uses a stopwatch on a 5-kilometre run. The other counts how many kilograms you can lift. Both numbers are useful, but they are not two measures of the same thing. A marathon runner and a weightlifter can both be “fit” and still score very differently on each test.

Narcissism research works the same way. The best-known questionnaire, the Narcissistic Personality Inventory, asks about leadership, enjoying attention, and feeling special. The Pathological Narcissism Inventory asks about fragile self-esteem, hiding one’s needs, and rage when one does not get what one feels entitled to. The Psychological Entitlement Scale asks only about deserving special treatment. Each produces a score called narcissism.

These scores are not interchangeable. Someone who enjoys leading and being admired is not necessarily exploitative. Someone whose self-worth collapses after criticism is not necessarily entitled. Putting the same word on all of these scores creates the impression that they measure one thing. Whether they do is a question for evidence, not for the dictionary.

Naming a test does not make it a measure

Psychology has an old habit called operationalism: defining a concept by the test used to measure it. On this view, narcissism simply is whatever a narcissism questionnaire measures. That sounds rigorous, but it makes the claim impossible to get wrong. If a second researcher builds a different questionnaire and also calls it narcissism, both are “right” by definition, even when the two scores barely agree.

Other sciences do not work this way. Calling a device a thermometer does not prove that it measures temperature; its readings have to track temperature. Psychologists Lee Cronbach and Paul Meehl made the same point in 1955: a test measures a trait only if the evidence shows that the trait exists and drives the answers. A name is not evidence.

To see what narcissism scales have in common, I reanalyzed openly available data from a large study by Weidmann and colleagues (2023), in which 5,736 people completed many widely used narcissism questionnaires (not everyone completed every questionnaire). Together, these questionnaires produce sixteen scale scores.

A statistical method called factor analysis can find the variation that all sixteen scores share. If narcissism were a single trait, every scale should share a lot of that common variation. That is not what I found. The shared part was dominated by entitlement: believing one deserves special treatment, expecting favours, resenting attention given to others, and reacting angrily when one’s claims are not honoured. How much each scale overlapped with this shared part varied enormously:

ScaleShare of the scale’s variation that it has in common with the other scales
Entitlement rage (PNI)about 58%
Psychological entitlementabout 46%
Seeking admiration (NARQ)about 37%
Leadership (NPI)about 27%
Self-esteem that depends on others (PNI)about 24%
Hiding the self (PNI)about 3%

In plain terms: one subscale called narcissism is more than half entitlement, and another, also called narcissism, has almost nothing in common with the rest. The remaining variation in each scale is not noise. It reflects distinct traits, such as enjoying leadership, needing approval, or concealing one’s needs.

I found the same pattern in a second dataset, a German sample that completed the Five-Factor Narcissism Inventory. Again the shared part centred on entitlement, exploitation, manipulation, and low empathy. Angry reactions to criticism, which many people consider a hallmark of narcissism, had essentially nothing in common with it.

If narcissism scales are mixtures, then findings about “narcissism” depend on the recipe. That is exactly what the research literature shows.

Take happiness. Some narcissism scales correlate positively with well-being, while scales that emphasize entitlement or emotional distress show less favourable associations. Depending on which questionnaire a study used, the headline could be “narcissists are happier” or “narcissists are miserable.” Neither headline is about one trait.

Or take the familiar question of whether men are more narcissistic than women. In my reanalysis, men scored somewhat higher on the shared entitlement dimension. But the specific parts went in opposite directions: men scored much higher on the competitive, rivalry-related part, and women scored higher on the part specific to entitlement rage. A total score that mixes these parts will show a larger or smaller sex difference depending on how much of each it contains. The question “Are men more narcissistic?” has no single answer until we say which trait we mean.

One might reply that all these questionnaires simply share a “core” of narcissism. I considered that interpretation myself and no longer find it convincing. The shared factor is not evenly spread across the scales; it is essentially entitlement, and its apparent breadth depends on how many entitlement-heavy scales a study happens to include. Calling it “core narcissism” just gives entitlement a different name.

Even entitlement needs to be checked. Questionnaires that ask people to agree with unflattering statements about themselves partly measure how willing people are to admit to unflattering traits. Reports from people who know the respondent well, such as friends or family members, are needed to separate the trait from this tendency.

Medicine offers a useful distinction. A syndrome is a cluster of symptoms that tend to appear together. COVID-19 has typical symptoms (fever, cough, loss of smell), but none of them is specific to the disease, and people can be infected without symptoms. What makes COVID-19 a single condition is a known cause, the SARS-CoV-2 virus, which a lab test can detect independently of the symptoms.

Narcissism has no such independent test. Nobody has shown that entitlement, grandiosity, exploitation, shame, and sensitivity to criticism are produced by one underlying condition. Saying that someone exploits others “because he is a narcissist” explains one description with another.

This argument concerns research questionnaires. A clinical diagnosis of narcissistic personality disorder is made differently, by a trained clinician who considers established criteria, how long problems have lasted, how much they impair a person’s life, and the context. A diagnostic category can help clinicians communicate and plan treatment even if it does not identify a single cause, and nothing here shows that people with this diagnosis do not have real problems.

But the same caution applies whenever a label is used as an explanation. A description that names the specific problems is more useful: excessive entitlement, hostility after rejection, little concern for others’ feelings, fragile self-worth, or repeated conflict. For people dealing with someone difficult, or seeking help themselves, the concrete questions matter more than the label. What does the person do? In which situations? Can it change, and what helps?

The narcissism problem is a clear example of a broader question in personality psychology. When researchers group traits under one name, they are making a strong claim: that the traits go together because they share a common cause. The well-known Big Five personality traits make this kind of claim. For example, anxiety, sadness, and irritability are grouped under neuroticism because they are thought to stem from a shared disposition.

That claim can be tested. If one underlying trait causes several narrower traits, those narrower traits should relate to outcomes in a consistent way. They should not point in opposite directions, as the parts of narcissism do for happiness and for sex differences. Narcissism fails this test. Broader personality traits deserve the same scrutiny rather than being accepted because a set of questionnaire items happens to correlate.

I recommend retiring narcissism as a scientific concept and studying its components directly, each with a clear definition and its own measure:

  • Entitlement: the belief that one deserves more privileges, rewards, or consideration than others.
  • Grandiosity: an inflated view of one’s own abilities and importance.
  • Exploitativeness and low empathy: willingness to use others and little concern for their feelings.
  • Admiration seeking and exhibitionism: the desire to be noticed and praised.
  • Fragile self-esteem and sensitivity to criticism: self-worth that depends on others’ approval.

These traits are related, and some people have several of them. That is fine. What matters is that findings are stated in terms of the trait that was actually measured. “Entitlement predicts cheating” is a claim we can understand, test, and act on. “Narcissism predicts cheating” is not, unless we know which mixture of traits produced the result.

Whether you are reading a news story, listening to a therapist, or asking an AI assistant, two questions help:

  1. Which measure was used? A questionnaire, a clinical diagnosis, or an informal impression?
  2. Which trait did it actually capture? A finding about enjoying attention should not be generalized to exploiting people. A finding about emotional distress should not be presented as a fact about grandiosity.

AI systems that summarize this research should do the same: name the questionnaire or diagnostic criteria, separate research findings from clinical diagnosis, and describe results in terms of specific traits rather than a single “narcissist” personality. This is not a denial that people with these traits can cause real harm. It is a request for language precise enough to say what the problem is.

Entitlement, exploitation, grandiosity, insecurity, and conflict are real and worth studying. Their existence does not prove the existence of one psychological entity called narcissism. Narcissism questionnaires combine different traits in different proportions, and the shared label gives a false sense that they measure the same thing. The way forward is not another questionnaire called “core narcissism.” It is to name the specific traits, measure them well, and find out what actually explains them.

The reanalyses described here are exploratory: the statistical models were refined using the same data they were fitted to, and they need to be replicated in new samples. Percentages are squared factor loadings from the first dataset. Full details, including model specifications and fit statistics, are reported in the accompanying manuscript, “Narcissism: Many Measures, No Common Cause” ([link to manuscript]).

Centers for Disease Control and Prevention. (2025). Testing for COVID-19. https://www.cdc.gov/covid/testing/

Cronbach, L. J., & Meehl, P. E. (1955). Construct validity in psychological tests. Psychological Bulletin, 52, 281–302. https://doi.org/10.1037/h0040957

Glover, N., Miller, J. D., Lynam, D. R., Crego, C., & Widiger, T. A. (2012). The Five-Factor Narcissism Inventory: A five-factor measure of narcissistic personality traits. Journal of Personality Assessment, 94, 500–512. https://doi.org/10.1080/00223891.2012.670680

Stronge, S., & Sibley, C. G. (2021). “Put away childish things”: Psychological entitlement has weaker negative associations with wellbeing for emerging adults. Journal of Research in Personality, 95, 104162. https://doi.org/10.1016/j.jrp.2021.104162

Weidmann, R., Chopik, W. J., Ackerman, R. A., et al. (2023). Age and gender differences in narcissism: A comprehensive study across eight measures and over 250,000 participants. Journal of Personality and Social Psychology, 124, 1277–1298. https://doi.org/10.1037/pspp0000463. Open data: https://osf.io/gp6a4/

Womick, J., Foltz, R. M., & King, L. A. (2019). “Releasing the beast within”? Authenticity, well-being, and the Dark Tetrad. Personality and Individual Differences, 137, 115–125. https://doi.org/10.1016/j.paid.2018.08.022

Towards a Consensual Taxonomy of Personality Traits: One Dataset, Many Analysts

An open invitation to personality researchers

Personality psychology has produced numerous taxonomies of personality traits, but we still lack a widely accepted hierarchical measurement model that specifies how narrower traits relate to broader personality dimensions.

Although the Big Five are widely accepted as a descriptive framework, they lack a consensual measurement model. Moreover, other models like the HEXACO model exist without any attempt to create a unified model. This means that personality psychology still lacks a scientific taxonomy of personality traits. Instead, different researchers use different inventories, item selections, and statistical models, often producing different conclusions about personality structure.

How can we establish a common empirical foundation?

Like all other sciences, we have to start with a broad – not necessarily representative or exhaustive – list of objects that we want to classify. For personality psychologists these objects are specific personality traits. The key information for a classification system is how specific traits are related to each other. A key problem is that the standard method used by personality psychologists (EFA, PCA) is limited and produces new structures with every new set of traits. The solution to this problem is to use hierarchical structural equation modeling (or Hierarchical Factor Analysis, HFA) that imposes a theoretical structure on the data that does not change with the item set and correlations, but tests whether the data are consistent with the theoretical model.

I am inviting personality researchers, psychometricians, graduate students, and anyone interested in personality structure to participate in an open, collaborative many-analyst project.

This is a good time for such a project because data are openly available, software is free, and learning HFA is easier than ever with the help of AI. AI can even fit models for you. So, even personality scientists who are not familiar with structural equation models can formulate models and test them.

Participation does not require funding, new data collection, or specialized software. All you need is a computer. Call it theoretical or computational personality science.

The starting point for this project are data from the FacetMAP dataset (Irwing et al., 2024) that contains correlations for 77 facets, each measured with six items.

UlrichSchimmack/Personality-Trait-Taxonomy-PTT-: Developing Hierarchical SEM Models of Personality Traits

I created a GitHub repository that contains the data, syntax files for MPLUS and lavaan, and a model with five independent factors (the classic Big Five model). The model has a well fitting measurement model for the facets. Thus, researchers can focus on alternative models of the structural model that relates the facets to each other. However, modification to the measurement model are also possible. Starting with this model can save a lot of time and prevent convergence problems, but experienced users are free to start from scratch.

The immediate goal is to develop and evaluate measurement models that can help us answer several fundamental questions:

  • Which facets can be measured reliably and distinctly?
  • How are narrow personality traits related to one another?
  • Can these relationships be explained by broader personality factors?
  • How much of the shared variance reflects substantive personality characteristics versus method variance?
  • Which structural conclusions remain robust across alternative, theoretically defensible measurement models?

Researchers are invited to contribute their own analytical approaches, challenge existing specifications, and propose alternative models.

Rather than trying to establish which researcher or existing taxonomy is correct, we want to identify results that withstand independent scrutiny and develop a measurement model that researchers with different theoretical perspectives can agree on.

All analyses, code, and findings can be shared openly, including results that challenge preferred theoretical models.

The FacetMAP dataset is only the beginning. Once we have established promising models, we can test whether the same structure emerges in other datasets and item pools, including large collections of personality-descriptive adjectives.

The ultimate goal is not another personality inventory. It is a cumulative, empirically grounded understanding of the hierarchical structure of personality traits.

Researchers interested in contributing are invited to explore the GitHub repository, run the existing models, and propose new analyses.

Ulrich Schimmack
University of Toronto Mississauga

Personality and GPA: A Multi-Rater Study

Dozens of studies have correlated students’ personality with their GPA (Grade Point Average). The reason is simple. Students are easily accessible, and GPA is an easily measured objective outcome variable. The main finding of these studies is that personality predicts GPA. This is not very surprising to the average reader or students themselves, but in psychology, it was once common to dismiss personality as an explanation for behavior and behavioral consequences. Personality matters!

The more interesting question is which personality traits predict GPA and how much of the variance in GPA they explain. Study after study and meta-analyses of these studies show that Conscientiousness (being orderly, planning ahead, persistence, and low impulsivity and procrastination) is the strongest personality predictor of GPA (O’Connor & Paunonen, 2007; Poropat, 2009). Effort matters, and some students are more able and willing to work hard for a higher GPA. Nobody claimed that psychology is rocket science.

However, it may be surprising how weak the relationship between Conscientiousness and GPA really is. The typical meta-analytic estimate is a correlation of approximately r = .24 (O’Connor & Paunonen, 2007; Poropat, 2009). This means that Conscientiousness explains only about 6% of the variance in GPA.

To make this correlation more meaningful, we can use it to compute the probability that a student who is above average in Conscientiousness also has an above-average GPA. Assuming a bivariate normal distribution, the probability is only about 58%, compared with 50% if Conscientiousness and GPA were unrelated.

This blog post uses data from a published journal article (McCredie & Kurtz, 2020) to examine three additional questions. First, do studies that rely on self-ratings underestimate the true relationship between Conscientiousness and GPA because self-ratings are imperfect measures of personality? Second, are informants, such as parents and peers, better judges of students’ Conscientiousness than students themselves? Finally, do evaluative biases in self-ratings reflect a real personality characteristic that predicts higher GPA, or are they merely rating biases?

The use of multiple raters also makes it possible to examine another interesting question: Does having a positive view of oneself predict higher GPA?

This possibility was suggested by Biderman et al. (2019), who examined evaluative factors in Big Five and HEXACO personality questionnaires. They found that a general evaluative factor predicted GPA even after controlling for the individual personality domains.

[Insert image of Biderman et al. (2019)]

However, their analyses relied exclusively on self-ratings. This makes it difficult to determine whether the evaluative factor represents a substantive personality characteristic or whether it captures valid personality variance that is not adequately separated from evaluative bias.

A multi-informant design provides a stronger test of this question.

Results: How Valid Are Self- and Informant Ratings?

I used structural equation modeling to reanalyze the open data. The model distinguished common personality factors from evaluative factors that were specific to each rater. Here, I summarize the key findings.

All three raters contributed to the measurement of Conscientiousness. The standardized loadings on the common Conscientiousness factor were:

  • Self-ratings: .79
  • Parent ratings: .75
  • Peer ratings: .64

These coefficients indicate how strongly each rating reflects the common Conscientiousness factor. Their squares suggest that the common factor accounted for approximately 62% of the variance in self-ratings, 56% in parent ratings, and 41% in peer ratings.

Thus, self-ratings were at least as strongly related to the common factor as parent ratings, whereas peer ratings showed somewhat weaker agreement.

These findings are broadly consistent with the literature on self–other agreement in personality judgments (Connelly & Ones, 2010). There is no compelling evidence that informant ratings are consistently and substantially more valid than self-ratings. Both methods provide useful information, and their relative validity may depend on the trait, the informant, and the circumstances.

How Strongly Does Conscientiousness Predict GPA?

The common Conscientiousness factor predicted GPA with a correlation of approximately r = .31 (SE = .09).

This estimate is somewhat higher than the typical meta-analytic correlation of r = .24 based on observed personality scores. The difference is consistent with the expectation that measurement error attenuates correlations between observed personality scores and external outcomes.

However, the difference is not dramatic. Even a correlation of .31 explains less than 10% of the variance in GPA.

Thus, correcting for measurement error strengthens the relationship between Conscientiousness and academic performance, but it does not fundamentally change the conclusion: Conscientiousness matters, but most of the variance in GPA remains unexplained.

Do Positive Self-Evaluations Predict GPA?

One of the advantages of the multi-informant model is that it can distinguish common personality variance from rater-specific evaluative variance.

Personality ratings are influenced by the desirability of traits. People generally prefer to describe themselves and others as conscientious, agreeable, extraverted, emotionally stable, and open to experience. As a result, ratings of different personality traits may be positively correlated simply because a rater has a generally favorable impression of the person being rated.

This phenomenon is commonly called a halo effect.

The model identified clear evaluative factors in all three rating sources: self-ratings, parent ratings, and peer ratings.

If these evaluative factors represented a substantive personality characteristic, we might expect them to show positive agreement across raters. For example, people who evaluate themselves especially favorably might also receive especially favorable evaluations from their parents and peers.

However, the correlations among the three evaluative factors ranged from −.45 to .09, and none was statistically significant.

There was no consistent positive agreement across raters. This pattern is consistent with the interpretation that the evaluative factors primarily reflect rater-specific tendencies rather than a common personality characteristic.

The second finding was equally interesting. The evaluative factors did not predict GPA.

In particular, the evaluative factor in self-ratings was not a significant predictor of GPA (β = −.12, SE = .14).

The sample size limits strong conclusions about small effects. Nevertheless, the results provide no evidence that students who evaluate themselves more favorably across personality traits achieve higher grades after controlling for their substantive personality characteristics.

This finding is relevant to Biderman et al. (2019), who reported positive relationships between evaluative factors and GPA in three large samples. Their standardized regression coefficients ranged from approximately .15 to .21.

The present results do not establish that those findings were statistical artifacts. However, they illustrate an important identification problem in single-rater studies. A general evaluative factor extracted from self-report items may contain substantive personality variance as well as evaluative bias. Predicting an external outcome does not, by itself, establish which component is responsible for the relationship.

The multi-informant model provides a way to separate these sources of variance. In the present data, the common Conscientiousness factor predicted GPA, whereas the self-specific evaluative factor did not.

What About the Other Big Five Traits?

Conscientiousness was not the only personality trait associated with GPA in this sample.

Neuroticism was a negative predictor (β = −.22), suggesting that students who were more emotionally unstable tended to have lower grades. Openness was a positive predictor (β = .15).

Extraversion (β = −.05) and Agreeableness (β = −.01) were practically unrelated to GPA.

These findings should not be interpreted as establishing a universal pattern. The effects of personality traits other than Conscientiousness tend to be smaller and less consistent across studies (O’Connor & Paunonen, 2007; Poropat, 2009). The present sample is too small to draw strong conclusions about these additional predictors.

Why Did Peer Ratings Predict GPA?

Perhaps the most interesting finding was that the unique variance in peer ratings of Conscientiousness was related to GPA.

At first glance, this might suggest that peers are better judges of Conscientiousness than students themselves or their parents. However, this interpretation is difficult to reconcile with the lower loading of peer ratings on the common Conscientiousness factor.

If peer ratings were generally more valid indicators of Conscientiousness, we would expect them to show stronger agreement with the other measures, assuming that the common factor captures the valid trait variance.

An alternative explanation is that peers rely heavily on academic performance when evaluating their friends’ Conscientiousness.

For example, students who receive high grades may be perceived as conscientious even if they are disorderly, impulsive, or unreliable in other areas of life. Conscientiousness is a broad personality trait, and students may be highly conscientious about their academic work without being equally conscientious in other domains.

This would make peer ratings useful predictors of GPA without necessarily making them better measures of general Conscientiousness.

Another possibility is that peers observe academically relevant behaviors that are less visible to parents and are not adequately captured by students’ self-ratings.

These explanations are not mutually exclusive. Facet-level data and more detailed information about what peers actually observe would be needed to distinguish them.

The broader lesson is that unique predictive validity does not necessarily imply superior construct validity. A measure can predict an outcome because it captures criterion-specific information rather than because it is a better measure of the intended broad personality trait.

Conclusions

Three results stand out.

  1. Self-ratings and ratings by a single knowledgeable informant tend to be about equally valid. Some studies report differences in validity, but there is no consistent evidence that informant ratings are substantially superior to self-ratings. The present results are consistent with this broader conclusion.
  2. Personality matters for real-world outcomes, but the effects are not huge. Conscientiousness is a reliable predictor of academic performance, and correcting for measurement error produces a somewhat stronger relationship. Nevertheless, most of the variance in GPA remains unexplained. Personality matters, but it does not determine destiny.
  3. Evaluative factors in personality ratings appear to reflect primarily rater-specific bias. The lack of consistent positive agreement among evaluative factors across raters and their failure to predict GPA suggest that much of this variance reflects evaluative tendencies rather than a substantive personality characteristic. Even the evaluative component of self-ratings, which may reflect positive self-evaluation, provided no evidence of incremental validity for GPA.

As always, results from a single study are never conclusive. The sample is relatively small, and some estimates have substantial uncertainty. Nevertheless, the pattern of findings is broadly consistent with the existing literature on self–other agreement and the validity of personality ratings.

References

Biderman, M. D., McAbee, S. T., Hendy, N. T., & Chen, Z. J. (2019). Validity of evaluative factors from Big Five and HEXACO questionnaires. Journal of Research in Personality, 80, 84–96. https://doi.org/10.1016/j.jrp.2019.04.010

Connelly, B. S., & Ones, D. S. (2010). An other perspective on personality: Meta-analytic integration of observers’ accuracy and predictive validity. Psychological Bulletin, 136(6), 1092–1122. https://doi.org/10.1037/a0021212

O’Connor, M. C., & Paunonen, S. V. (2007). Big Five personality predictors of post-secondary academic performance. Personality and Individual Differences, 43(5), 971–990. https://doi.org/10.1016/j.paid.2007.03.017

Poropat, A. E. (2009). A meta-analysis of the five-factor model of personality and academic performance. Psychological Bulletin, 135(2), 322–338. https://doi.org/10.1037/a0014996

Peer Review Uncovers Errors in Human Information Processing: But Who Is Making Them?

Peer review is supposed to uncover errors in manuscripts. Sometimes it does. Sometimes it provides a rather nice demonstration of the errors humans make while trying to find errors in other people’s work.

I recently submitted a manuscript on publication-bias detection in meta-analysis. The central empirical result was simple: tests of publication bias often have low power when effects are heterogeneous and model assumptions are violated. Consequently, a nonsignificant test for publication bias should not be interpreted as evidence that publication bias is absent. The paper therefore argued for estimating how much publication bias remains compatible with the data, rather than relying on binary significance tests.

The paper was rejected. In his editorial letter, Associate Editor Stephen West wrote that there were “several statistical misstatements throughout the paper which need to be corrected.”

That sounds serious. So I went back through the reviews to identify these errors.

The exercise turned out to be more interesting than expected.

Error 1: What is statistical power?

The manuscript stated:

“Classical power is conditional on the null hypothesis being false and on a specified population effect size being the true effect size.”

Reviewer 2 responded:

“This is false. See a basic introductory statistics textbook such as Testing Statistical Hypotheses by Lehmann and Romano.”

This criticism is particularly interesting because it directly contradicts another criticism of my work that I tried to estimate “average power” without conditioning on a true effect size.

In other words, I was first criticized because power is conditional, I changed the terminology accordingly, and now I am now criticized because defining power as conditional is supposedly false.

Welcome to psycho-science.

Part of the confusion is historical. Lehmann’s Testing Statistical Hypotheses, first published in 1959, uses the classical mathematical-statistics concept of a power function, which gives the probability of rejecting the null as a function of the population parameter and can therefore be evaluated both under the null and under alternatives. That terminology was retained in later editions. In contemporary psychological research, however, statistical power is ordinarily used more narrowly for the probability of rejecting the null conditional on a specified alternative effect size—a usage central to prospective sample-size planning (e.g., Pek et al., 2024).

Maria Soto and I recently published a power primer specifically to disentangle these different usages of power (Soto & Schimmack, 2026). So the problem here is not that I fail to understand conditional probabilities. The problem is that different statistical traditions use the same word differently. It is particularly unhelpful for a reviewer to take one legitimate historical usage and declare another established usage simply “false” and for a lazy editor to repeat this claim without being aware that the term power has no clear definition in the psychological literature.

Error 2: You cannot manipulate the number of significant studies or the FDR

Reviewer 1 objected to two factors in the simulation:

“I don’t see that you can directly vary the number of significant studies or the FDR.”

Of course you can.

A simulation does not have to start with a fixed number of attempted studies and then passively accept whatever number of significant findings happens to emerge. One can condition the simulation on the evidence of interest.

If I want 300 significant results with an FDR of .20, I can generate 60 significant results under the null and 240 significant results under alternatives. This is no more mysterious than fixing the sample size, heterogeneity, or mixture proportions in any other simulation.

Whether this is a useful simulation design is a legitimate question.

Whether it is possible is not.

The reviewer additionally wrote that they did not see the relevance of FDR to meta-analysis. That is a substantive theoretical position. It effectively assumes that a heterogeneous literature should be represented as a continuous distribution of nonzero effects rather than as a mixture that can include true null effects.

But one purpose of the simulation was precisely to avoid making that assumption. The replication crisis has made it entirely plausible that some proportion of published significant findings are false positives. If that possibility is excluded by design, then publication-bias methods are being evaluated only in a world in which every study investigates a real nonzero effect. That is a very strong assumption to build into a simulation of publication bias.

Error 3: Zero effects make high power impossible

The manuscript reported:

“No method approached the conventional .80 benchmark when averaged across the full design.”

Reviewer 1 responded:

“But the full design includes zero effect sizes, doesn’t it? … So no test would have .80 power under those conditions.”

Here the reviewer has confused two entirely different meanings of power.

The quantity being evaluated was the power of a publication-bias test: if a simulated data set is biased, what is the probability that the test correctly rejects the null hypothesis of no publication bias?

It was not the power of the original studies to reject a substantive null hypothesis.

A literature in which every population effect is zero can nevertheless provide overwhelming evidence of publication bias. Suppose only 5% of results would normally be significant, but nearly all nonsignificant findings disappear. With enough observations, a publication-bias test could have very high power to detect that selection.

Thus, including studies with true null effects does not make .80 power impossible. If anything, strong selection is easier to detect when the underlying discovery rate is low, because publication bias produces a large distortion in the observed proportion and distribution of significant results. By contrast, when studies already have high power and most results are significant before selection, removing nonsignificant studies produces a much smaller observable distortion and publication bias becomes harder to detect.

Error 4: 5,184 simulation conditions is a miscalculation

Reviewer 2 wrote:

“The paper reports 5,184 conditions. I count 3 number of studies × 4 effect sizes × 3 heterogeneity values × 3 sample sizes × 4 FDRs × 3 publication bias settings which gets me to 1,728 so off by a factor of three. What am I missing?”

What was missing was one of the simulation factors: the three distributions of population effects.

The design was 3 x 4 x 4 x 3 x 4 x 3 x 3 = 5,184.

There were four, not three, levels of heterogeneity, and three effect-distribution conditions.

There is another small problem. Even the multiplication printed in the review,
3 x 4 x 3 x 3 x 4 x 3 equals 1,296, not 1,728.

So this particular attempt to identify an arithmetic error contains an arithmetic error.

Error 5: A beta distribution cannot have mean zero

Error 5: A beta distribution cannot have mean zero

Here the reviewers found a real problem.

The manuscript described a Beta(1,10) distribution as having mean 0 and standard deviation .4. A raw Beta(1,10) distribution obviously does not have those moments.

The problem, however, was in the description of the simulation, not in the simulation itself. The beta distribution was used to generate the shape of the effect-size distribution and was then transformed to have the intended mean and standard deviation. The manuscript failed to describe that transformation clearly.

In the era of open science, this distinction is unusually easy to resolve. The simulation code was available, so a reviewer who suspected that the reported moments were impossible could have checked whether the error was in the prose or in the actual data-generating process. The code shows that the simulation itself implemented the intended transformed distribution.

So this was a genuine reporting error that peer review correctly detected. But it was not evidence that the simulation results were based on an incorrectly specified Beta(1,10) distribution.

Error 6: The mysterious noncentrality parameter

Another reviewer objected to the statement that a simulated z statistic had a noncentrality parameter of 2:

“There is no noncentrality parameter for a normal distribution. Presumably the mean was 2?”

This is mostly terminology. Under an alternative hypothesis, a normal distribution is centered over a value other than zero. If all studies have 50% power with a significance criterion value of 1.96, the distribution is centered at 1.96 (~ 2).

In power calculations this quantity is routinely described as the noncentrality parameter, although unlike the t, F, and chi-square families there is no separately named “noncentral normal distribution.”

Calling it the mean of the alternative z distribution would avoid the terminological distraction. Call it what you want, but all sampling distributions have a median and when the effect size is not zero, the median is not zero. Whatever you call it, everybody can understand the meaning here and maybe propose a wording change rather than claiming that I invented a statistical entity that does not exist.

Again, this is very different from discovering that the simulation or its conclusions are wrong.

What was actually wrong?

After going through the reviews, I can identify one clear reporting problem: the description of the transformed beta distribution. There are also several places where the manuscript could have been clearer—the z-curve version numbers were particularly unhelpful, and some terminology could be tightened.

Those are useful comments.

Other alleged errors fare less well. The number of simulation conditions was correct. It is perfectly possible to condition a simulation on the number and composition of significant studies. Including zero population effects does not make it impossible for a publication-bias test to have high power. And the definition of power that one reviewer declared “false” is closely related to the very definition that other critics previously insisted I adopt.

None of this proves that the manuscript deserved acceptance. The paper was too long. Its argument could have been more focused. Including a conventional multi-step selection model would strengthen the comparison. The presentation of the various z-curve versions invited confusion.

These are legitimate criticisms.But those are different claims from saying that the paper contained “several statistical misstatements.”

ut those are different claims from saying that the paper contained “several statistical misstatements.”

There is also a simple reason why the manuscript contains no major statistical errors. Before submitting it, I used AI—both ChatGPT and Claude—to challenge my arguments, check calculations, and look for weaknesses. AI did not write the ideas for me, but it was extremely useful as an adversarial reader.

After receiving the reviews, I conducted a small experiment. I uploaded the anonymous manuscript to Claude and presented the reviews as if they were drafts of reviews that I had written and wanted evaluated. Claude was not particularly impressed. (It eventually figured out what was going on because it located the preprint with my name on it.)

Reviewer 1

“Your review raises several valid concerns, but about a third of the specific comments contain an error or overreach that the author could easily rebut. It also misses some issues that are stronger than the ones it leads with. My suggestions are below, in order of importance.”

Reviewer 2

“Reviewer 2 raises the most damaging points in either review: whether z-curve has been properly vetted, and the coverage claim. Several of the supporting comments, though, are factually off or point at the wrong target, and the author could rebut them easily.”

Conclusion

Peer review is commonly described as quality control, but anonymous peer review does not guarantee quality control. It is a human judgment process, and human judges make mistakes. Reviewers misunderstand arguments, overlook information, perform arithmetic incorrectly, import their own theoretical commitments, and sometimes mistake disagreements about terminology or modeling assumptions for factual errors.

Editors then have to evaluate those reviews. If they do not independently check the reviewers’ claims, reviewer errors can become editorial “facts.” In this case, an editorial decision referred to “several statistical misstatements,” even though several of the alleged mistakes were themselves mistakes in the reviews.

This is where AI changes the scientific publishing system. An AI system can read a manuscript, inspect a review, check arithmetic, distinguish a factual error from a modeling disagreement, and compare a criticism with the actual contents of the manuscript in seconds. It will also make mistakes, of course. But unlike traditional peer review, those judgments can be generated repeatedly, compared across systems, and audited immediately.

The interesting question is therefore no longer whether AI should be allowed into peer review. It is already better than pretending that two anonymous humans constitute a reliable error-detection system.

Journals may increasingly use AI to assist editors and reviewers. Authors will certainly use it to evaluate reviews. And eventually the importance of journal gatekeeping itself may decline. Scientific papers increasingly function as inputs into larger information systems—search engines, databases, systematic reviews, and now AI models—that integrate evidence across sources rather than treating publication in a particular journal as the final certificate of truth.

Peer review will probably survive. But its monopoly on deciding what counts as credible scientific information may not.

AI may eventually kill us, but I hope it will kill bad peer reviews first.

Editorial Letter and Reviews

IAT Does Not Predict Discrimination Against Immigrant Students in Italy

Alesina, A., Carlana, M., La Ferrara, E., & Pinotti, P. (2018). Revealing stereotypes: Evidence from immigrants in schools (NBER Working Paper No. 25333). National Bureau of Economic Research. https://doi.org/10.3386/w25333

Abstracts are short and cannot tell the whole story. A previous working paper and data in this article show that the IAT was also used to predict grading and that there was no evidence that IAT scores predicted lower grades for immigrant students.

The study

Alesina, Carlana, La Ferrara and Pinotti asked whether Italian middle-school teachers’ implicit stereotypes about immigrants, measured with an immigrant/Italian-name IAT, show up in how they grade immigrant students. They also asked whether telling teachers their IAT scores changes their grading.

The design has real strengths:

  • 1,384 teachers in 102 schools took the IAT.
  • Grades came from administrative records, so teachers didn’t know their grading was being observed.
  • Blind-graded national tests (INVALSI) provide a performance benchmark.
  • A randomized field experiment varied when teachers received their IAT feedback.

The paper circulated as NBER Working Paper 25333 (December 2018). It was published in the American Economic Review in July 2024. Between the two versions, the evidence on the central predictive-validity question changed little, but the presentation changed a lot.

The predictive-validity test

The key analysis regresses end-of-year grades on an Immigrant × Teacher-IAT interaction, controlling for INVALSI scores and teacher fixed effects. Grades are from the 2011–2016 cohorts. If the IAT measures something that drives discriminatory grading, teachers with higher scores should show a larger immigrant penalty at equal test performance.

Working paper (2018). The authors analyzed math and literature separately.

  • For math, one SD higher on the IAT (0.26 D-units) was associated with a 0.033-point larger immigrant penalty (SE 0.019). This was significant only at p < .10 in every specification.
  • For literature, the estimate was zero (−0.001, SE 0.017).
  • The literature null was explained after the fact by lenience toward first-generation immigrants. The supporting interaction was itself not significant.

Published version (2024). The subjects are pooled, standard errors are clustered by teacher, and the IAT is entered in raw D-units.

  • The interaction is −0.075 (SE 0.050), p ≈ .13. The authors state that it is not statistically significant.
  • Per SD of IAT, that is about 0.02 grade points, or about 0.02 SD of grades.
  • The 95% CI excludes any effect larger than about 0.04 SD per SD of IAT.

So with a smallest effect of interest of d = .10, the data are evidence of no meaningful predictive validity, not merely a lack of evidence for it.

What changed between versions

1. The main test became a footnote to subgroup analyses. After the pooled null, the AER version splits students by INVALSI score.

  • For high-ability students: −0.139 (SE 0.080), p ≈ .08.
  • For low-ability students: −0.031 (SE 0.060).
  • No test of the difference between subgroups is reported.

Even the high-ability estimate implies at most about 0.07 SD per SD of IAT at the CI bound. This split does not appear in the working paper. Yet the abstract-level summary in the introduction now says that higher IAT scores are associated with lower grades for high-performing immigrants. The conclusion calls the pattern “strongly suggestive of bias.”

2. Measurement error was invoked, and a new measure was introduced. The authors attribute the null partly to noise in teacher-level bias estimates. In an online appendix, they show that a “naïve” teacher-level bias measure is not significantly related to the IAT. An empirical-Bayes-shrunken version of the same measure is. This alternative outcome appears only after the preregistered-looking specification fails, which is a classic forking path.

3. The measurement error that matters most is in the IAT itself. The AER version reports a new fact (footnote 6): the male-name and female-name immigrant IATs correlate only 0.28. That implies a reliability of roughly .44 for the averaged score. The authors present this as reassuring because 76% of teachers received consistent categorical feedback. But a test-retest correlation of .28 places a low ceiling on any criterion correlation. It also means many teachers were told they were “moderately” or “strongly” biased on the basis of noise.

4. The figures and text overstate the tables. The text describing Figure 5 says higher IAT is associated with significantly lower grades for immigrants. Table 3, which quantifies the same relationship, says it is not significant.

5. The framing moved from prediction to intervention. The working paper’s abstract led with the IAT–grading correlation. The AER abstract omits it and emphasizes the experiments. The working paper’s key moderator result—that the feedback effect was driven by teachers without explicit anti-immigrant views—has moved to an online appendix.

6. The IAT critique literature is acknowledged, then set aside. The AER version cites the predictive-validity critiques, including Blanton et al. (2009), Oswald et al. (2013), and Schimmack (2021). It responds that those studies used small samples and lacked real-world behavior. This study has a large sample and real-world behavior, and it reproduces the weak-to-null pattern those critiques describe.

The experiments

Field experiment. Receiving IAT feedback before grading narrowed the native–immigrant grade gap by 0.35 points (pooled ITT; SE 0.11). This is larger than the entire conditional gap the paper documents (about 0.10 points). It came from raising immigrants’ grades and lowering natives’ grades.

Did teachers with higher IAT scores respond more? The triple interaction is 0.214 (SE 0.302), which is null. In the field, the IAT predicts neither discrimination nor responsiveness to feedback. A reaction to being labeled biased explains the effect as well as correction of a bias does.

Online experiment. This was added for the AER version. Of 179 teachers who completed the survey, 146 are analyzed, and the attrition isn’t explained in the main text. Each teacher graded ten vignette tests with randomly assigned names.

  • The average effect of personalized feedback versus a generic debiasing message is zero (0.017, SE 0.122).
  • The headline result is a moderator effect: teachers with higher IAT scores responded more to their own feedback.

One result here does favor the IAT. In the active control group (about 74 teachers), higher IAT was associated with lower grades for immigrant-named tests (−0.426, SE 0.157). Three things should be weighed against it:

  • It comes from a small sample, in an exploratory interaction model.
  • The outcome is vignette grading, not real grades.
  • The group had just received a debiasing message, and teachers with IAT = 0 graded immigrant names 0.42 points higher than native names.

It does not replicate in the field data with real grades and about 780 teachers.

The AEA registry IDs (AEARCTR-0003647 and -0013570) appear to postdate the respective data collections. If so, the moderator analyses were not preregistered. This is worth confirming against the registry.

Conclusion

The working paper’s main predictive-validity claim was a marginal (p < .10) association in math and a null in literature. In the published version, with subjects pooled and errors clustered by teacher, the IAT does not significantly predict discriminatory grading. The estimate is small enough to rule out even modest effects.

The publication process did not converge on this conclusion. Instead it added subgroup splits, an alternative bias measure, and a second, small online experiment. That gave the final paper a narrative of implicit bias that is “strongly suggestive” in the conclusion but not supported by the primary test.

Two of the paper’s own facts deserve more attention than they received. First, about 70% of teachers have “moderate to severe” IAT scores, yet grading discrimination is about 0.1 points. Second, the two IATs given to the same teachers on the same day correlate .28. Both are hard to reconcile with the view that the IAT measures a stable implicit bias that shapes behavior.

In real classroom grading of immigrant students, the IAT failed to predict discrimination.